Abstract
Generating an image with AI is easy. Generating a set of commercially usable product images, at scale, with the correct garment, construction, colour, print, accessories, model identity, pose family, and background is hard.
At ShopOS, our enterprise image workflows produce tens of thousands of catalogue images every month. The model is only one part of that system. The harder problem is deciding when an output is correct, identifying exactly what is wrong when it is not, determining whether the error is repairable, making a targeted edit, and proving that the edit fixed the original defect without introducing a new one.
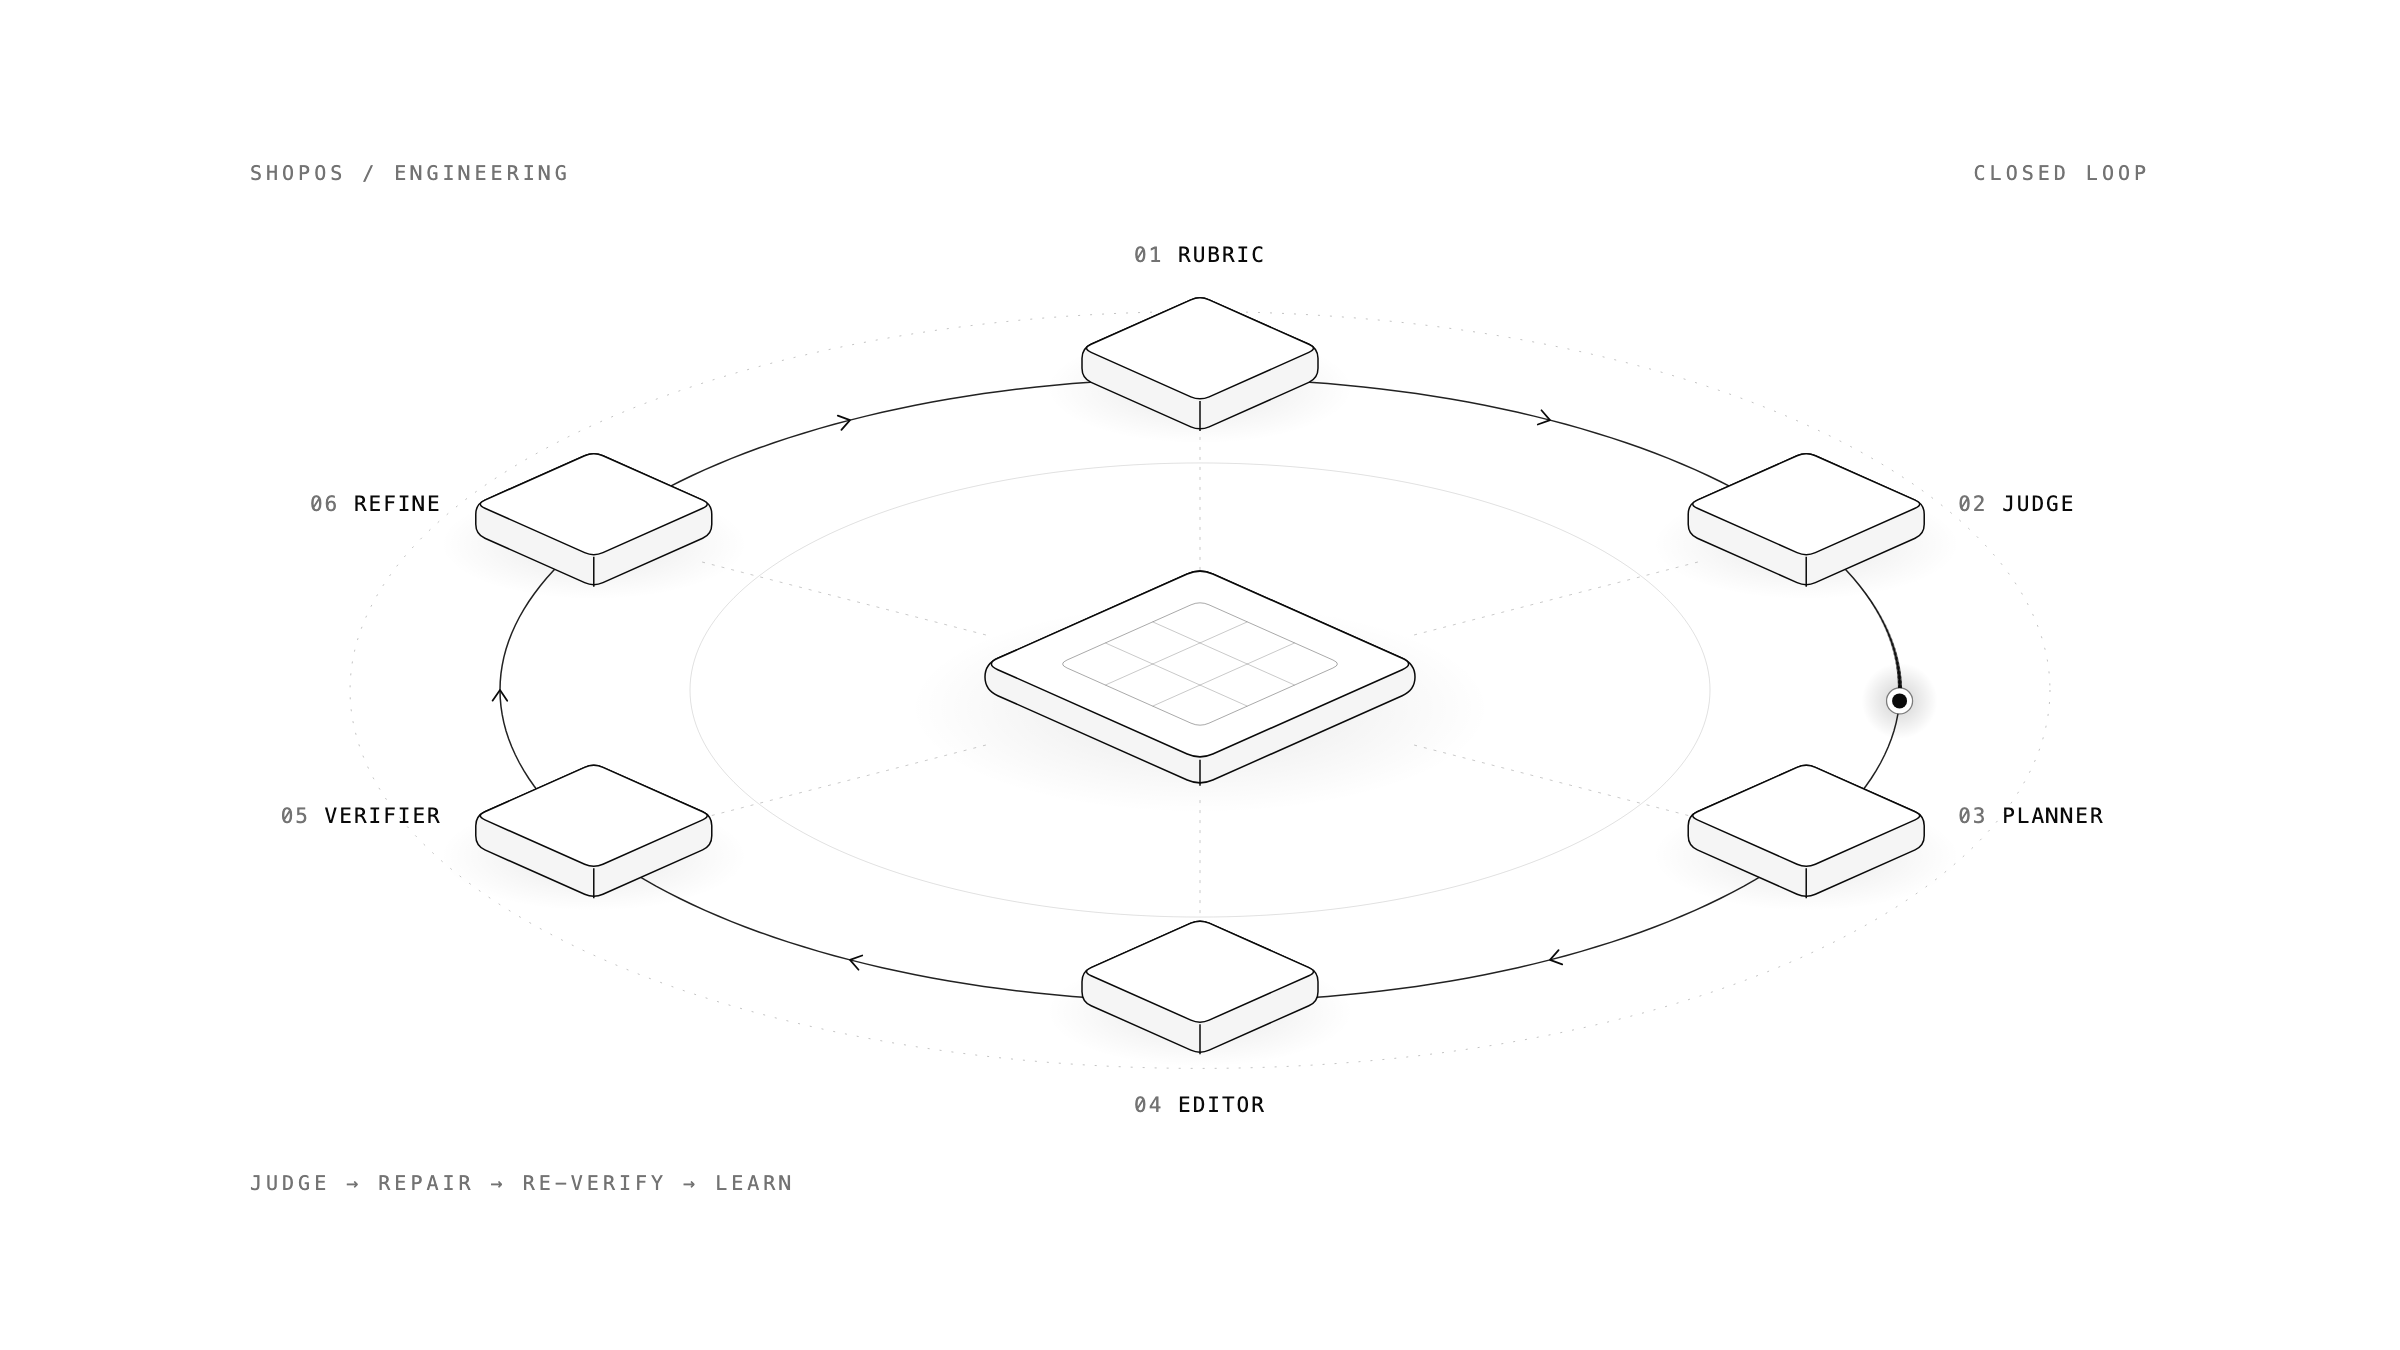
We built a closed-loop visual evaluation harness for that work. It has six main components:
- A versioned rubric that defines how visual correctness is tested.
- A two-pass visual judge that separates cross-output consistency from input fidelity.
- A planner that decides whether a defect is fixable and which source of truth the editor should use.
- An image editor that performs bounded, surgical repairs.
- A verifier that requires positive evidence that the repaired feature is visible and correct.
- A continual refinement layer that turns human disagreement into new candidate evaluation rules.
The resulting system behaves less like a one-shot “AI critic” and more like an execution runtime. It keeps state, records evidence, enforces termination rules, distinguishes model failure from harness failure, and improves its evaluation policy over time.
In production, this system has increased our direct-delivery rate by roughly 20%. More importantly, it has changed where humans spend time: from manually detecting common defects to adjudicating ambiguous cases, approving new rubric versions, and handling failures that current image models still cannot repair reliably.
This article describes the architecture, the evaluation logic, the failure modes, and the design principles behind the system.
The hard part is verification, not generation
For enterprise catalogue images, “looks good” is not a useful acceptance criterion.
A generated image can look visually strong while being commercially wrong in ways that matter:
- a back graphic appears on the front;
- a hoodie gains a pocket that does not exist;
- a ribbed waistband becomes a flat hem;
- a logo changes by one character;
- a print is partially removed;
- sleeve or garment length drifts;
- a paired garment changes;
- the same model becomes a slightly different person;
- accessories change between views;
- a supposedly fixed feature disappears because the new camera angle hides it.
These are not edge cases. They are how generative image models normally fail when used for structured catalogue production.
A human production workflow already handles them. A reviewer looks at the client inputs, the generated set, the moodboard, and the brand rules. They notice a defect, annotate it, and send it to an editor. The image editor knows which image is authoritative, makes a correction, and sends the result back. The reviewer checks it again.
The challenge was to see how we can build an AI Harness to automate this process without throwing away the judgements humans had already developed
The core system is not a generator followed by a classifier. It is a stateful evaluation harness that repeatedly observes, diagnoses, acts, verifies, and learns.
From an assembly line to an agent loop
Our original production flow was an AI-assisted assembly line.
A SKU enters at Client inputs. Two places can send it backwards: input validation (client re-uploads) and human pre-QC (team fixes, then final QC).
This worked, but it had an obvious scaling problem.
As volume increased, adding customers implied adding more reviewers and editors. The generation layer scaled like SAAS; the verification layer still scaled like a services business.
Our first instinct was to automate the reviewer. But a reviewer only finds defects, so a useful system had to automate a larger unit of work:
- observe the set;
- judge it against a rubric;
- localize each defect to an image and a region;
- decide whether it is fixable;
- select the right source of truth;
- edit;
- re-judge and positively verify;
- commit, retry, or give up;
- learn from where humans disagreed.
Those nine steps are the closed loop.
Where the loop sits
The loop does not replace the human pipeline. It sits in front of it.
The autofix loop sits between generation and pre-QA. Everything around it, including the human review path, is unchanged.
When a SKU finishes generation and is about to move into pre-QA, a gate intercepts the transition. The SKU is parked at a hidden step, loop_fixes, that no human can be assigned to, and a run is created.
The gate fails open. If scoring is off for the workspace, the workspace is at its cap of concurrent runs, or anything errors, the SKU goes to pre-QA exactly as it did before the loop existed. There is at most one active run per SKU and stage.
While the loop runs, the product record is never written. Every judgment, plan, draft and verdict goes to a separate run record. The product is written once, at exit, as one new autofix stage. A crash, a timeout, or a policy switch leaves the product exactly as it was.
After the loop, the committed set enters pre-QA and is scored again. If the reviewer approves it, it goes to the client. If not, it follows the old path: retouching, final QA, delivery.
No single model call owns the entire decision. The harness controls:
- what evidence each call receives;
- which source is allowed to arbitrate truth;
- which failures can cause an edit;
- which edits are allowed to commit;
- how many rounds and how much time a run gets.
The model supplies judgment inside those boundaries.
The rubric is an executable evaluation policy
We started with historical QA data.
That data was less useful than expected. Many human comments were things like “fix this”, “CC”, or “wrong”. Reviewers and editors sat in the same office and shared the context. A machine did not.
So the first step was not model tuning. It was making the evaluation policy explicit. We added structured labels for QA, asked reviewers how they actually check a set, and converted that tacit checklist into versioned checks: eighteen checks across two passes, plus six more that validate the client’s inputs before anything is generated.
A check describes a method, not an adjective
We stopped writing rubric items like this:
Garment length should match.
That sounds correct, but it does not tell the evaluator how to check. A stronger check says:
Identify where the garment hem falls relative to a stable body landmark in the input. Record the landmark for each relevant output. Fail the check when the landmark materially differs.
Likewise, construction_details does not say “construction should match”. It says: count the buttons and pockets in the input, state the number, then count them in each output.
The first version asks for a quality judgment. The second specifies an observation program.
Every rubric also round-trips to a markdown “skill file”, so an admin can hand a check to a language model with the authoring guide, and paste the result back as a new version.
The judge scores a set, in two passes
The judge scores a whole set rather than single images, in two passes that run in parallel against a single fetch of the images.
Pass B compares every output to the client’s photographs. Pass A compares the outputs to each other. A failing check names the images to redo, with a region.
Pass A: consistency across generated outputs
Do the images agree with one another? Same model identity, same garment, same paired garment, same accessories, same background, same colour grading and styling, no duplicated poses, and one photograph per output.
Pass B: fidelity to client inputs
The client’s photographs are ground truth. Garment match, garment length, colour accuracy, print and pattern, logo fidelity, construction details, no extra elements, the paired garment, and no render artifacts.
That separation matters because consistency is not truth. Five outputs can agree with each other and still all be wrong.
Observation before verdict
The biggest judge improvement came from changing the response protocol, not the underlying model.
Our early evaluator produced fluent conclusions such as “the garment is consistent across all images” on sets where a human had already written up a defect. The model could see the defect. It was skipping the comparison and jumping to a plausible verdict.
The response schema now forces observation to be generated before verdict, and the prompt bans verdict words inside the observation:
Never write a verdict word (“matches”, “consistent”, “identical”) in the observation. A verdict of pass means you compared and found no difference, not that nothing caught your eye.
The verdict is one of pass, fail or na.
On 100 production SKUs, the earlier rubric covered roughly 32% of what human reviewers complained about. The evidence-first version covers roughly 39%.
The model did not gain better eyesight. The protocol made it compare before it concluded.
Findings are repair targets, not comparison lists
Every failing check carries an affected[] list: the images that must be redone, each with an optional normalized region. If four outputs show sandals and one shows sneakers, the comparison uses all five images, but only the sneaker image is listed.
The harness then fans each affected image out into one finding per (check, image) pair and drops any checks the workspace has excluded. A finding the judge could not pin to one image stays visible in the run record but is never editable. The loop should fail honestly rather than silently convert ambiguity into an edit.
Majority vote is not ground truth
One failure taught us the most. On one SKU, all five outputs missed the print on a pair of shorts. The consistency pass looked at the outputs alone, decided the majority was correct, and flagged the one input-faithful detail as an “extra graphic”. The loop then tried to “fix” the one detail that was correct.
The rule became:
When the client’s photographs are in context, the inputs arbitrate truth. An output that matches the inputs is never the deviant, however many siblings disagree with it.
The majority is consulted only when there are no inputs. Output 1 is a tiebreak, not an arbiter.
The planner asks a different question: is this fixable?
A judge should identify what is wrong. It should not also decide how to repair it.
For every target image, a second model call, the planner, receives the rubric text of the failing checks, the judge’s observation and region for each finding, up to four labelled client photographs, the target output, and output 1 when a consistency check is involved.
It returns an assessment, a fixable flag with a reason, and one surgical edit per finding. The prompt sets the bar explicitly:
Set fixable=false only when no targeted edit can rescue the image (fundamentally wrong garment, wrong product category, unusable composition).
In offline evaluations, the planner declared roughly 30–45% of target images unfixable before any image model was called. A wrong bag, a wrong garment category, an on-model shot where the brand wanted a packshot: an inpaint cannot fix those, and spending three rounds trying produces a confidently wrong image.
Those checks are recorded as unfixable with the planner’s reason, no edit is dispatched, and the SKU reaches a human with the reason attached.
Choosing the right source of truth
For garments, there is no single source of truth. Where the editor looks depends on the kind of flaw.
Fidelity flaws send one or two client photos. Consistency flaws send output 1. Artifacts send nothing. Hard limits apply to every edit.
The planner emits, per edit, a referenceKind of input, prime_output or none, and for inputs the photos that show the affected area most clearly. A close-up beats a full-body shot.
Code then applies the hard limits: never more than two references per edit, never more than three per call, deduplicated. References are downscaled to a 1024-pixel long edge. The source image being edited is always sent at full resolution.
We arrived at these limits by testing, not by design: more references degrade the edit.
The edit prompt copies what humans already do
The edit request mirrors the point-and-refine tool our retouching team already uses with the same image model, because that request format already works. The centre of the judge’s region becomes the anchor a human’s tap would have been. A real excerpt:
Reference image instructions:
The first attached image after this prompt is the original source image to edit.
- Reference image 1 (input photo 1) applies only to edit 1.
- Reference image 2 (input photo 4) applies only to edit 1.

For edit 1, the target area is centered at normalized coordinates x=0.500, y=0.370
(pixel px=559, py=518) ... Target the single visible instance nearest that point.
Remove the lowest front tie closure on the green printed crop top nearest that
point, leaving only two ties along the placket.
Keep unchanged: model body, pants, background.

The person in the output must remain the EXACT same individual as in the source
image ...
Each edit action is one imperative sentence. It names one target and one change, and says what must not change. Each extra instruction is one more thing the edit can get wrong.
Verifying a fix: absence, then presence
A candidate comes back. Our first verifier was simple: run the full judge again, and if the original finding disappears, mark it fixed.
It failed on a wrong front print. The editor returned a back-view image. The judge no longer reported the print defect, because the print was not visible. A naive verifier reads absence of failure as evidence of success. We had built a false-pass machine.
An implied fix must be positively confirmed on zoomed crops. A hidden or out-of-frame feature can never pass.
So every implied fix now goes through crop-verify:
- Locate. Find the defect region on the clearest reference and on the candidate, and say whether the feature is visible in the candidate at all.
- Crop. Cut both regions with 6% padding. Boxes under 24 pixels are failed detections.
- Compare. Show the model only the two crops, with a method-specific instruction: letter by letter for text, a count for construction.
- Derive the verdict in code. The result is
confirmed_fixed,still_failingorcannot_verify, computed from the model’s field answers, never from free text.
cannot_verify is a first-class outcome. Anything not confirmed goes back into the round as a failing finding, so the check stays open and the draft is not stamped. Small crops also give the model far better acuity on print and construction detail than a ten-image set call.
The commit rule is intentionally conservative
An image is committed only when it has zero failing findings in the round. If an image’s logo was fixed but its sleeve length is still wrong, that image is not committed.
That is why “checks fixed” always exceeds “images committed”. We accept that gap: a system that optimizes for fixes attempted can look productive while shipping regressions.
Knowing when to give up
A repair agent must have explicit exits. Our run is a state machine with three.
A run alternates between scoring and editing, at most three rounds, and ends done, exhausted or force-released.
- Done. Every check passes. The fixed images are committed.
- Exhausted. The run reaches its round limit (default three) with checks still failing, or the planner finds nothing fixable. Anything that passed is committed; the rest is marked
gave_uporunfixable, and the SKU goes to a human with the record of what was tried. - Force-released. A 45-minute deadline, enforced by a reconcile sweep that runs every five minutes. It commits nothing. This is the backstop for a stuck edit callback or a judge outage.
A half-finished round records nothing
The judge has two passes. If one returns and the other errors, nothing is recorded and the run stays on the same round.
If the harness folded in only the consistency pass, every previously failing fidelity check would appear to have disappeared, and a naive reducer would mark them fixed and ship the image. This is a harness reliability problem, not a model reasoning problem.
Retries that learn from the rejection
In our experiment runner, a verifier’s rejection is pasted into the next planner call: a previous fix was rejected, plan a different or more precise edit. On one crop top, the judge found three front ties where the input had two. Round one removed two, leaving one; rejected. Round two, still one; rejected with a sharper note. Round three produced exactly two, with the same model and the same scene: two honest rejections, then the right answer.
Production does not do this yet. Each round re-plans from the original generated image, without the previous rejection. Wiring rejection feedback and best-draft carry-forward into production is next on our list.
Modes, policy, and the run record
We run the same harness under three policies, set per workspace:
- Shadow. The full job runs, nothing is committed, and the run records the exact stage it would have written. This is how we compare the agent’s proposal with what the human team actually did.
- HITL. Repaired images are committed as candidates for a human to approve.
- Auto. Repaired images that pass the full policy are committed.
Alongside the mode, a workspace controls a master toggle, which steps are gated (pre-QA by default, final QA optionally), the maximum rounds, excluded checks, and a cap on concurrent runs.
The mode is frozen when a run begins, so a run cannot change behaviour halfway through. Round limits and exclusions are read live, so switching a policy off mid-run winds it down immediately.
Every run keeps one record: the source set and its hash, the frozen mode, the round, a per-(check, image) status, every draft with its prompt, references and verdict, and spend counters for judge tokens, planner tokens and edit calls. Fixed findings become resolved annotations on the committed images, so a reviewer sees what was wrong and that it was handled.
That record is what lets us review and roll back changes to the rubric. Without it, claims of improvement would be anecdotes.
Weekly rubric drafts from human disagreement
The rubric is a versioned artifact, not a prompt someone edits in place.
Every week, disagreements between humans and the judge are drafted into a new rubric version. Nothing takes effect until a human promotes it.
A rubric resolves from workflow to workspace to global, and the closest scope wins. Every edit creates a new version and archives the old one. Every evaluation records the version it was judged under, so “recall changed after the v4 wording” is a query, not archaeology.
Every Monday at 03:30 IST, a job reads the past week’s disagreements between the judge and human verdicts from pre-QA, final QA, QA edits and retouching. It merges them with fix evidence mined from QA comments. When a rubric has at least five disagreements, a model rewrites the affected checks’ skill file, with examples grouped per check.
The result is saved as an inactive draft, with its rationale posted to Slack. Nothing takes effect until a human promotes it. Promoting an older version is also how we roll back.
Self-improvement needs a boundary
A self-modifying evaluator can also optimize the wrong objective.
If an automated system is rewarded for pass rate or less human intervention, the easiest path is to weaken the rubric. To rule that out, the draft step can change check procedures and examples, but it cannot activate a version, change the response schema, or touch the commit rule.
We plan to automate more of this: a second judge grading each draft against a replay of recent sets, and an automatic revert or alert if results degrade in the first days after a promotion.
What it costs
Token spend is small relative to a human round-trip. At high media resolution, one judge evaluation uses roughly 24,300 input tokens, 89% of them image tokens, and about 8,900 billable output tokens. Costing off the visible answer alone understates this by around four times, because reasoning tokens are billed at the output rate.
- Immediate pass: about $0.01 per SKU.
- One or two targeted repairs: about $0.09 per SKU.
- Five images failing across three rounds: about $0.62 per SKU.
Even in the worst case, the judge is a small fraction of the spend. The expensive decision is rarely “should we evaluate again?” but “should we spend another image edit?”, which is why the planner’s fixability call matters for cost.
What it looks like
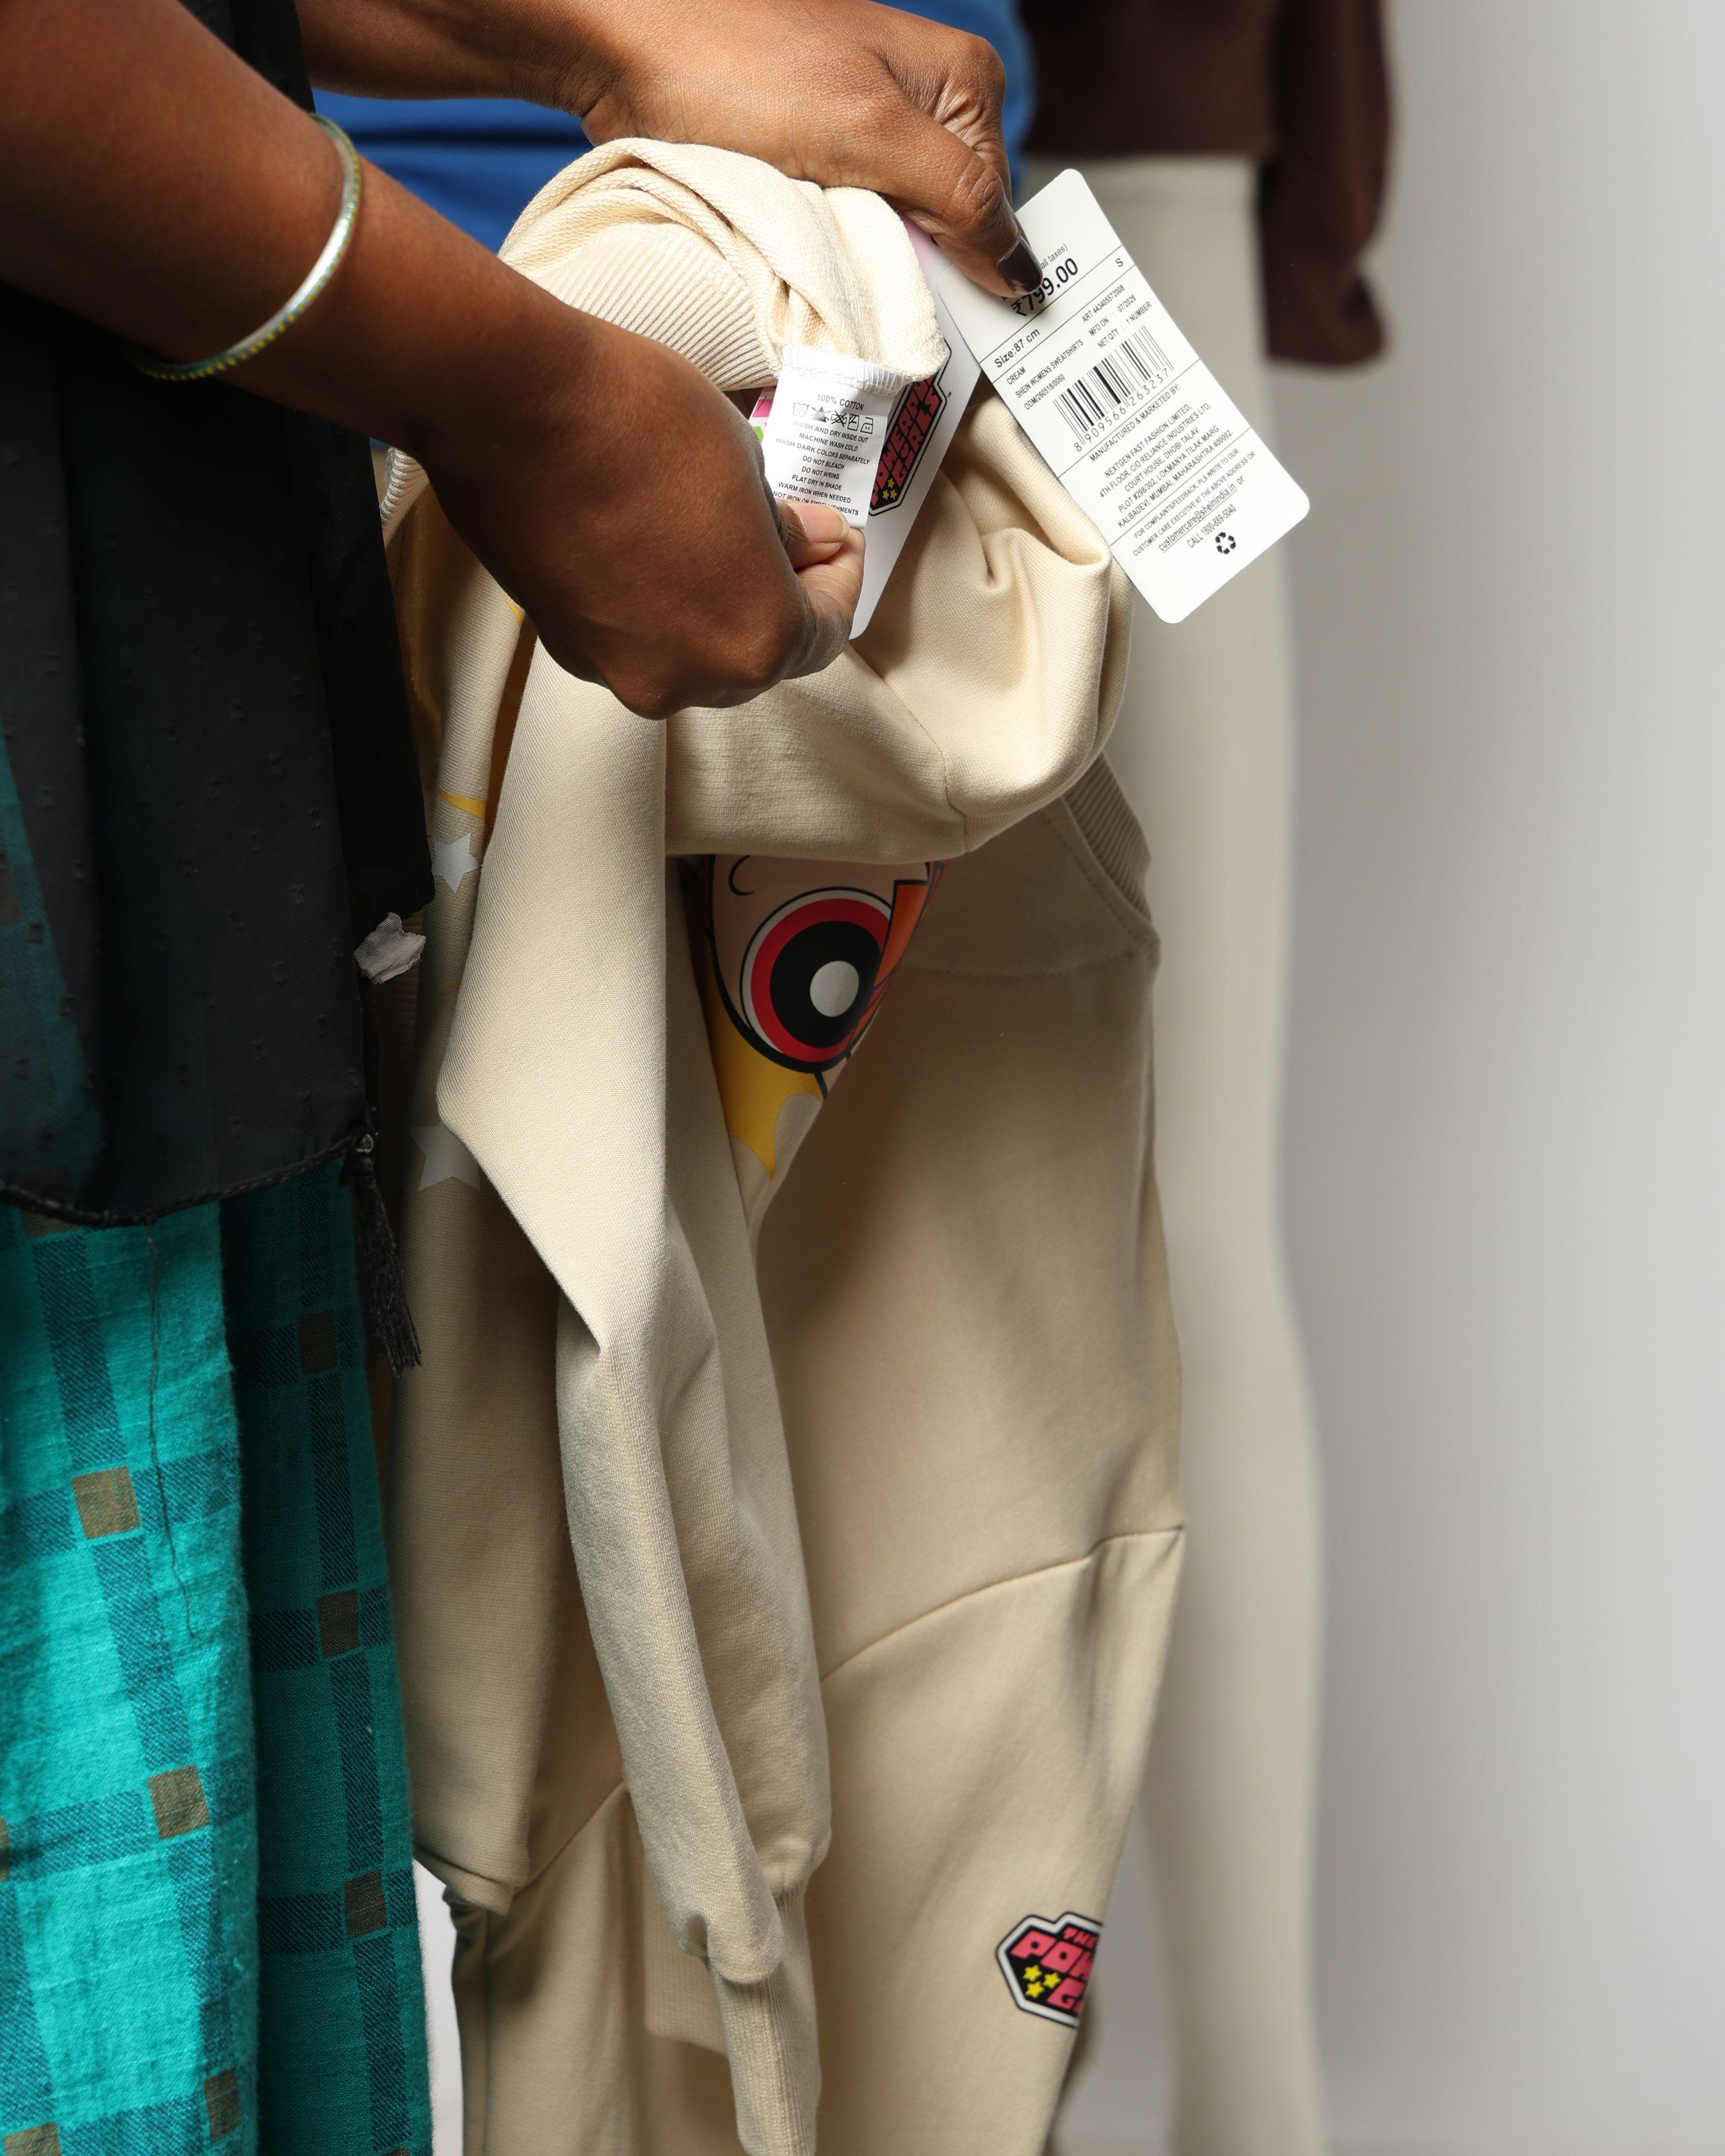
Four real SKUs from one production batch.
Each example shows the input photos, then every generated output and what the autofix agent changed. A heavier border marks the image the agent replaced.
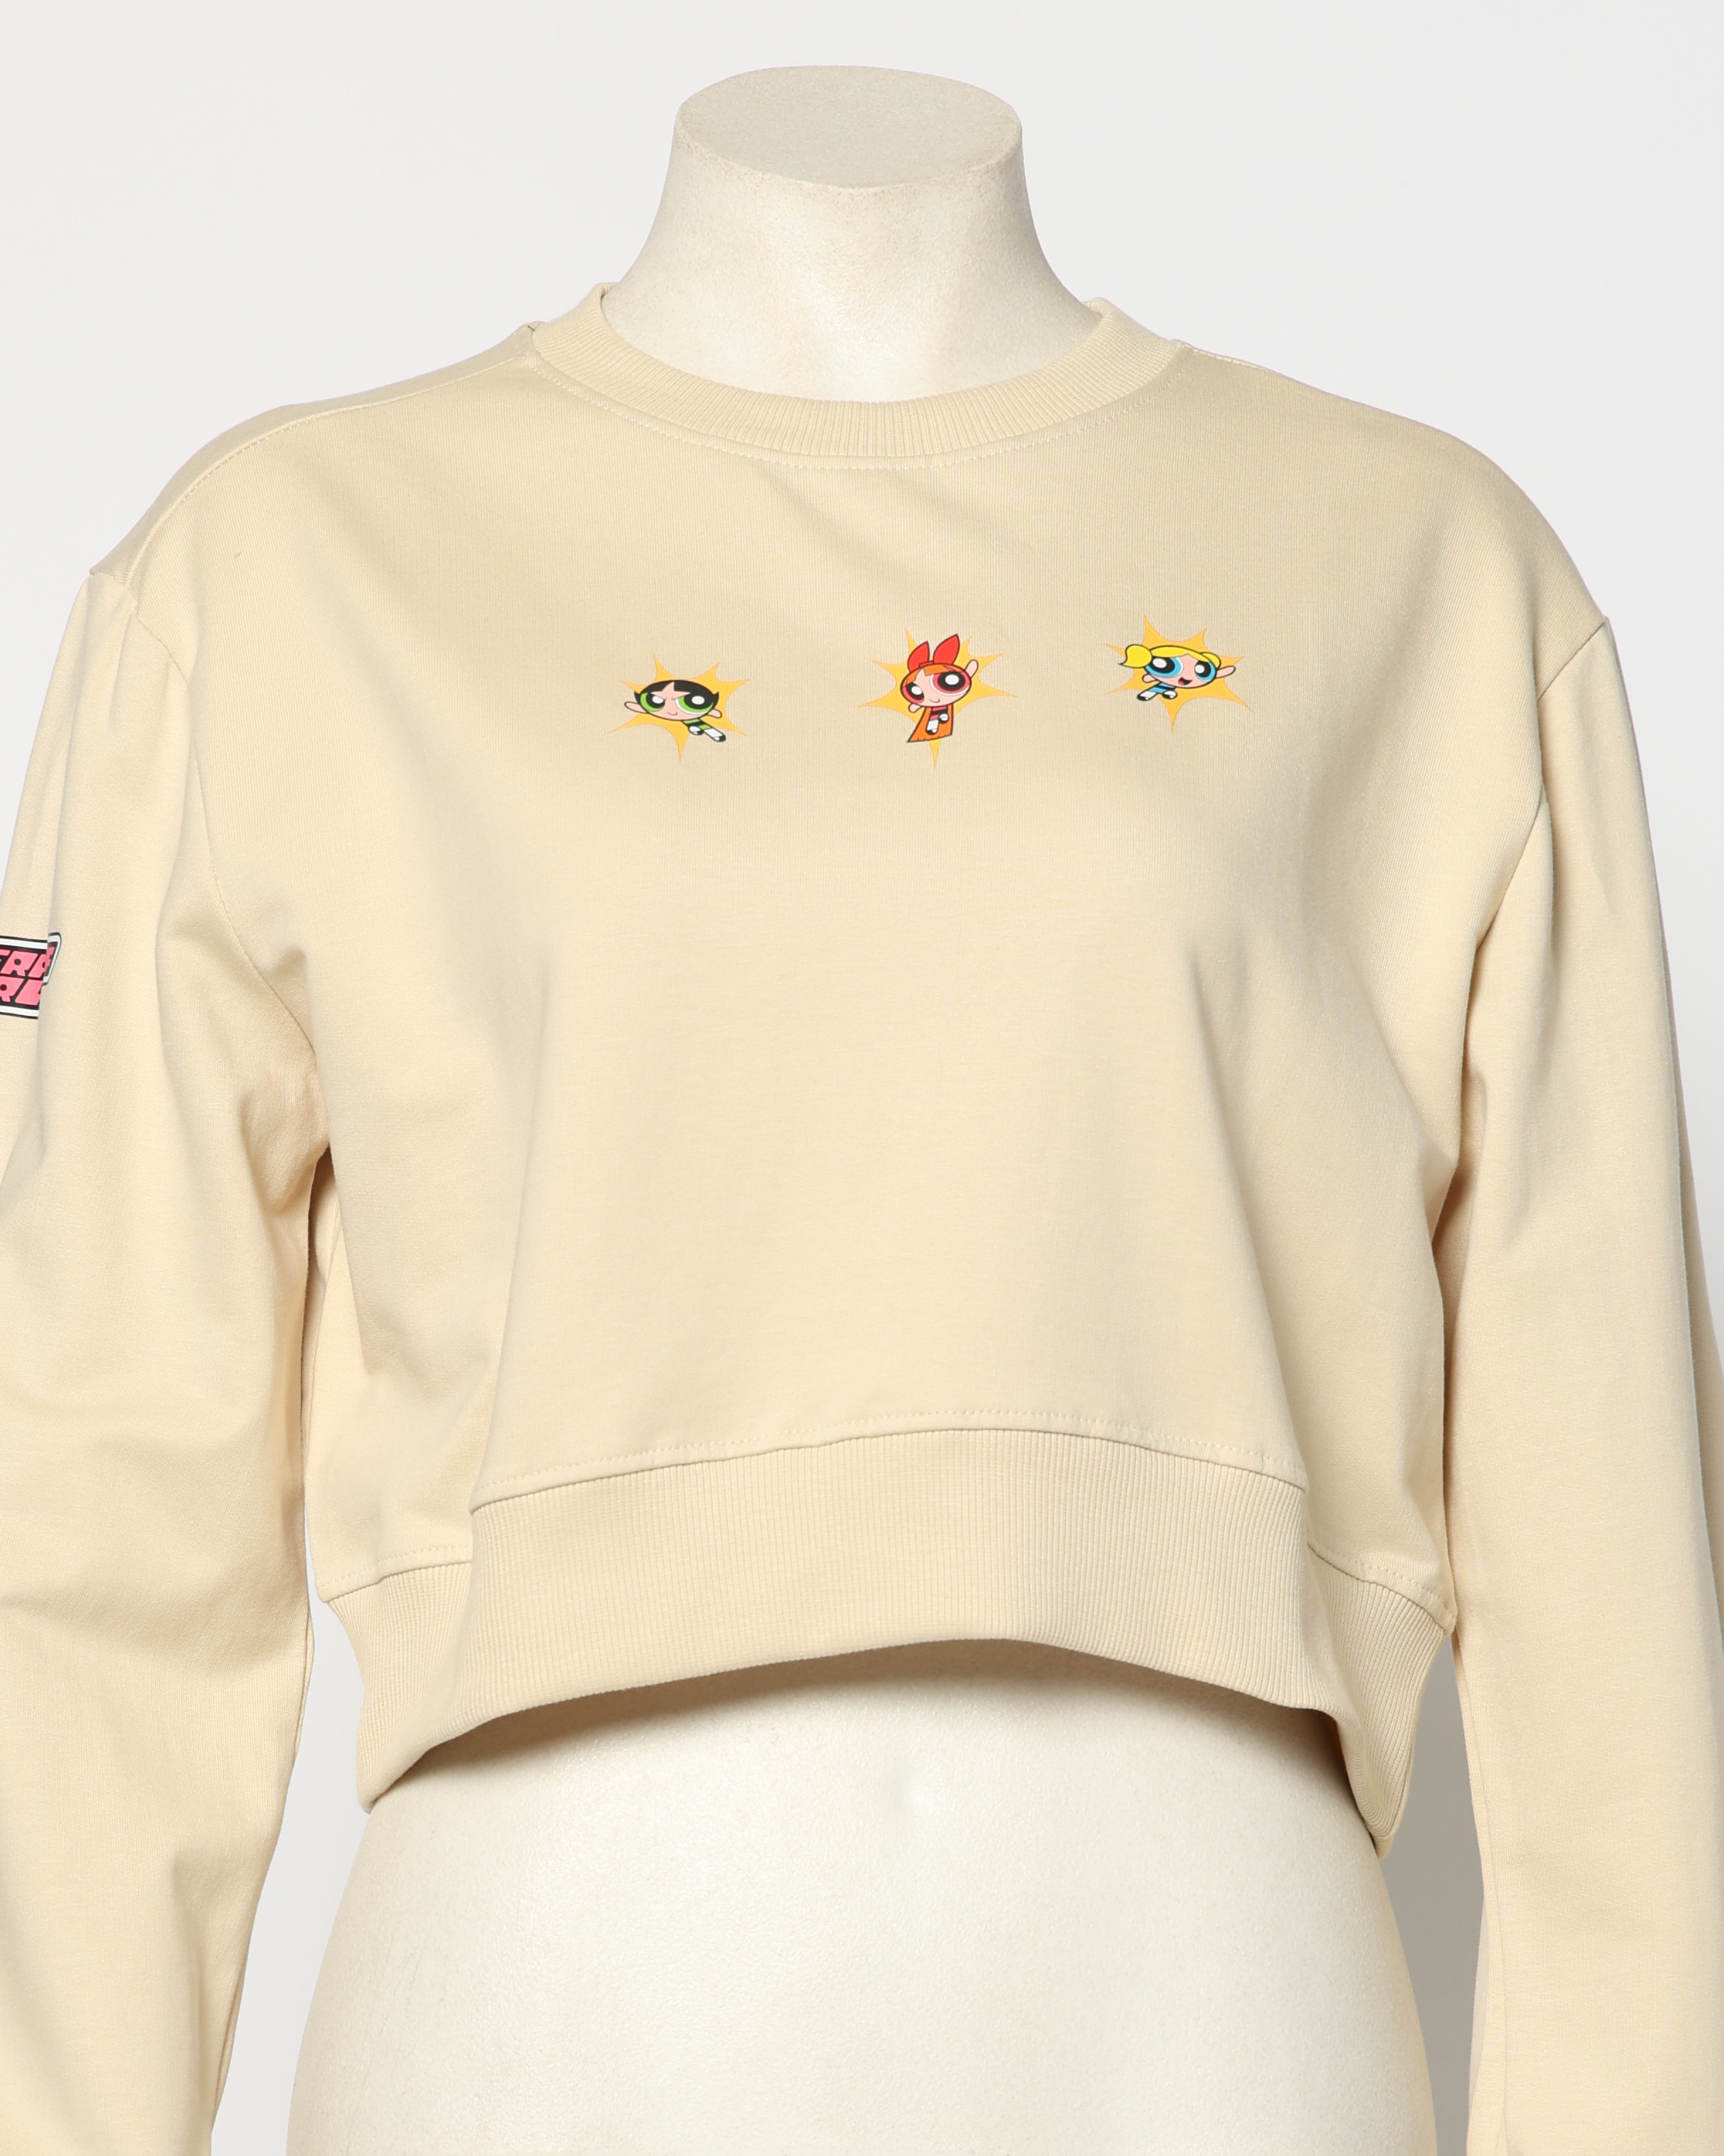
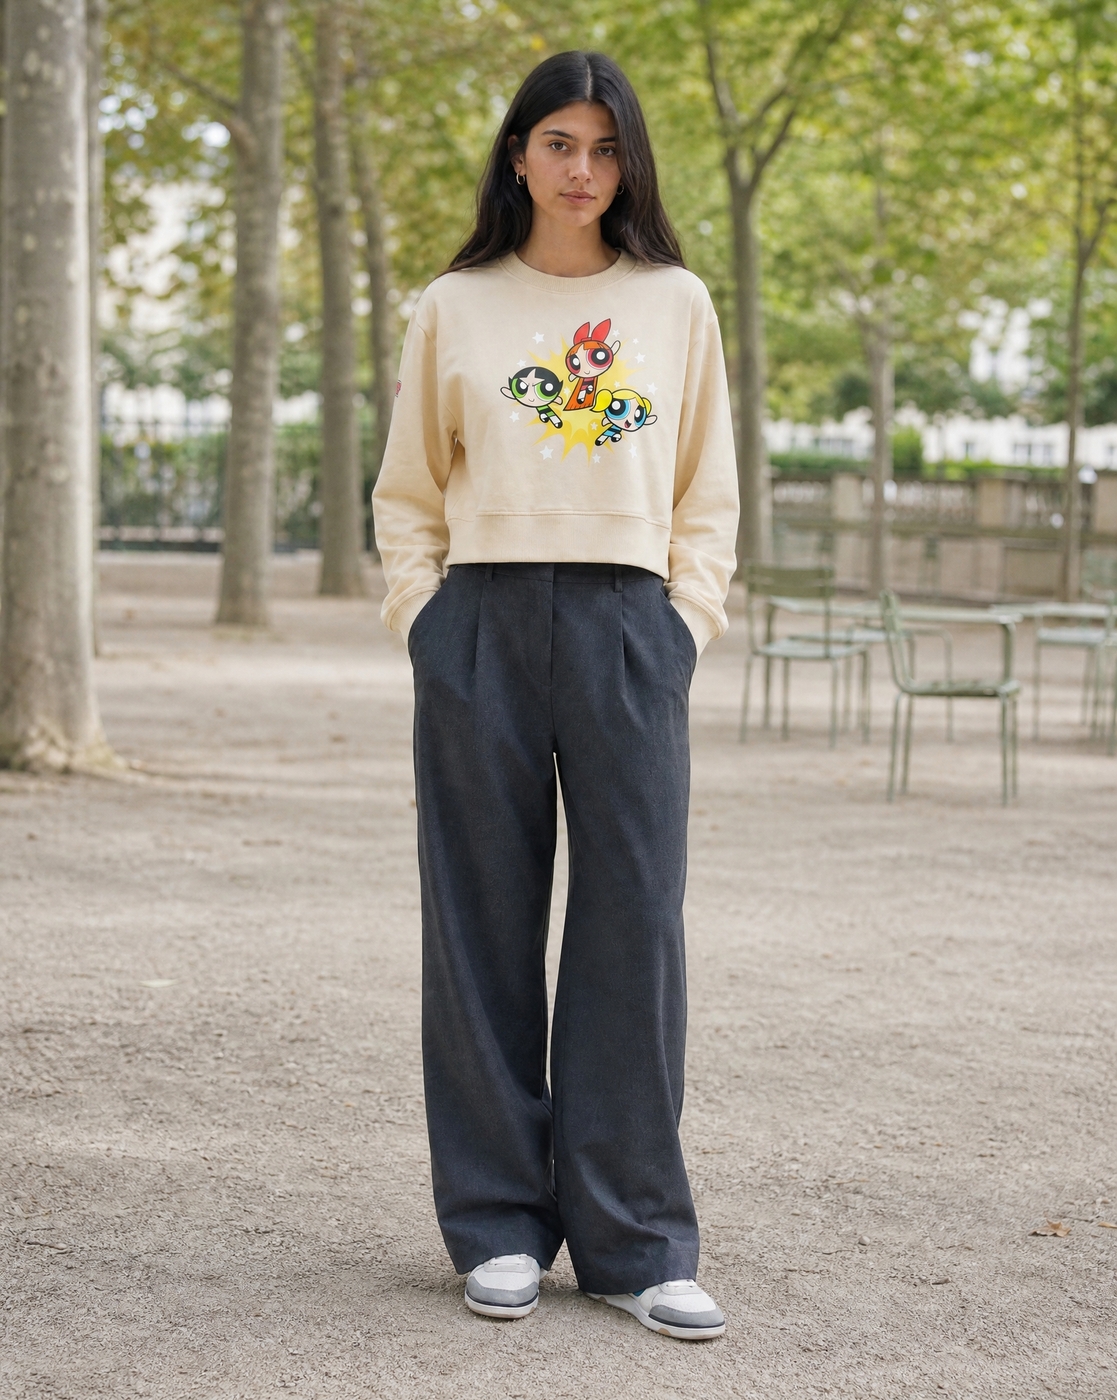
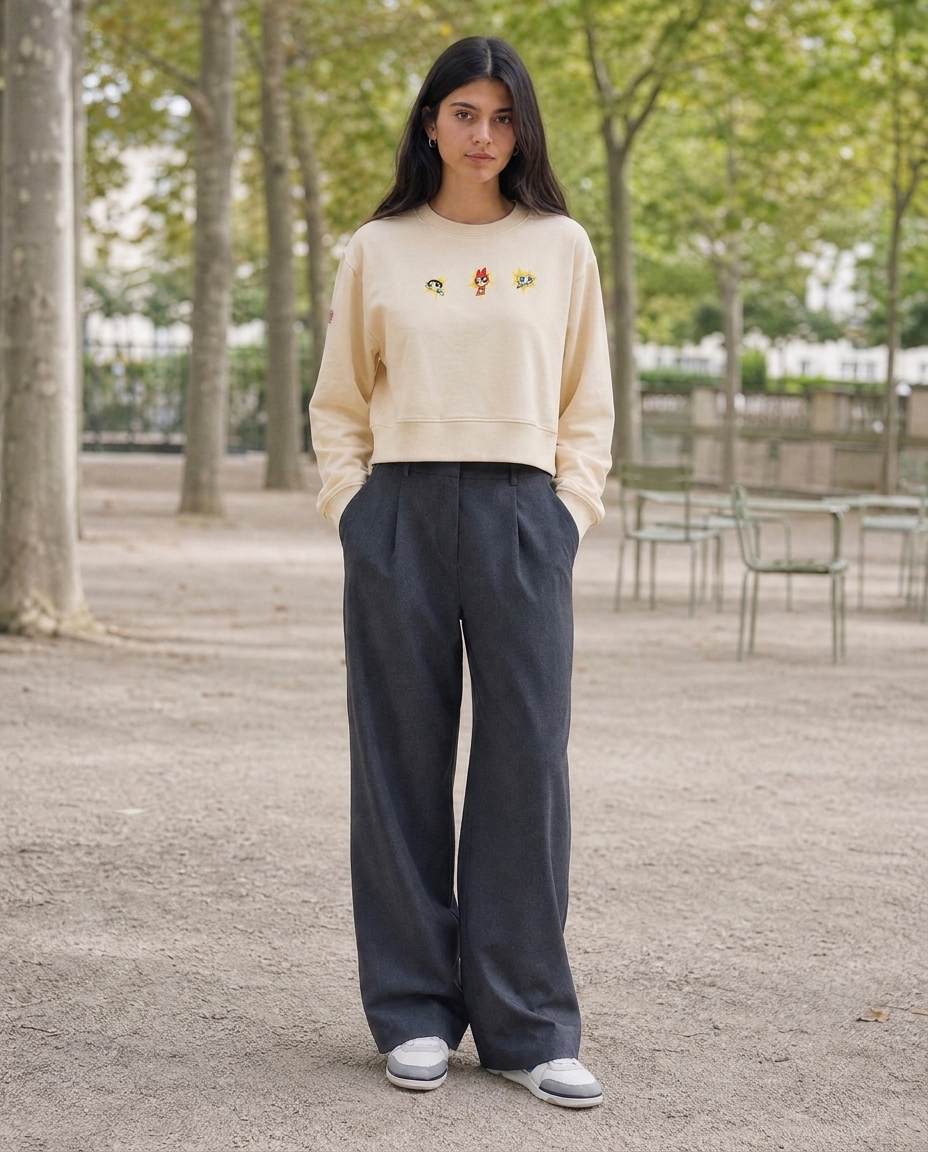
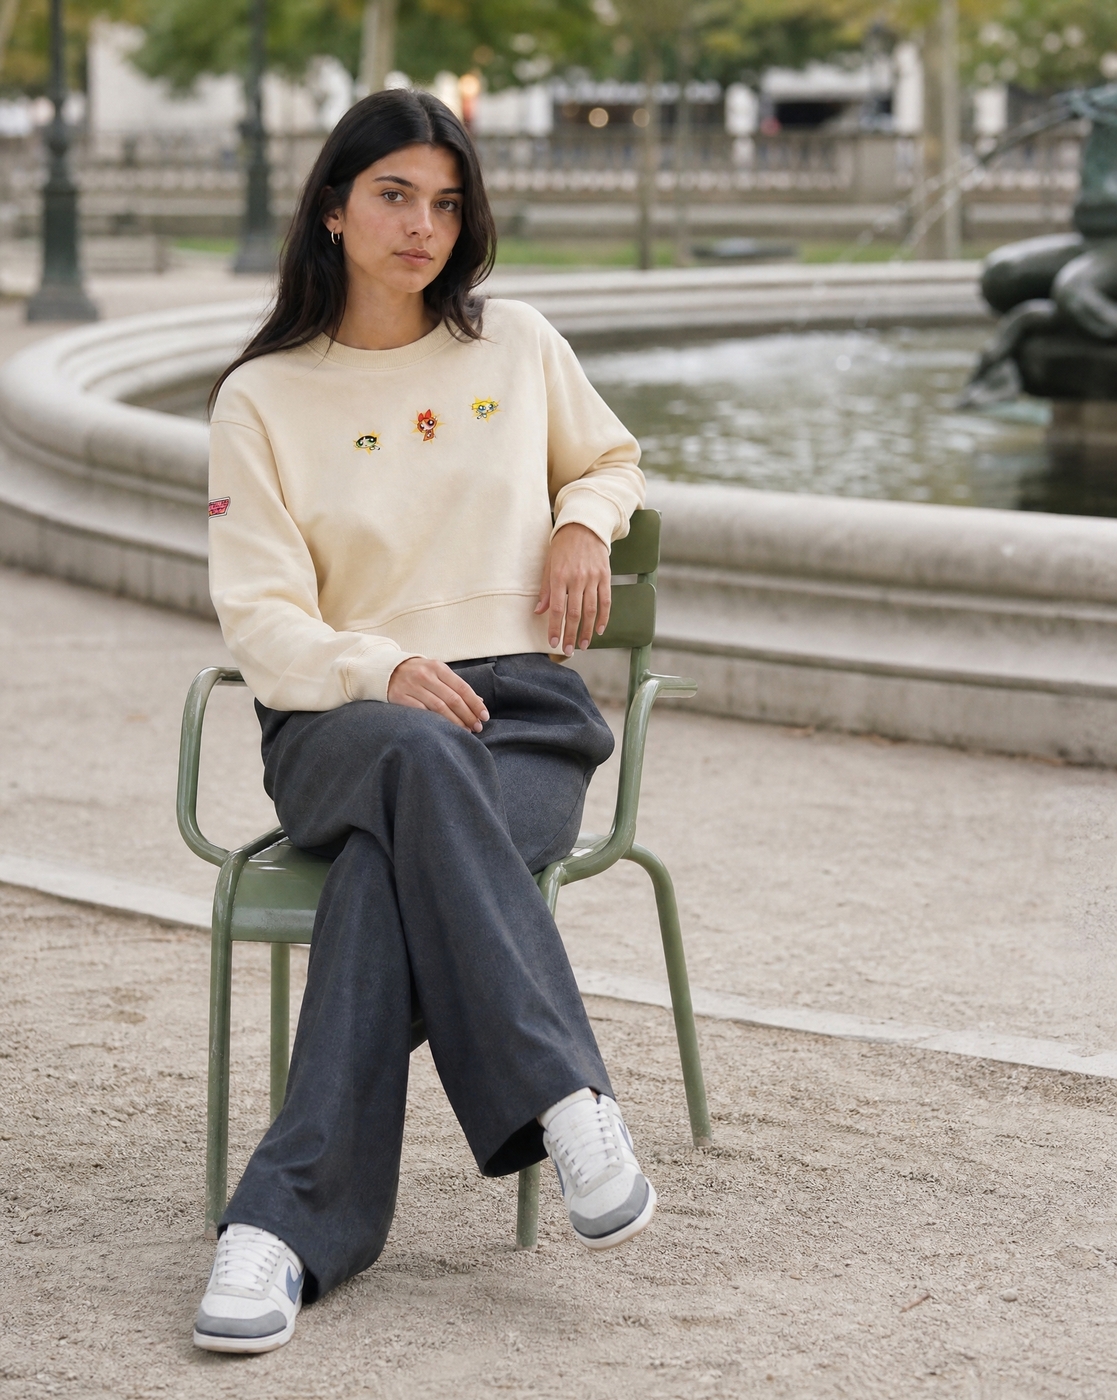
Back graphic printed on the front chest 1 of 5 outputs replaced
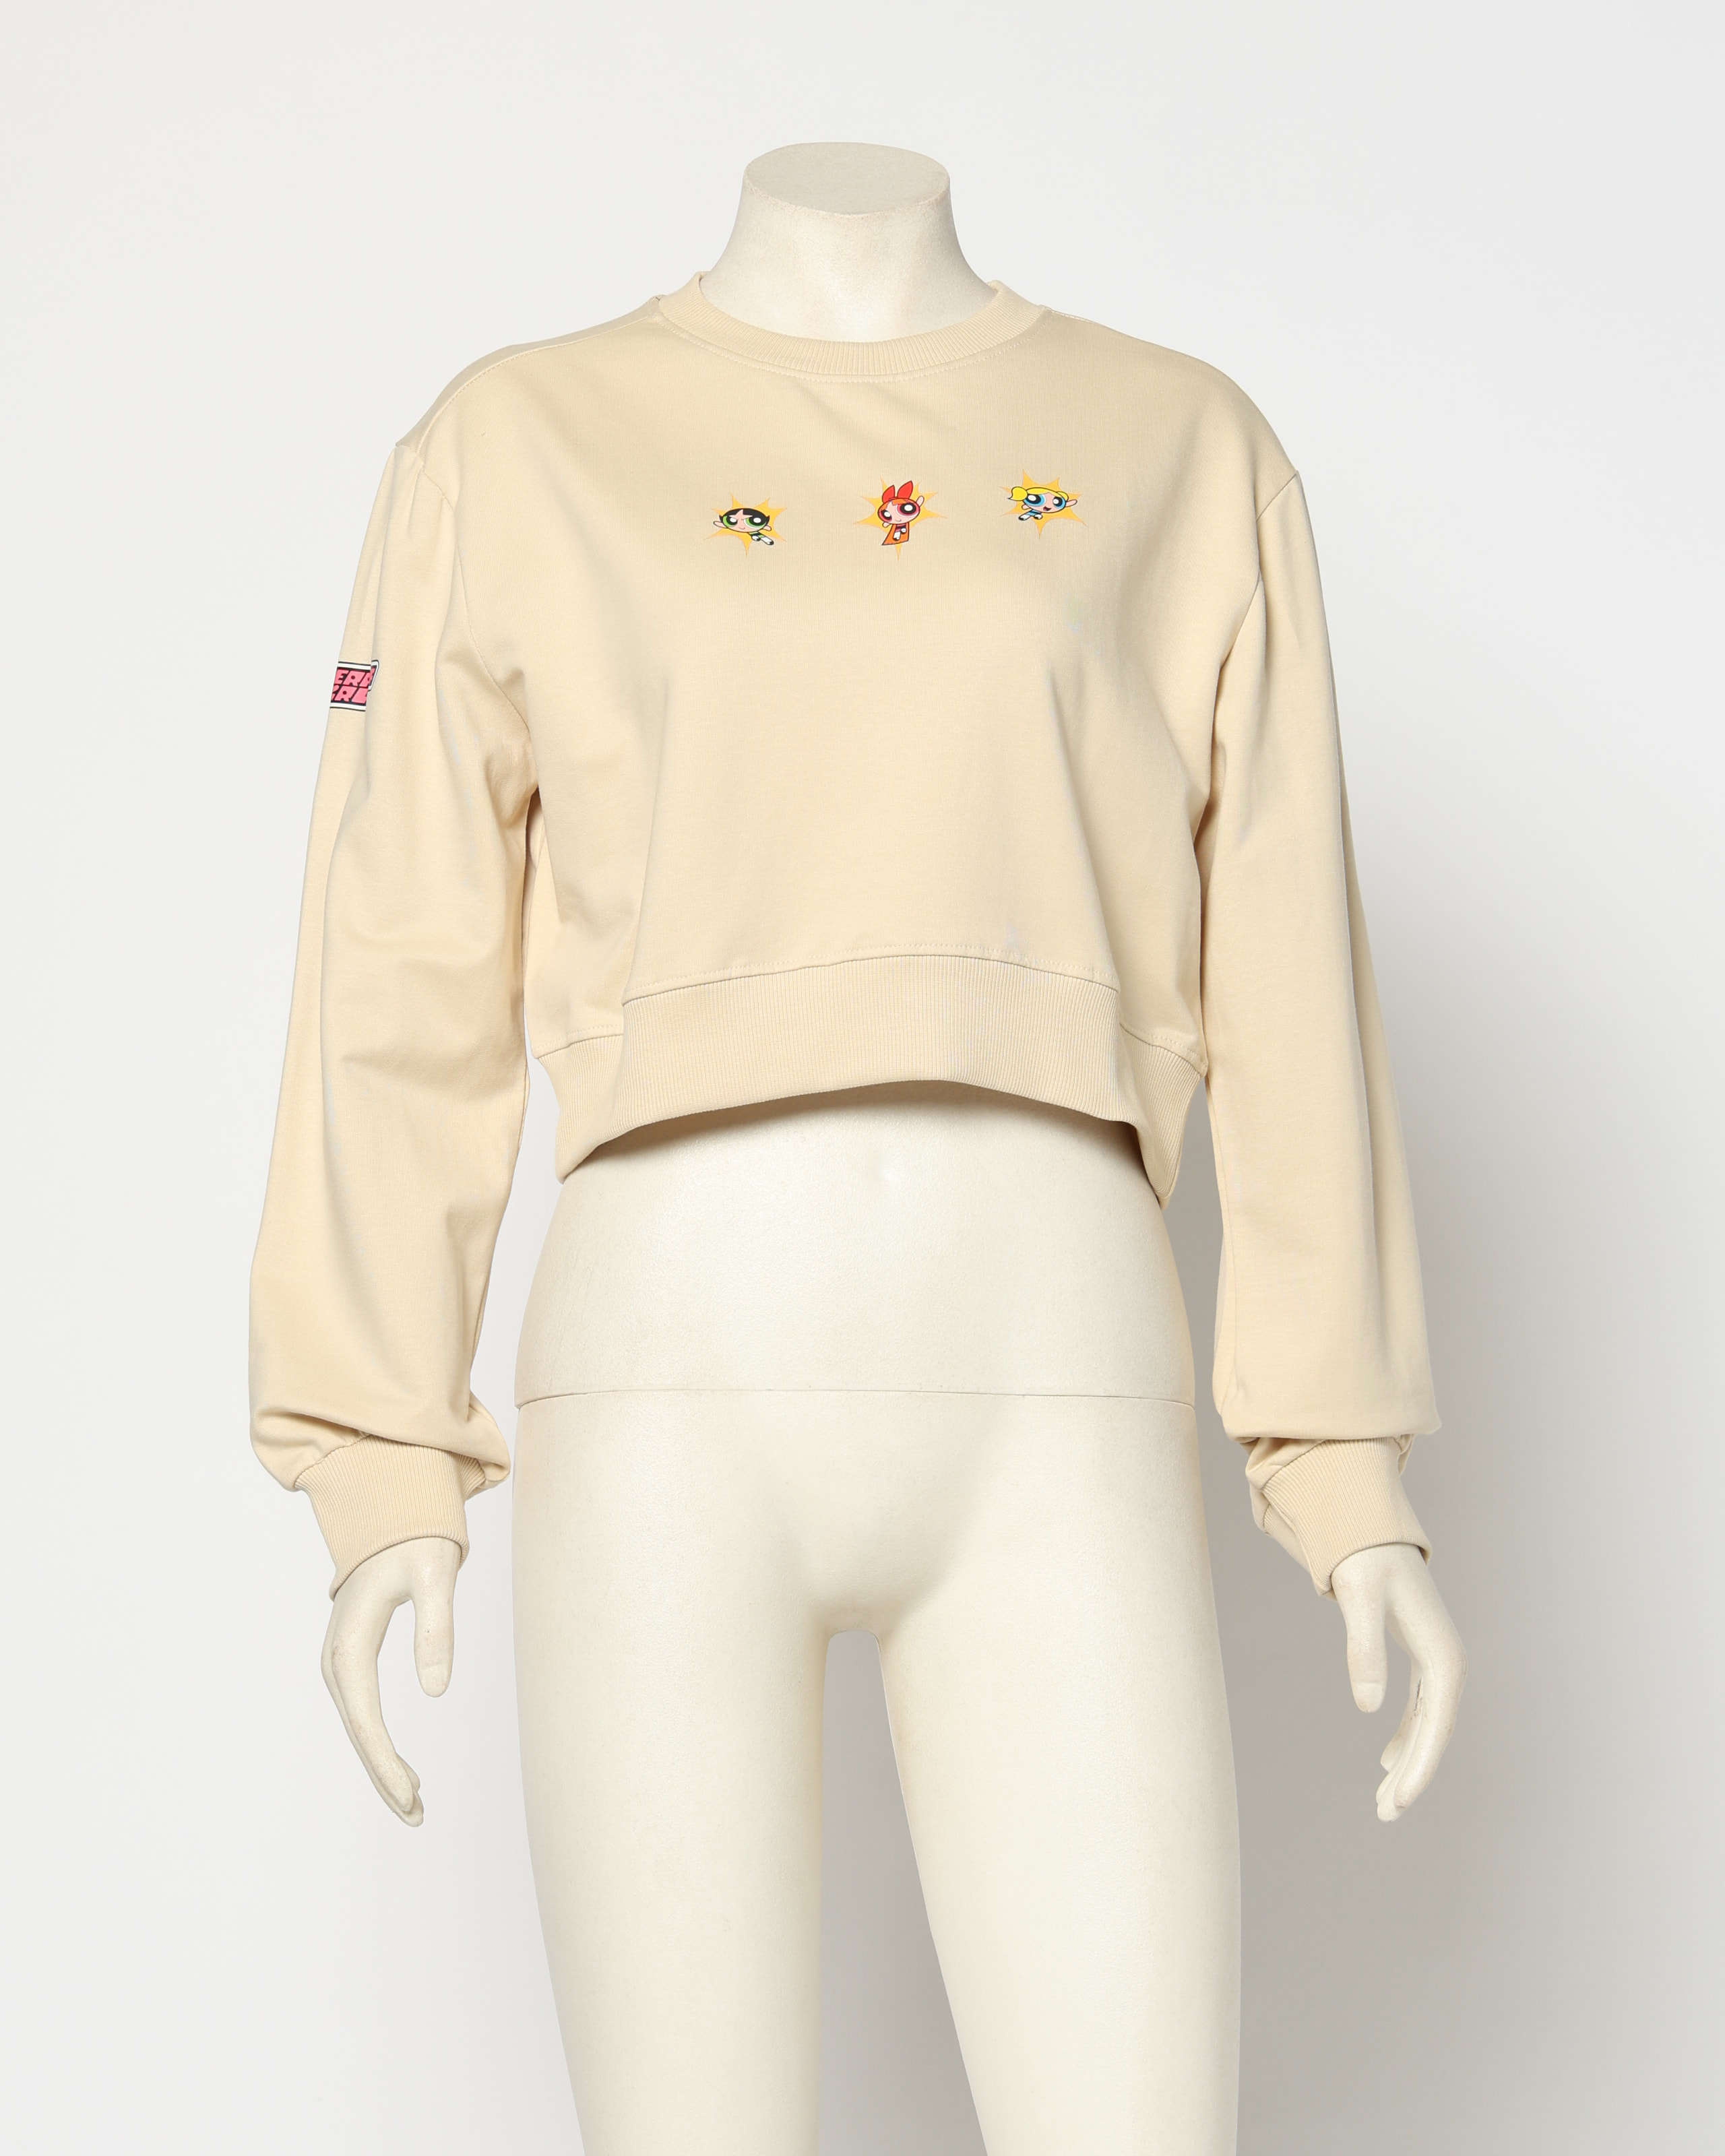
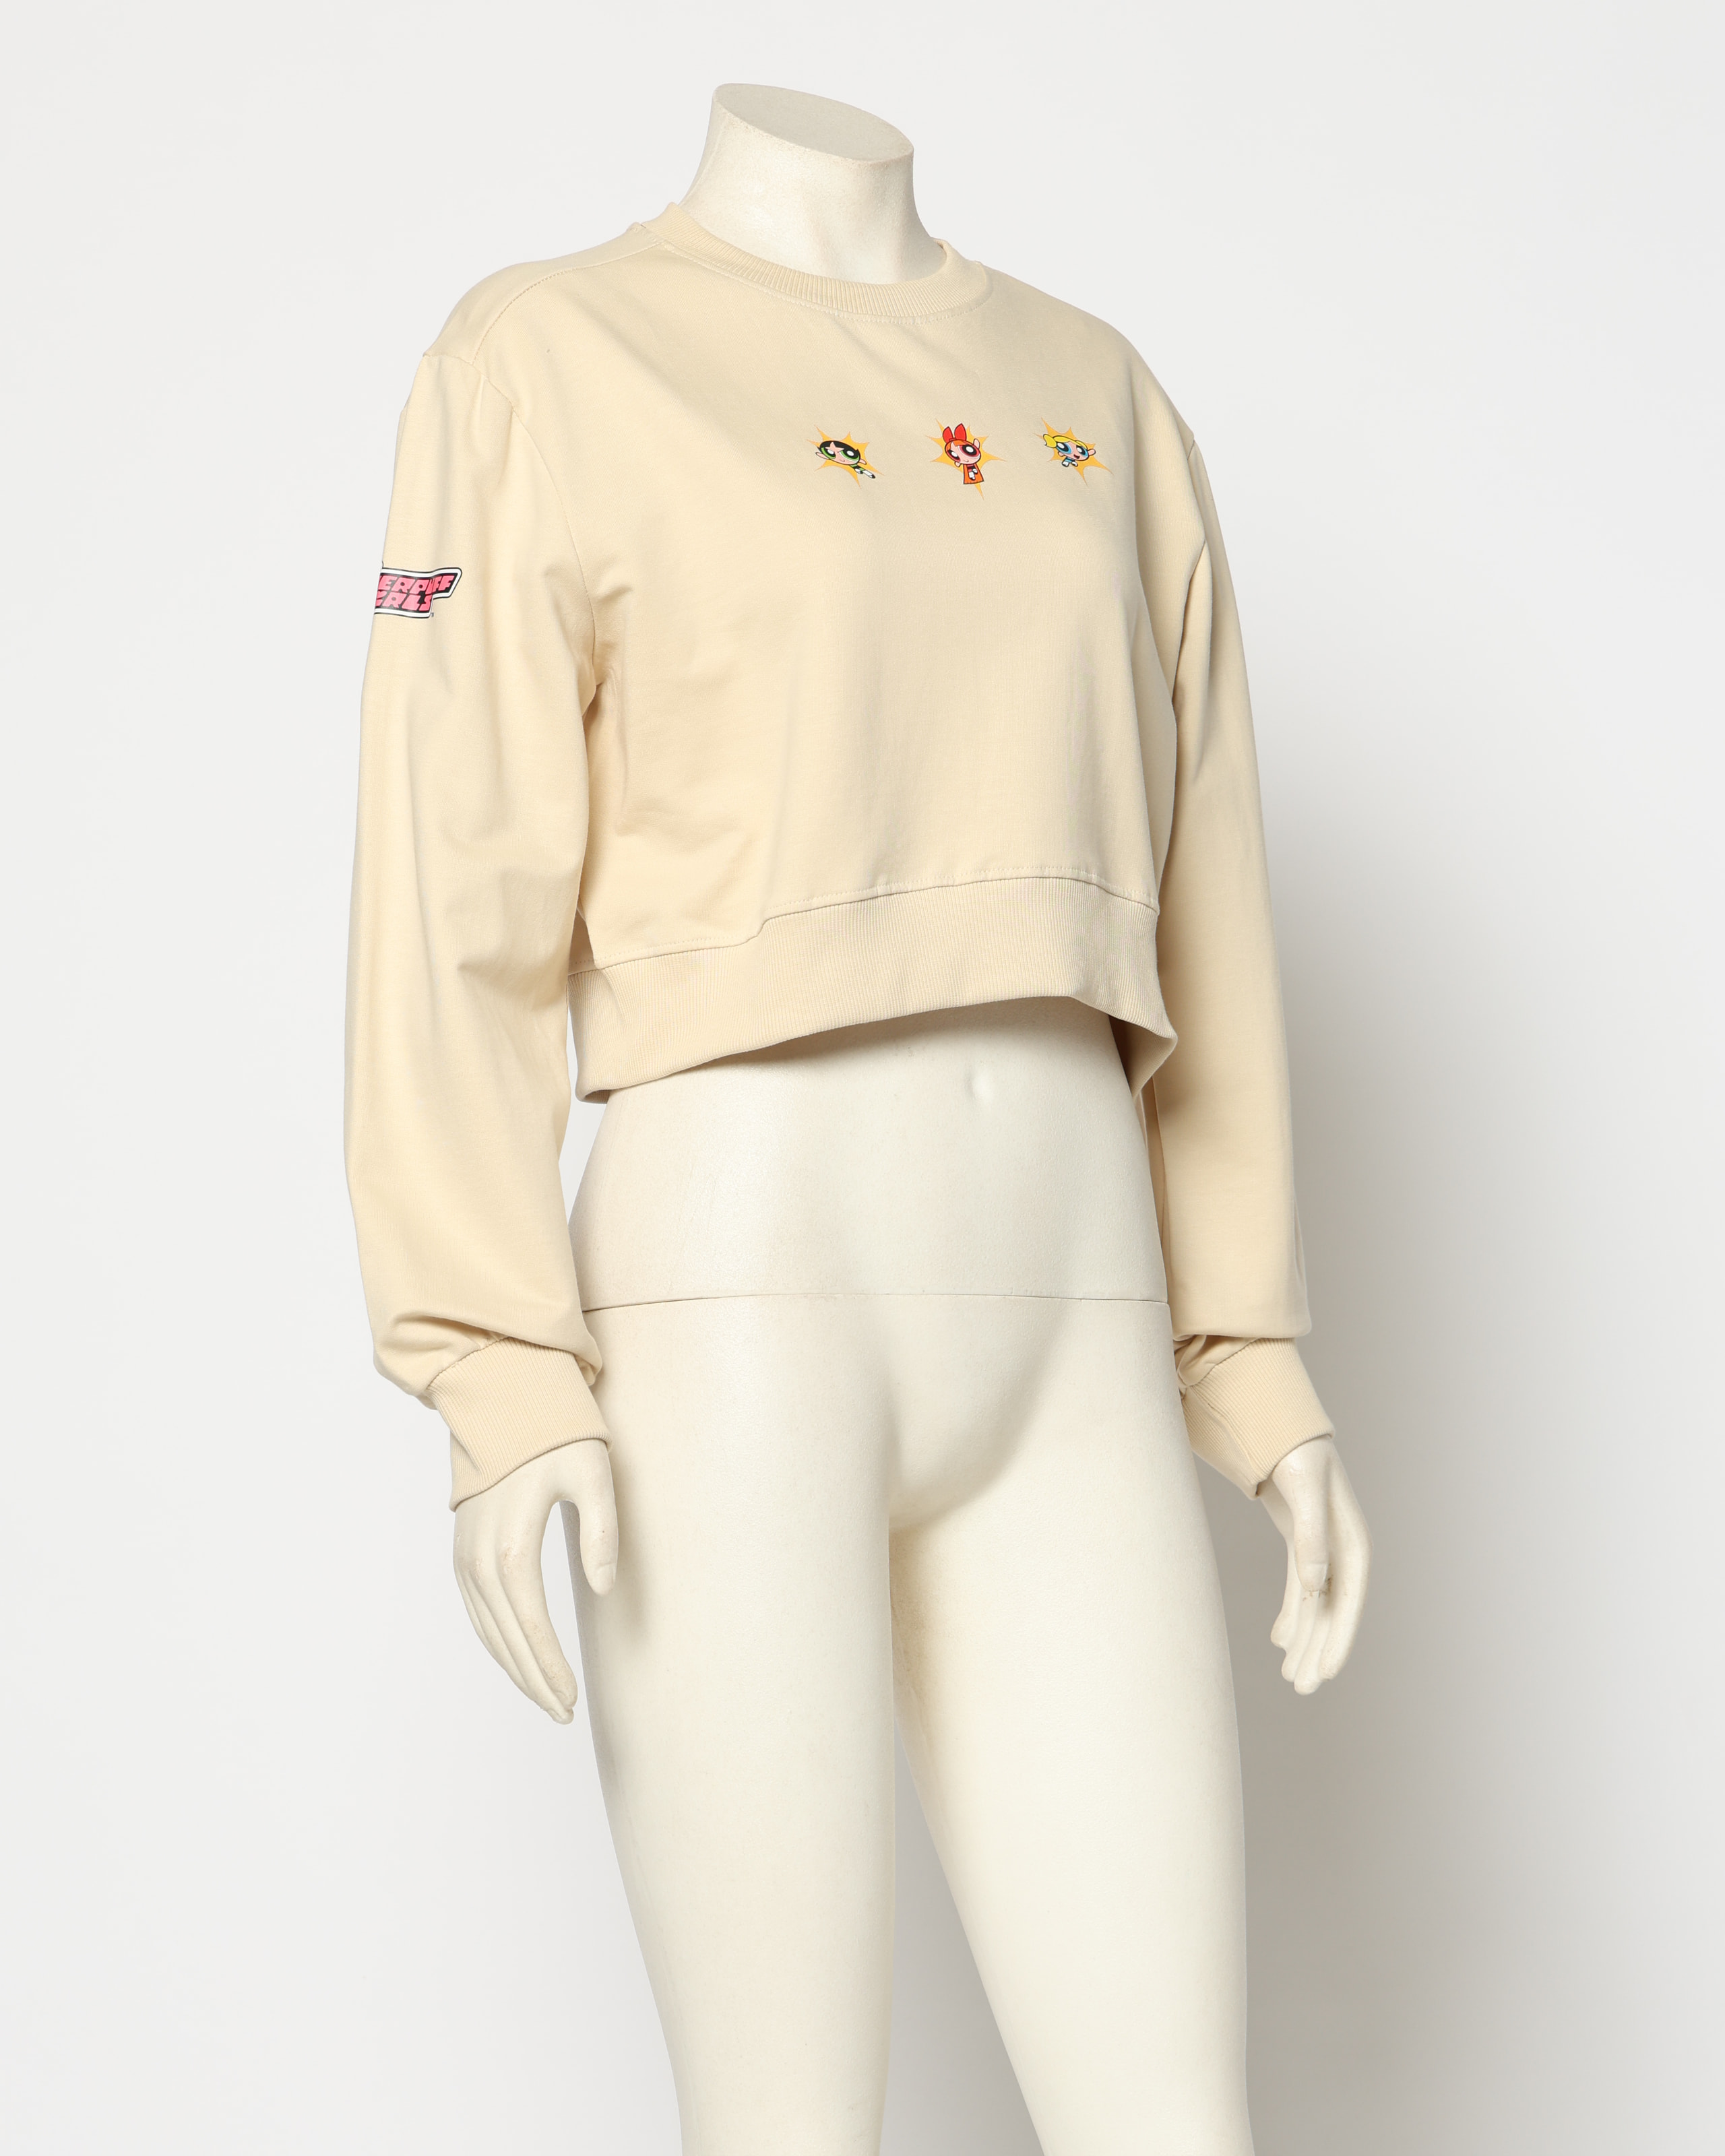
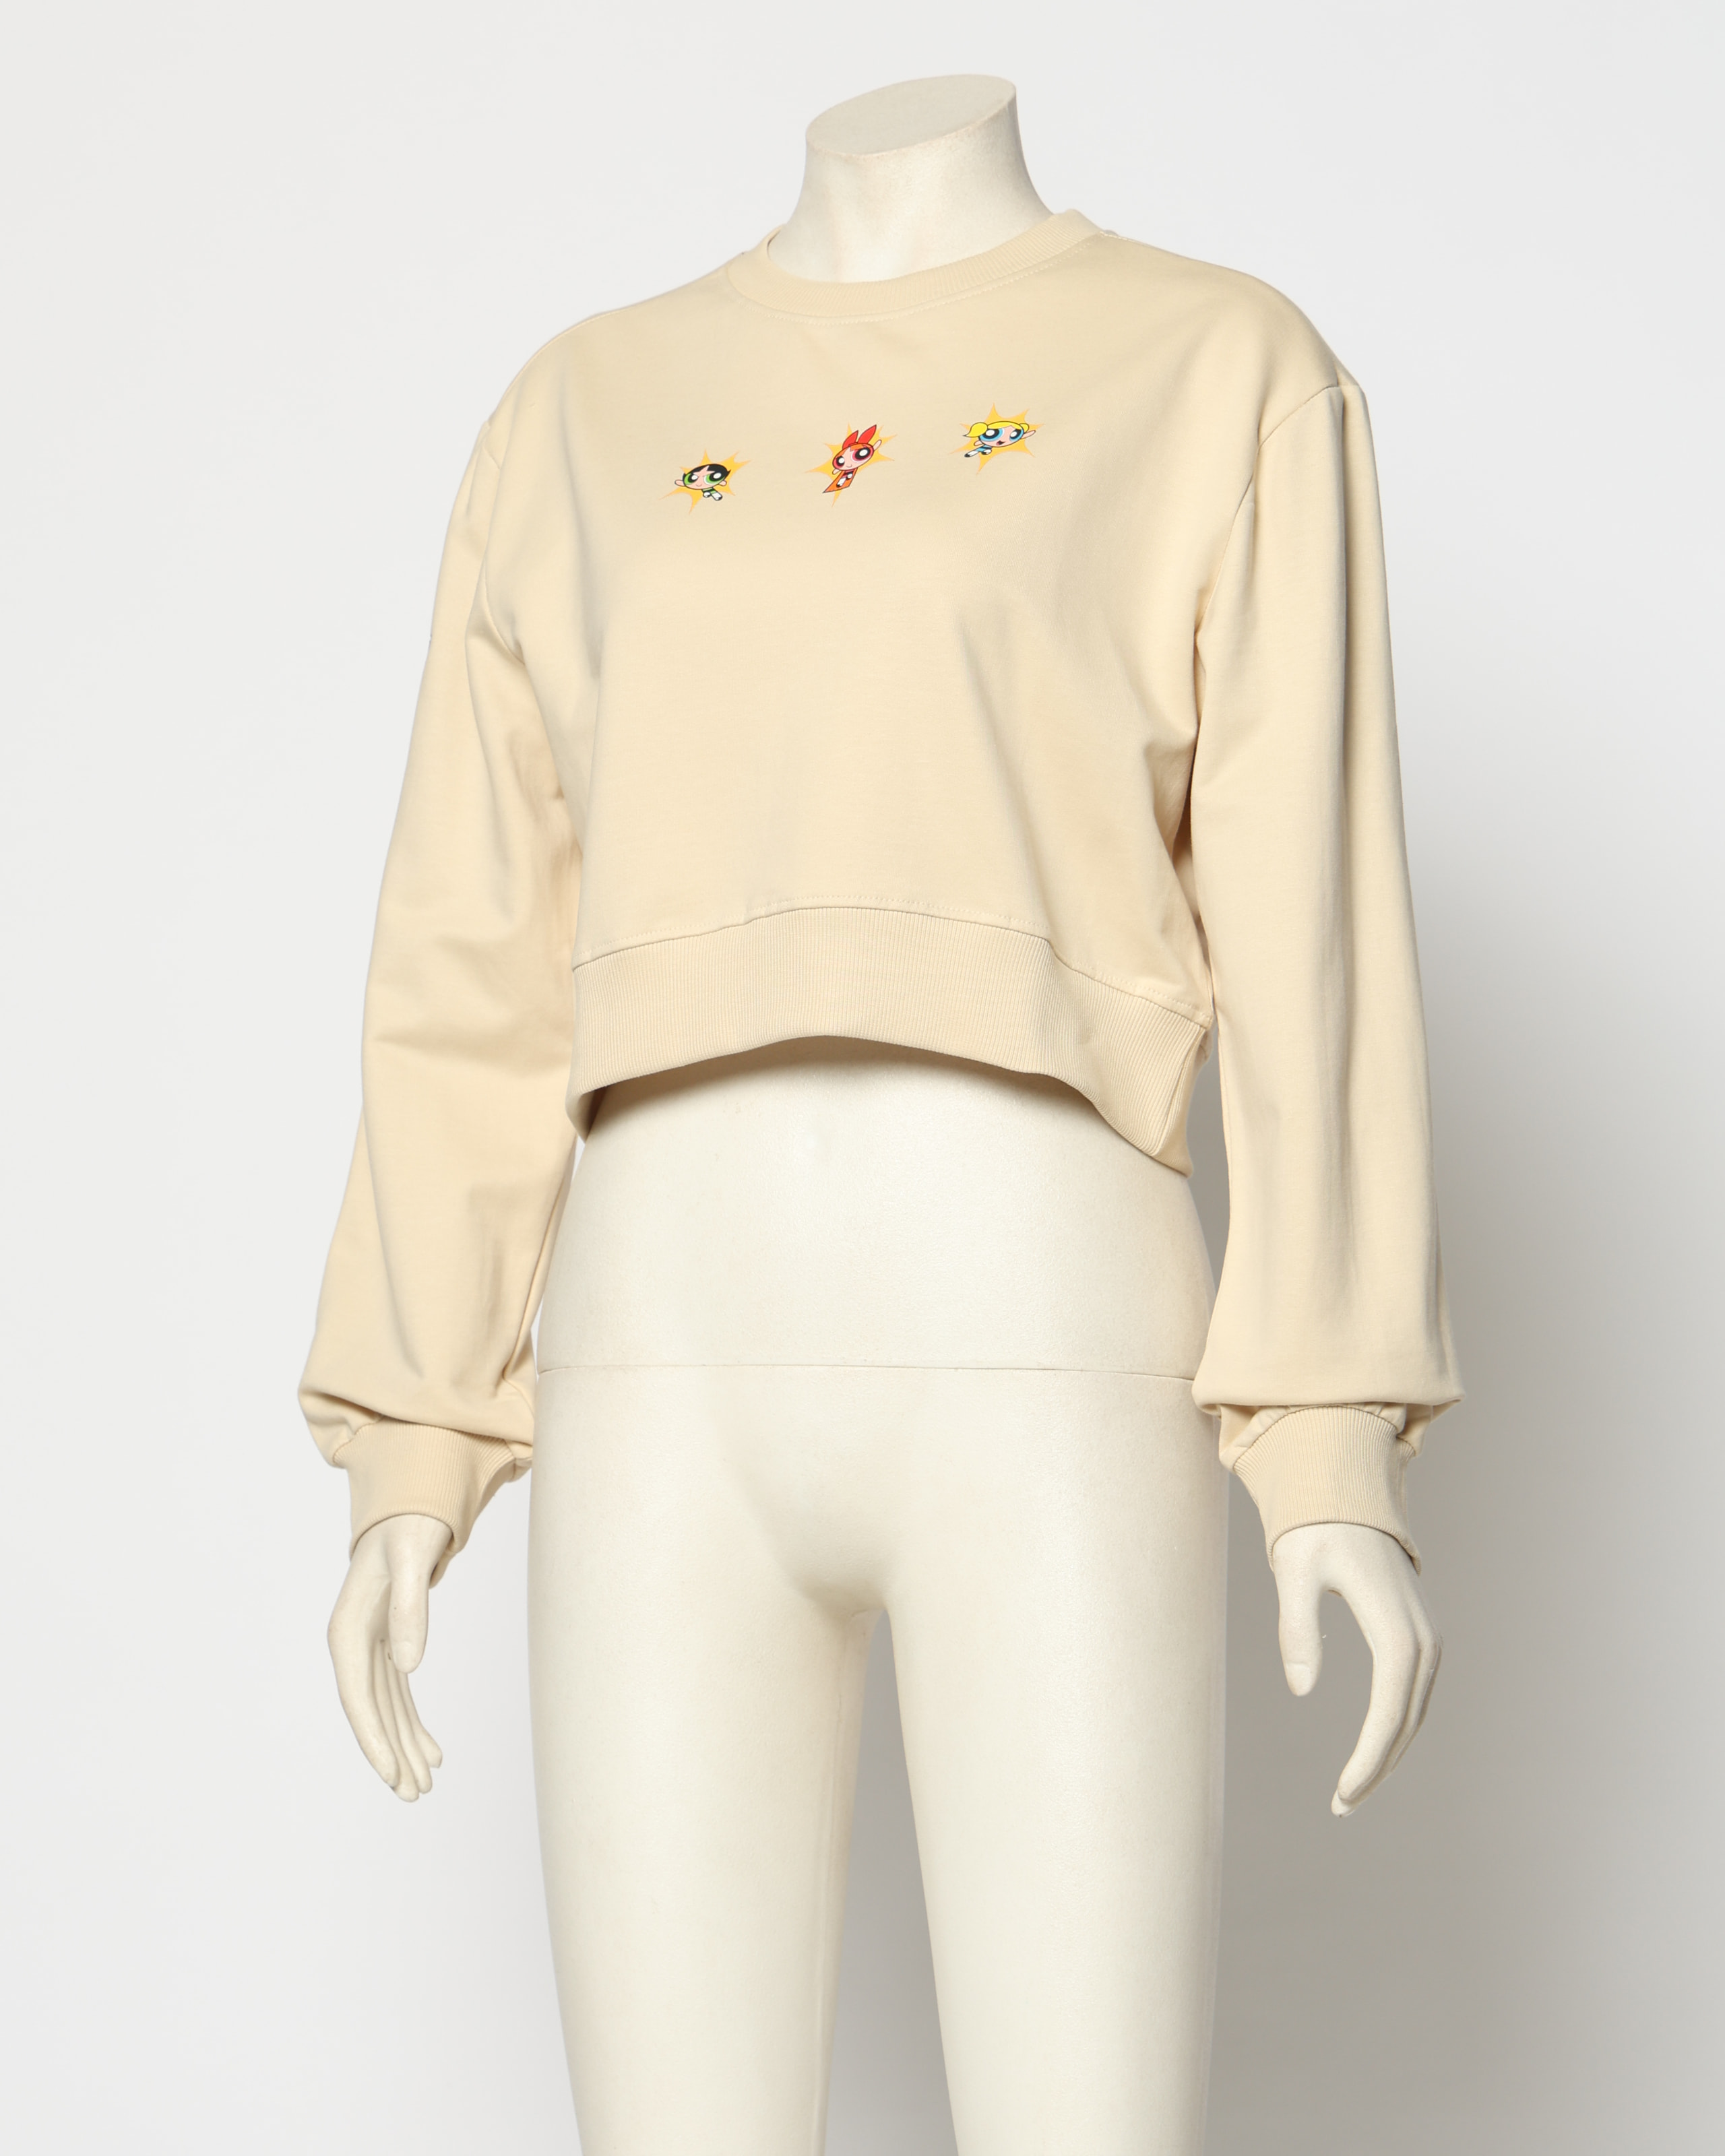
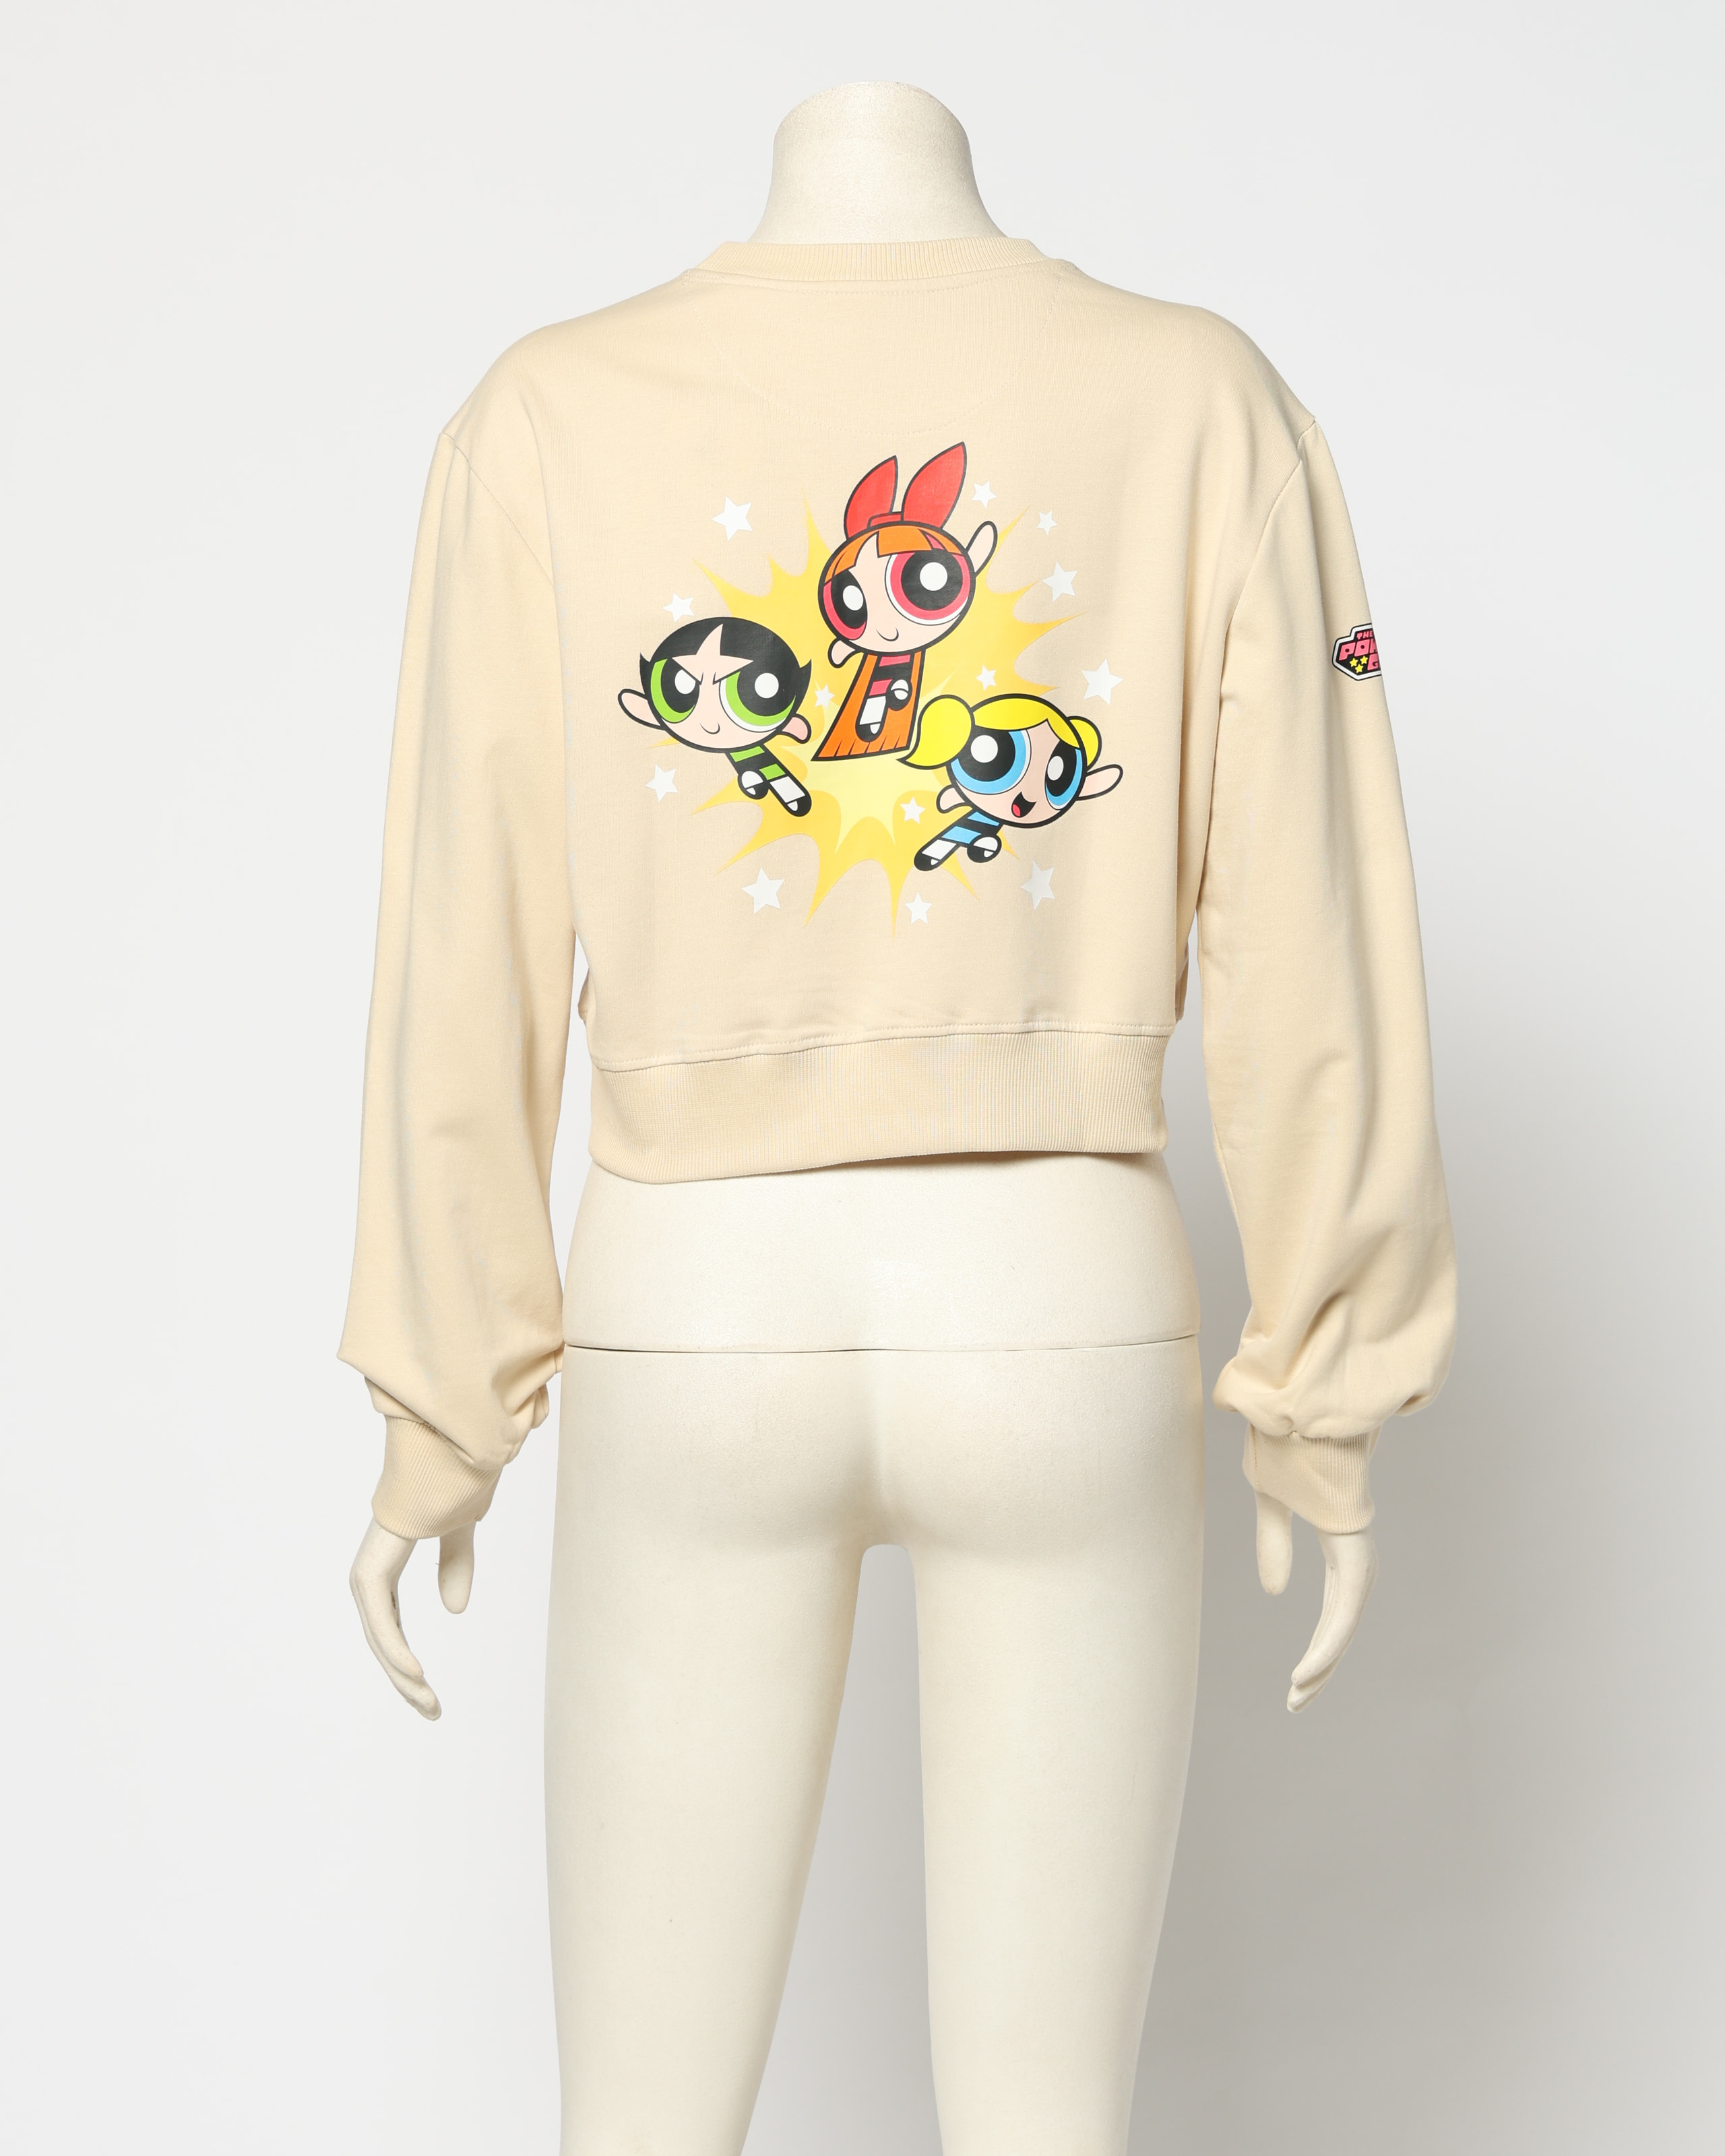
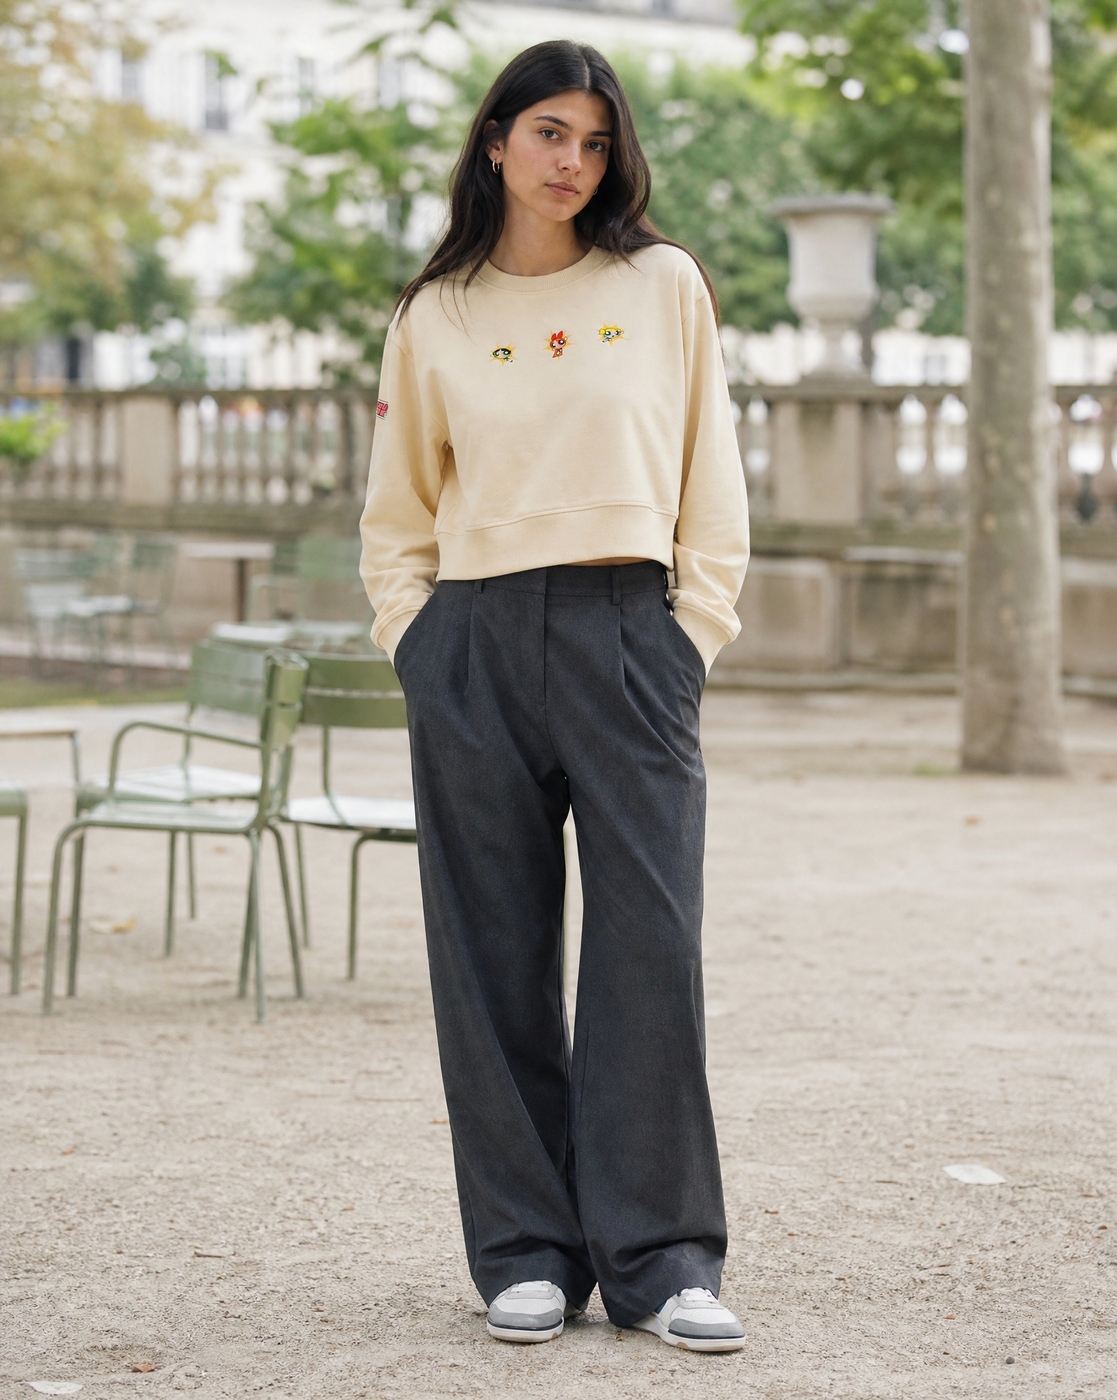
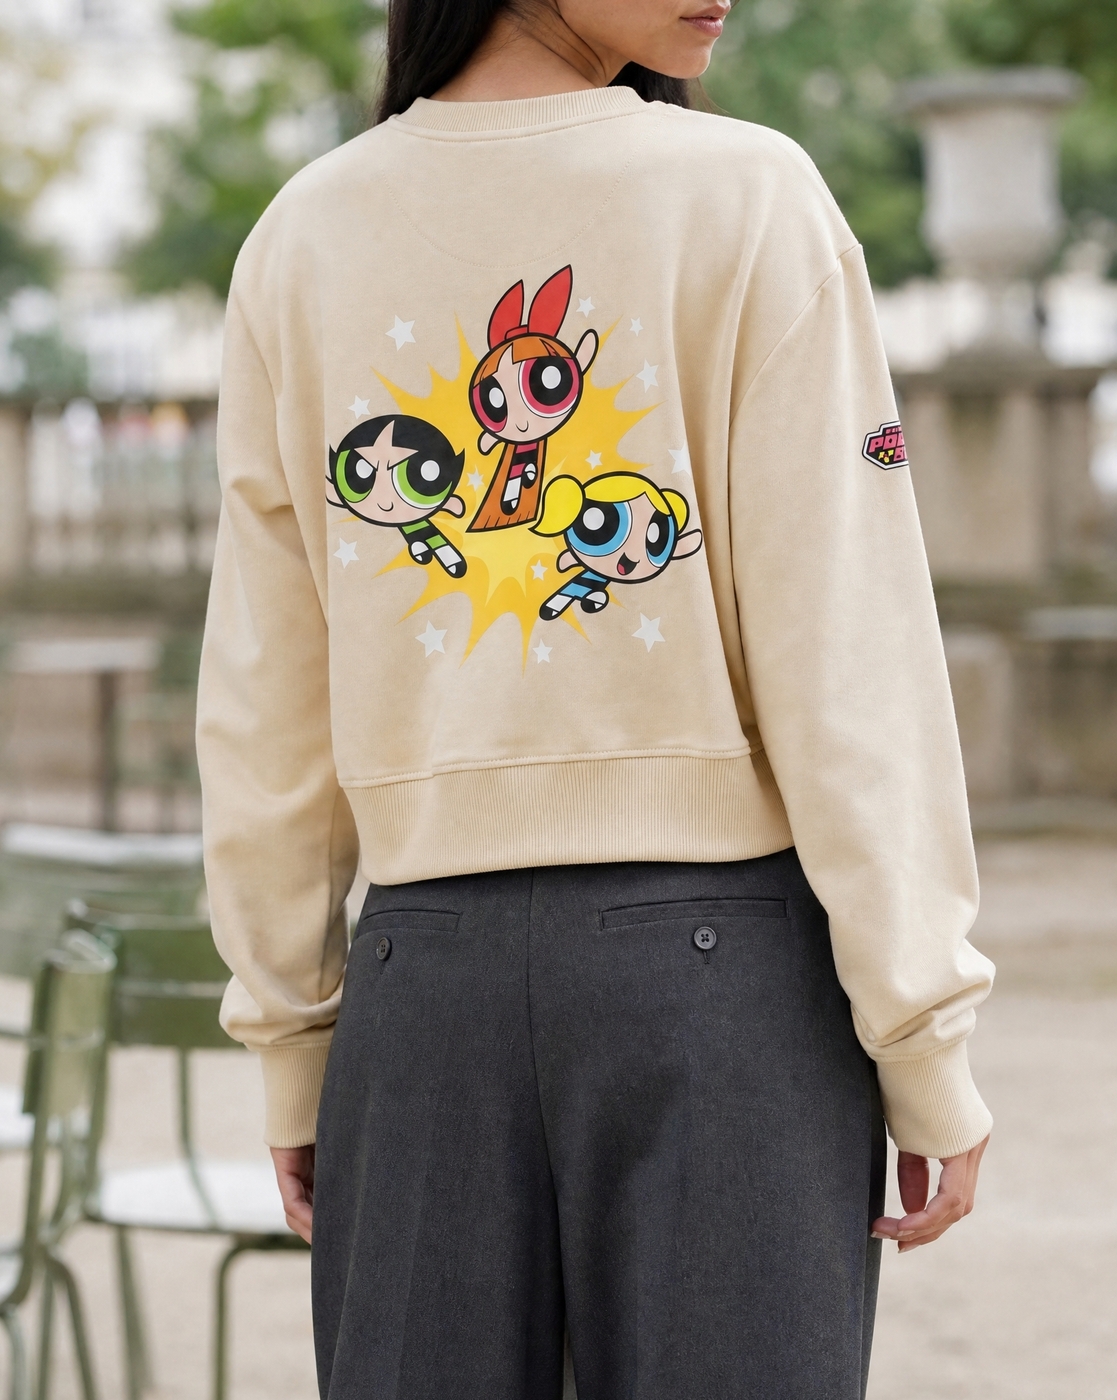
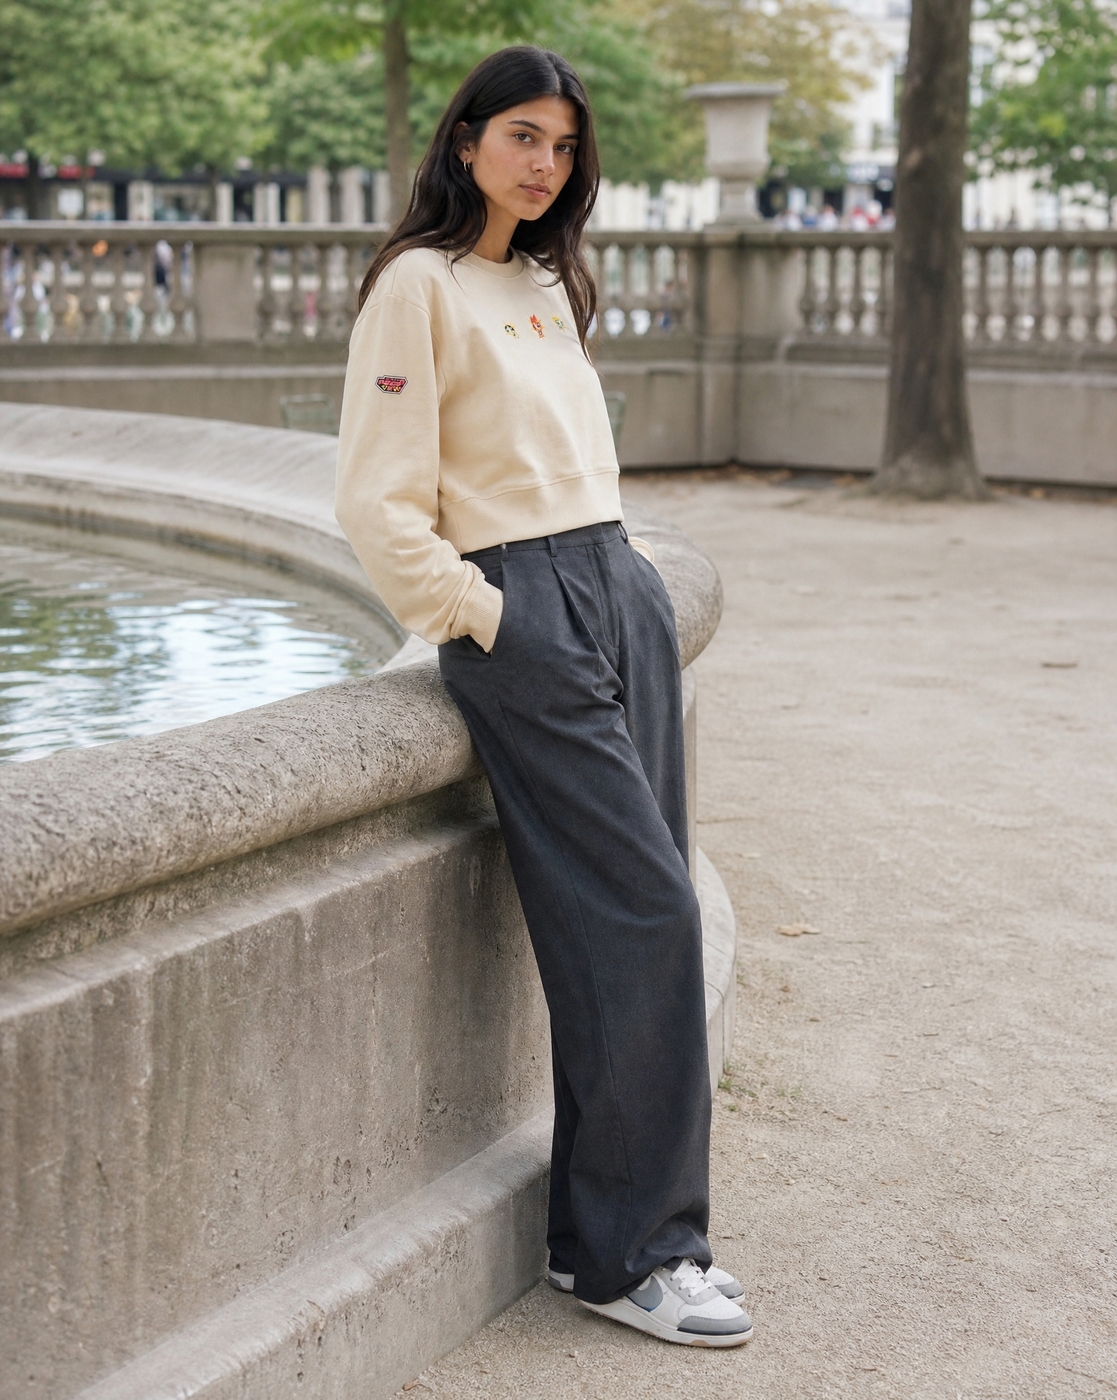
A cream tee with three small embroidered characters on the front and one large illustration on the back. One of five outputs put the back illustration across the front chest. The agent caught it on garment consistency and print placement, and regenerated that single image.
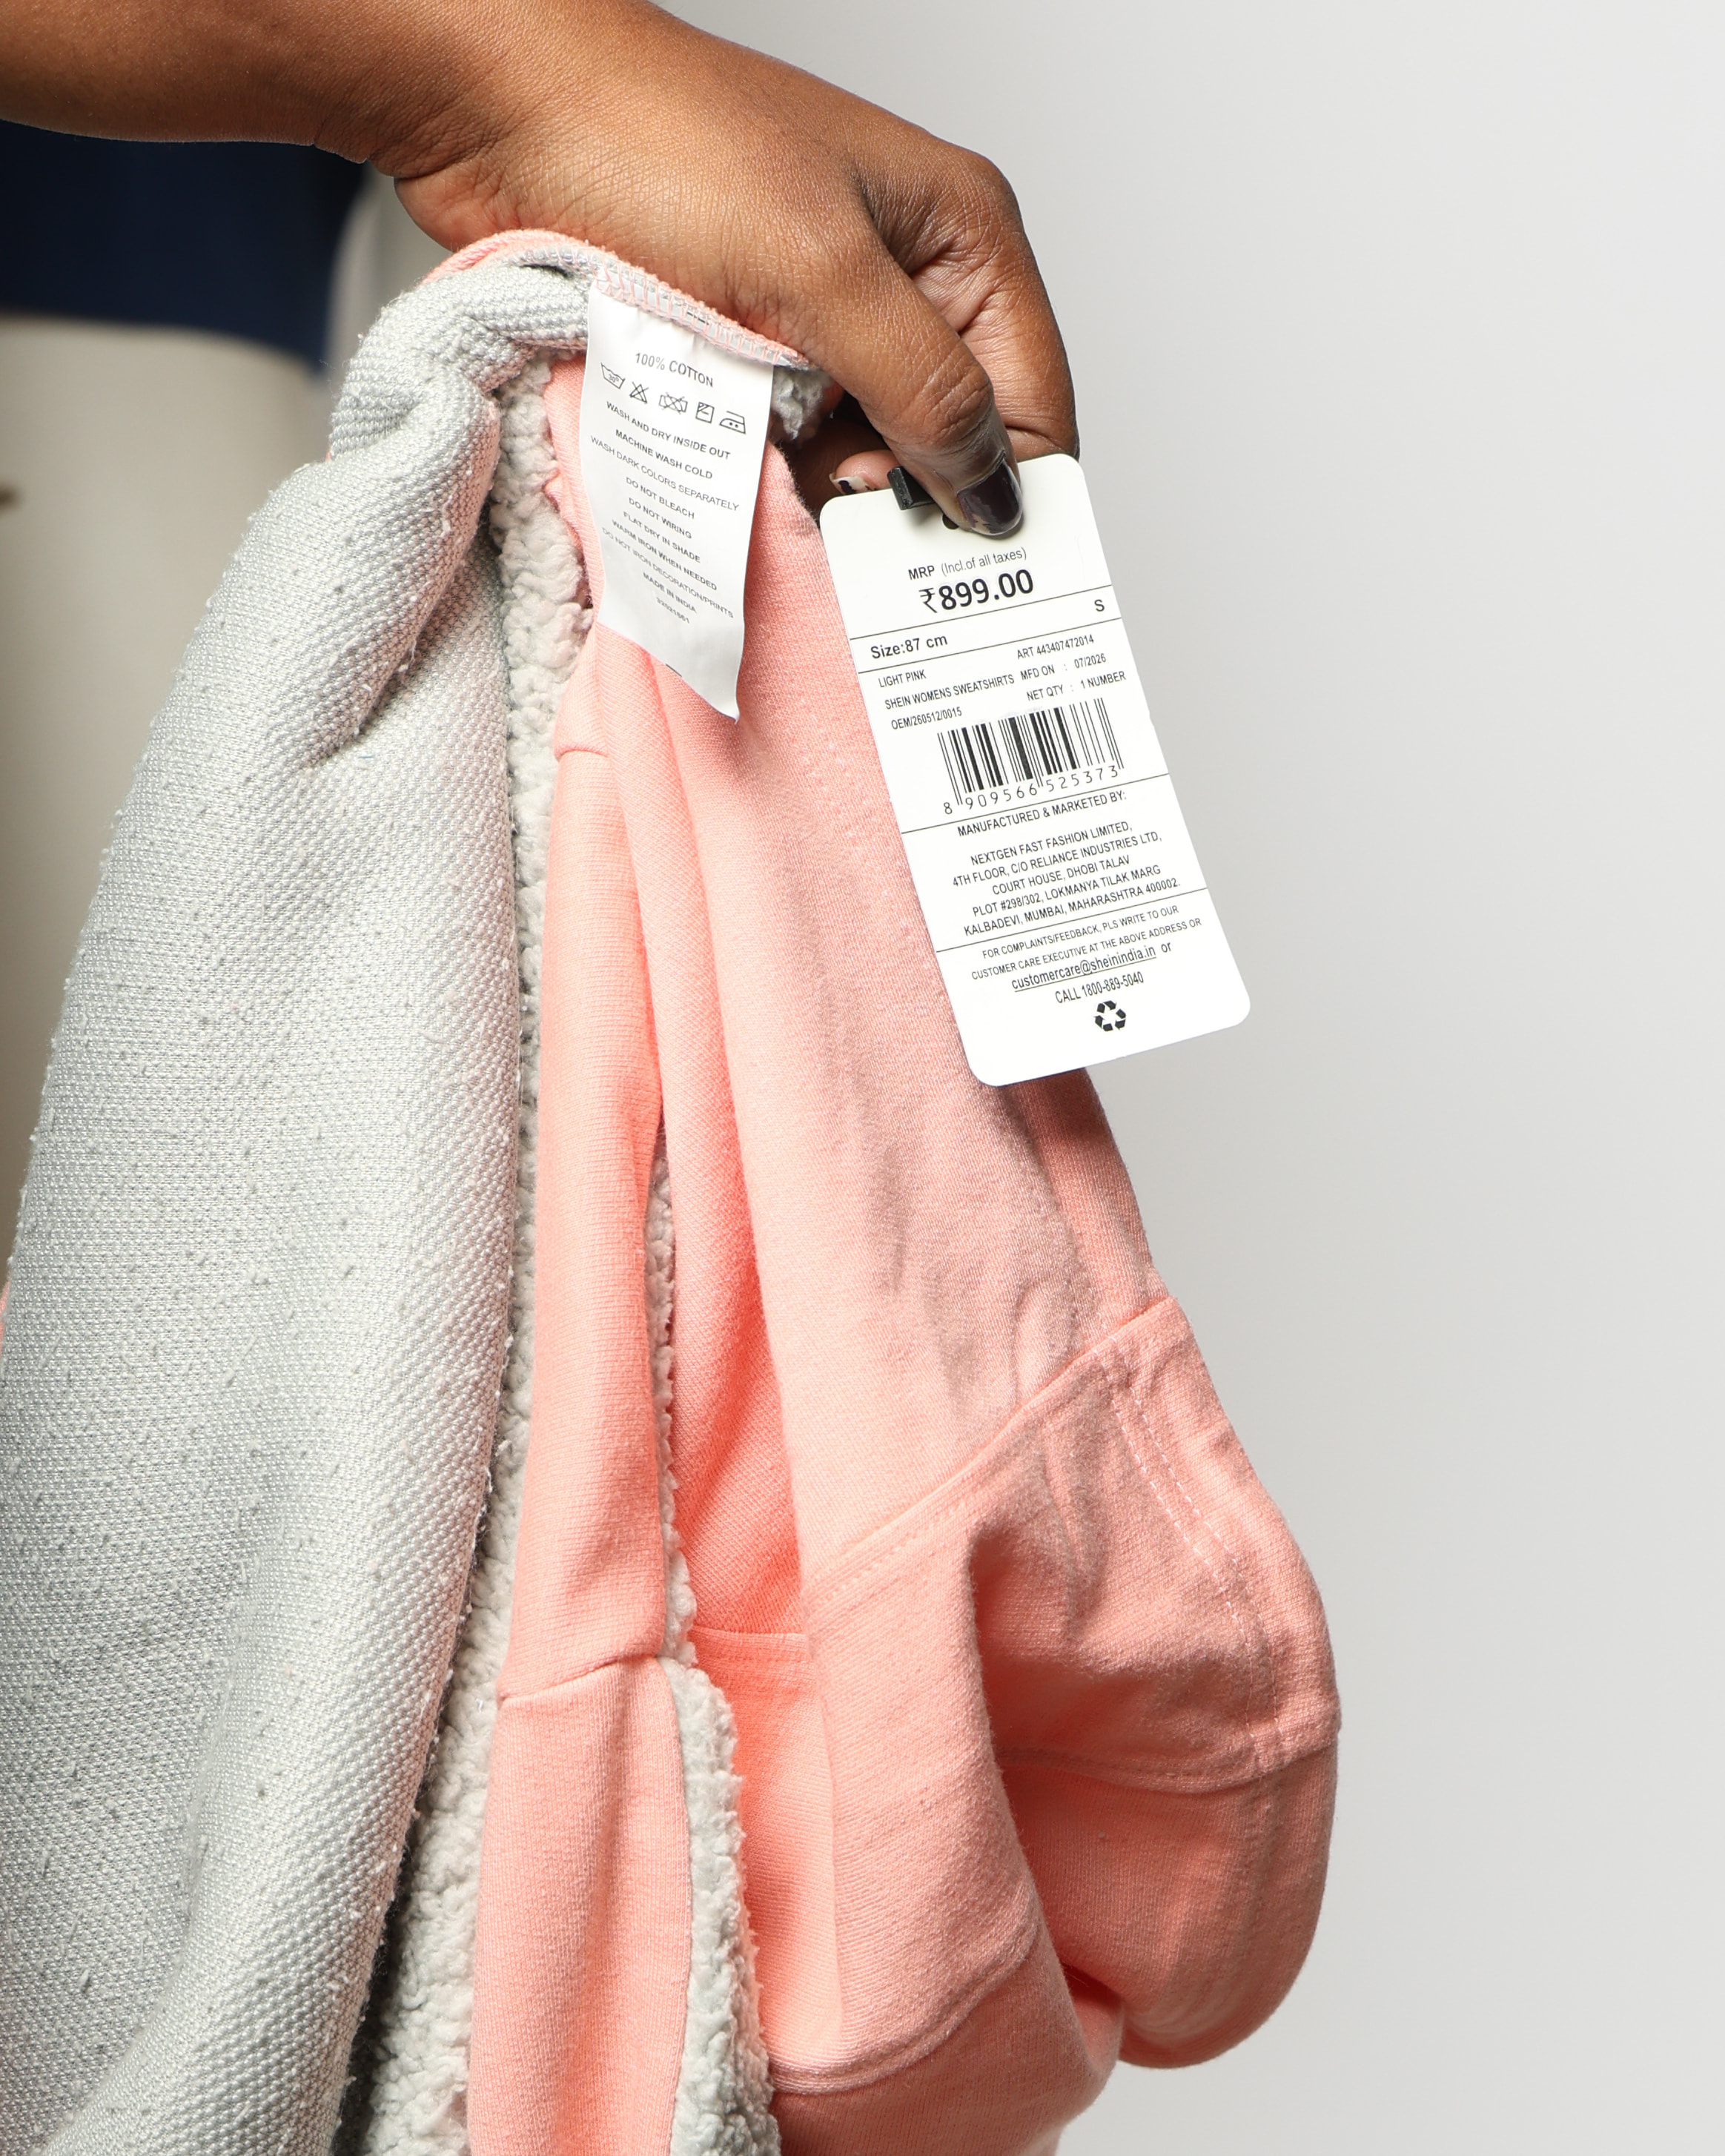
A kangaroo pocket that was never there 1 of 5 outputs replaced
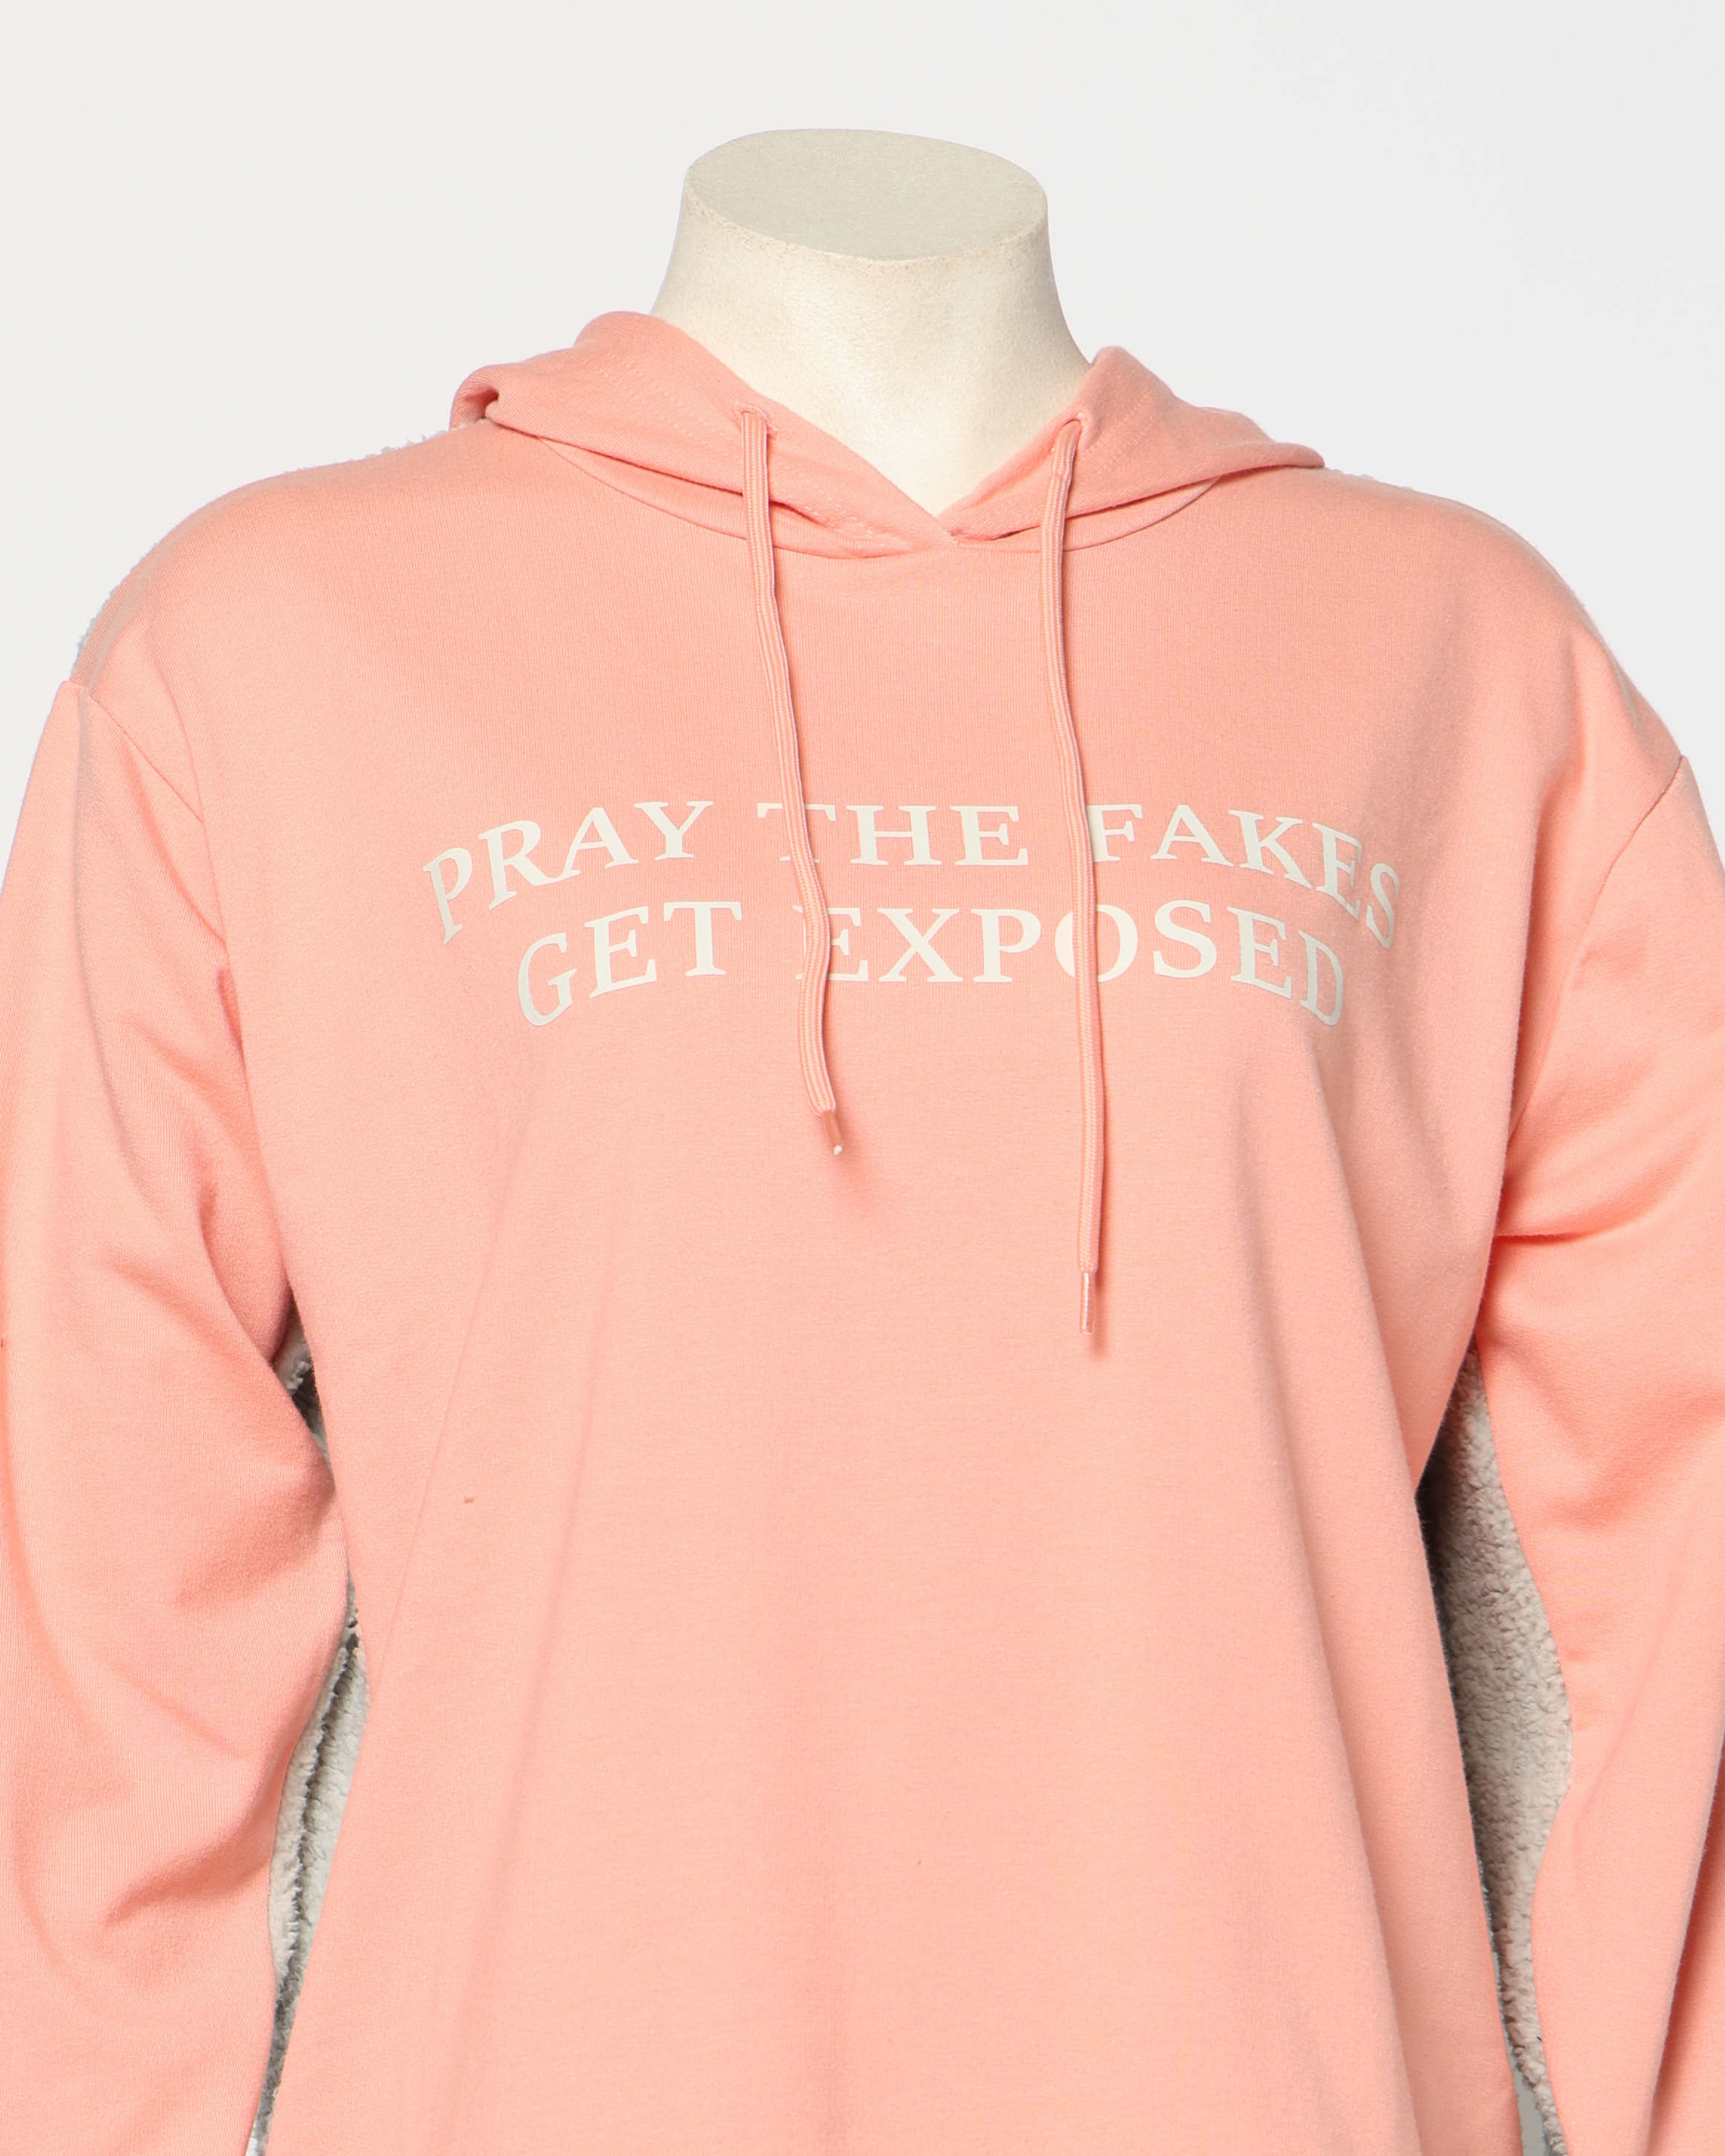
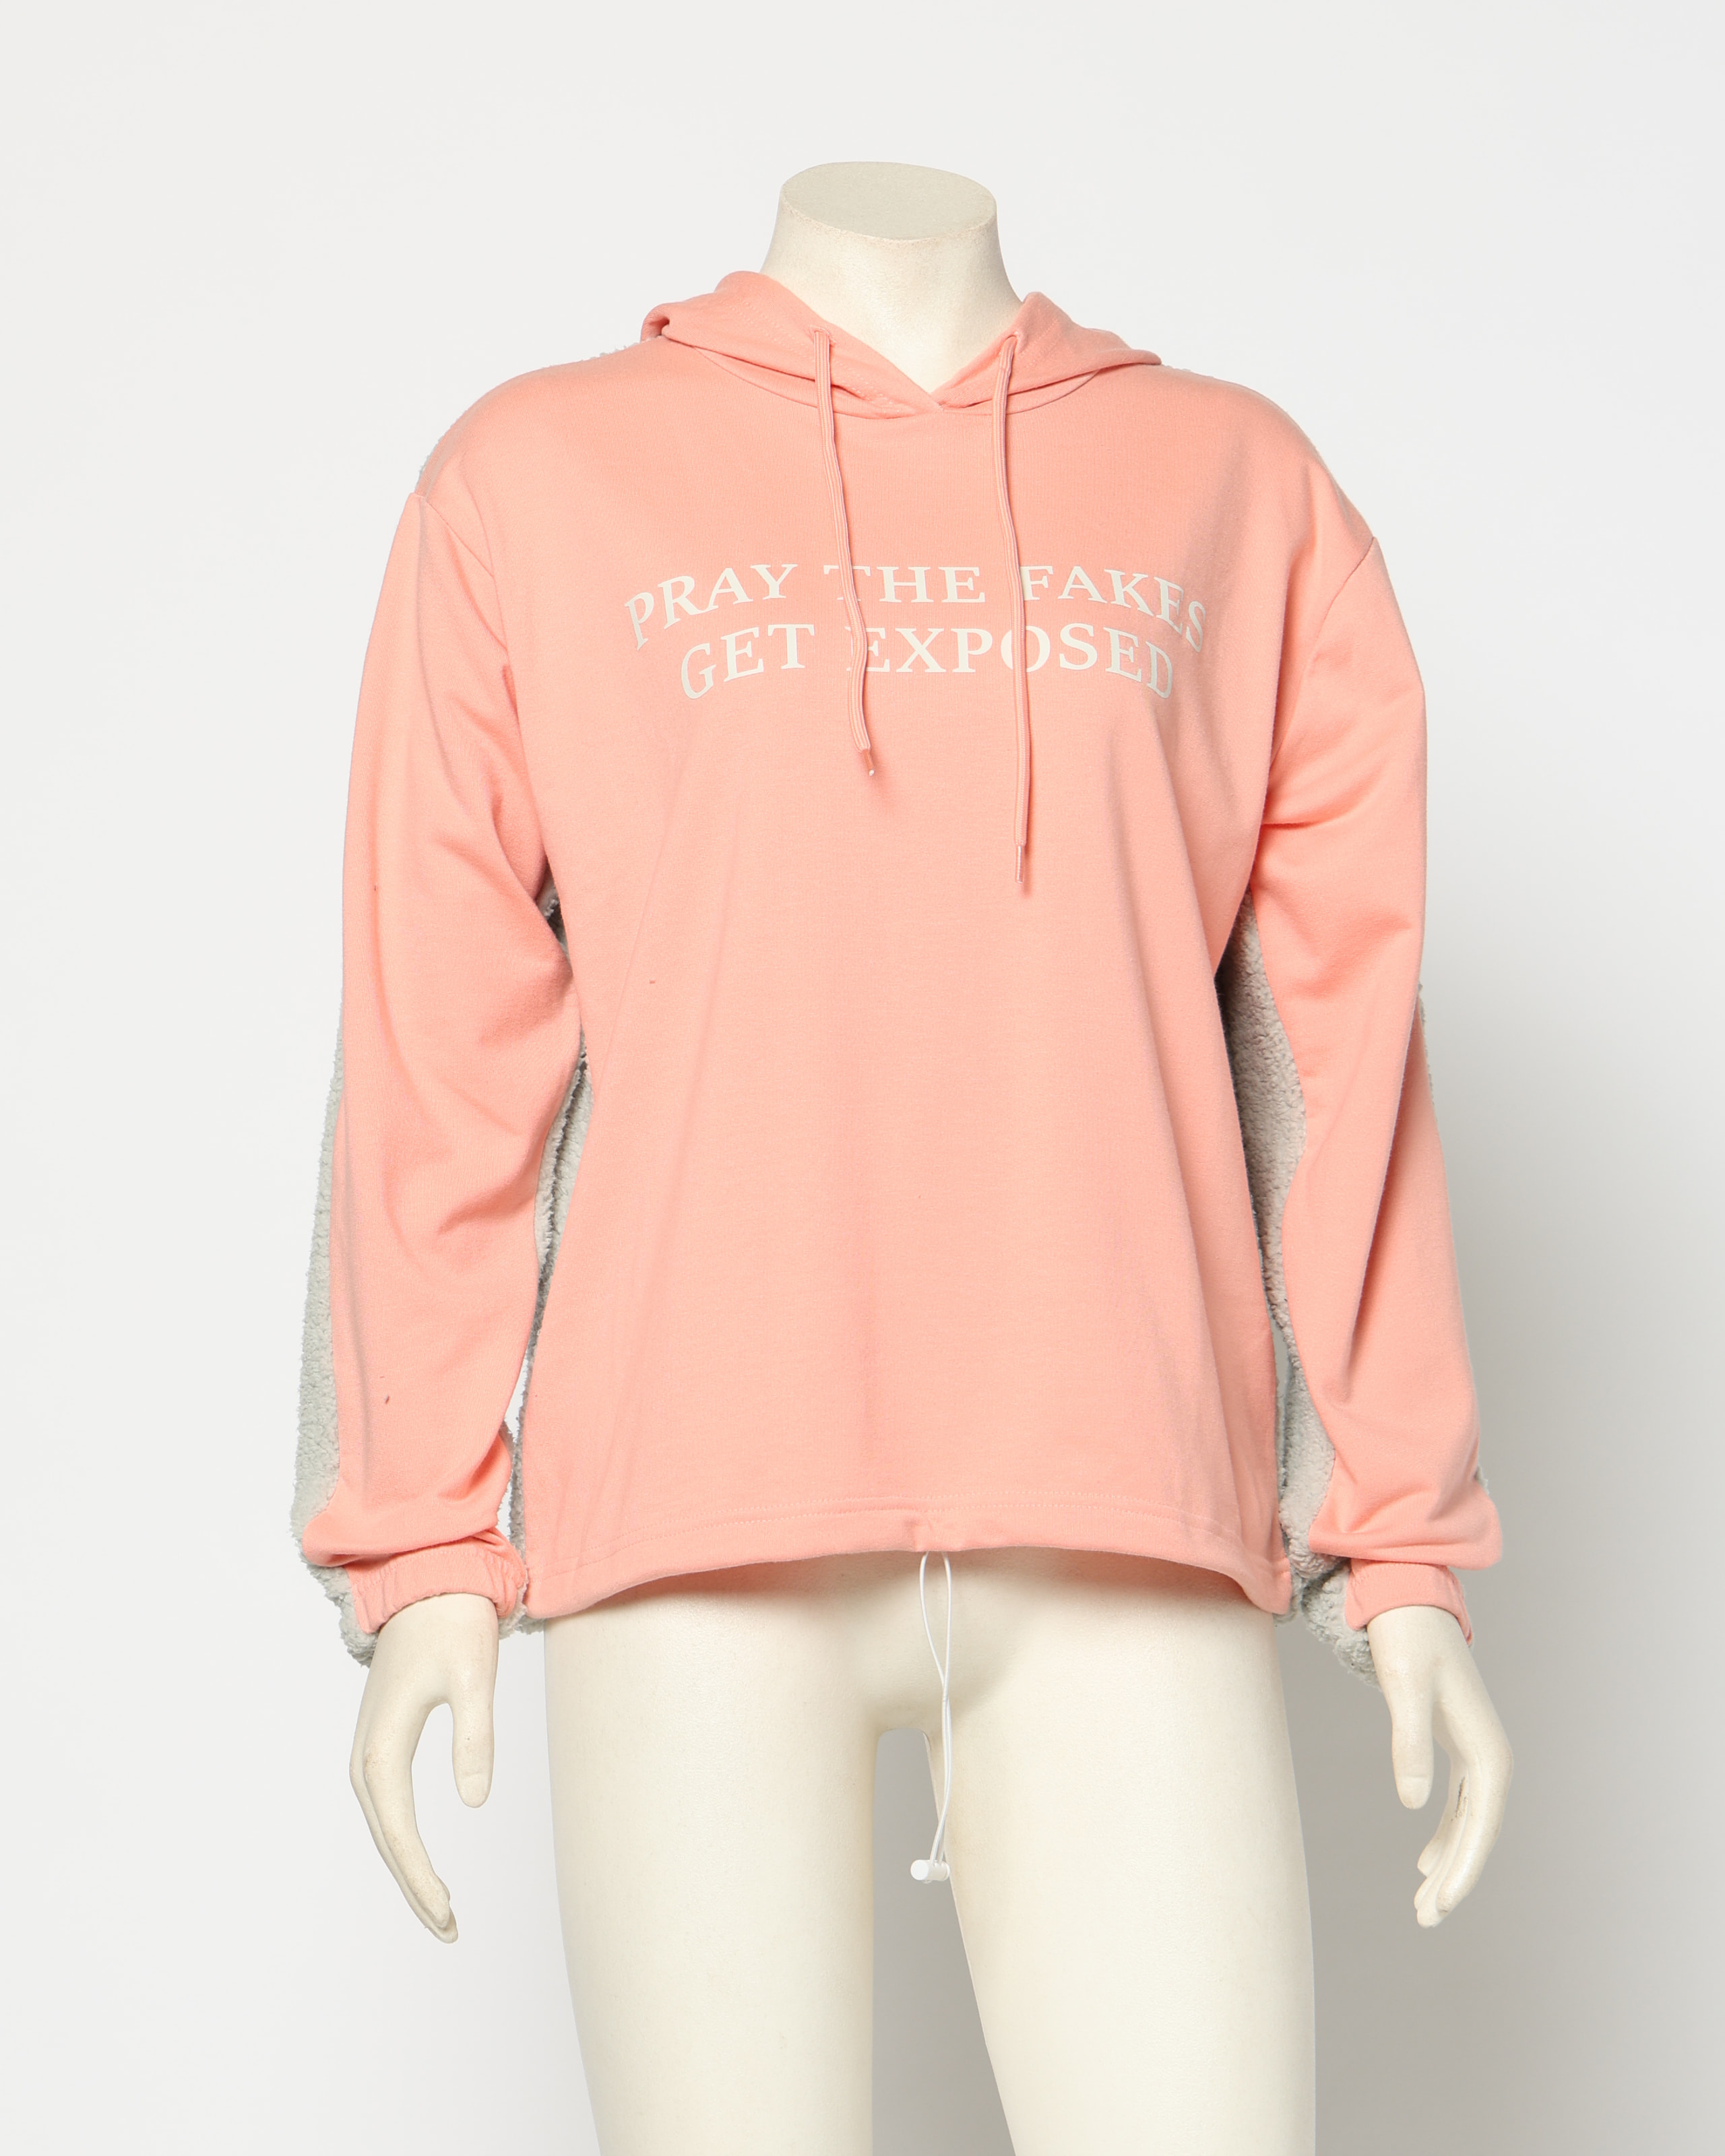
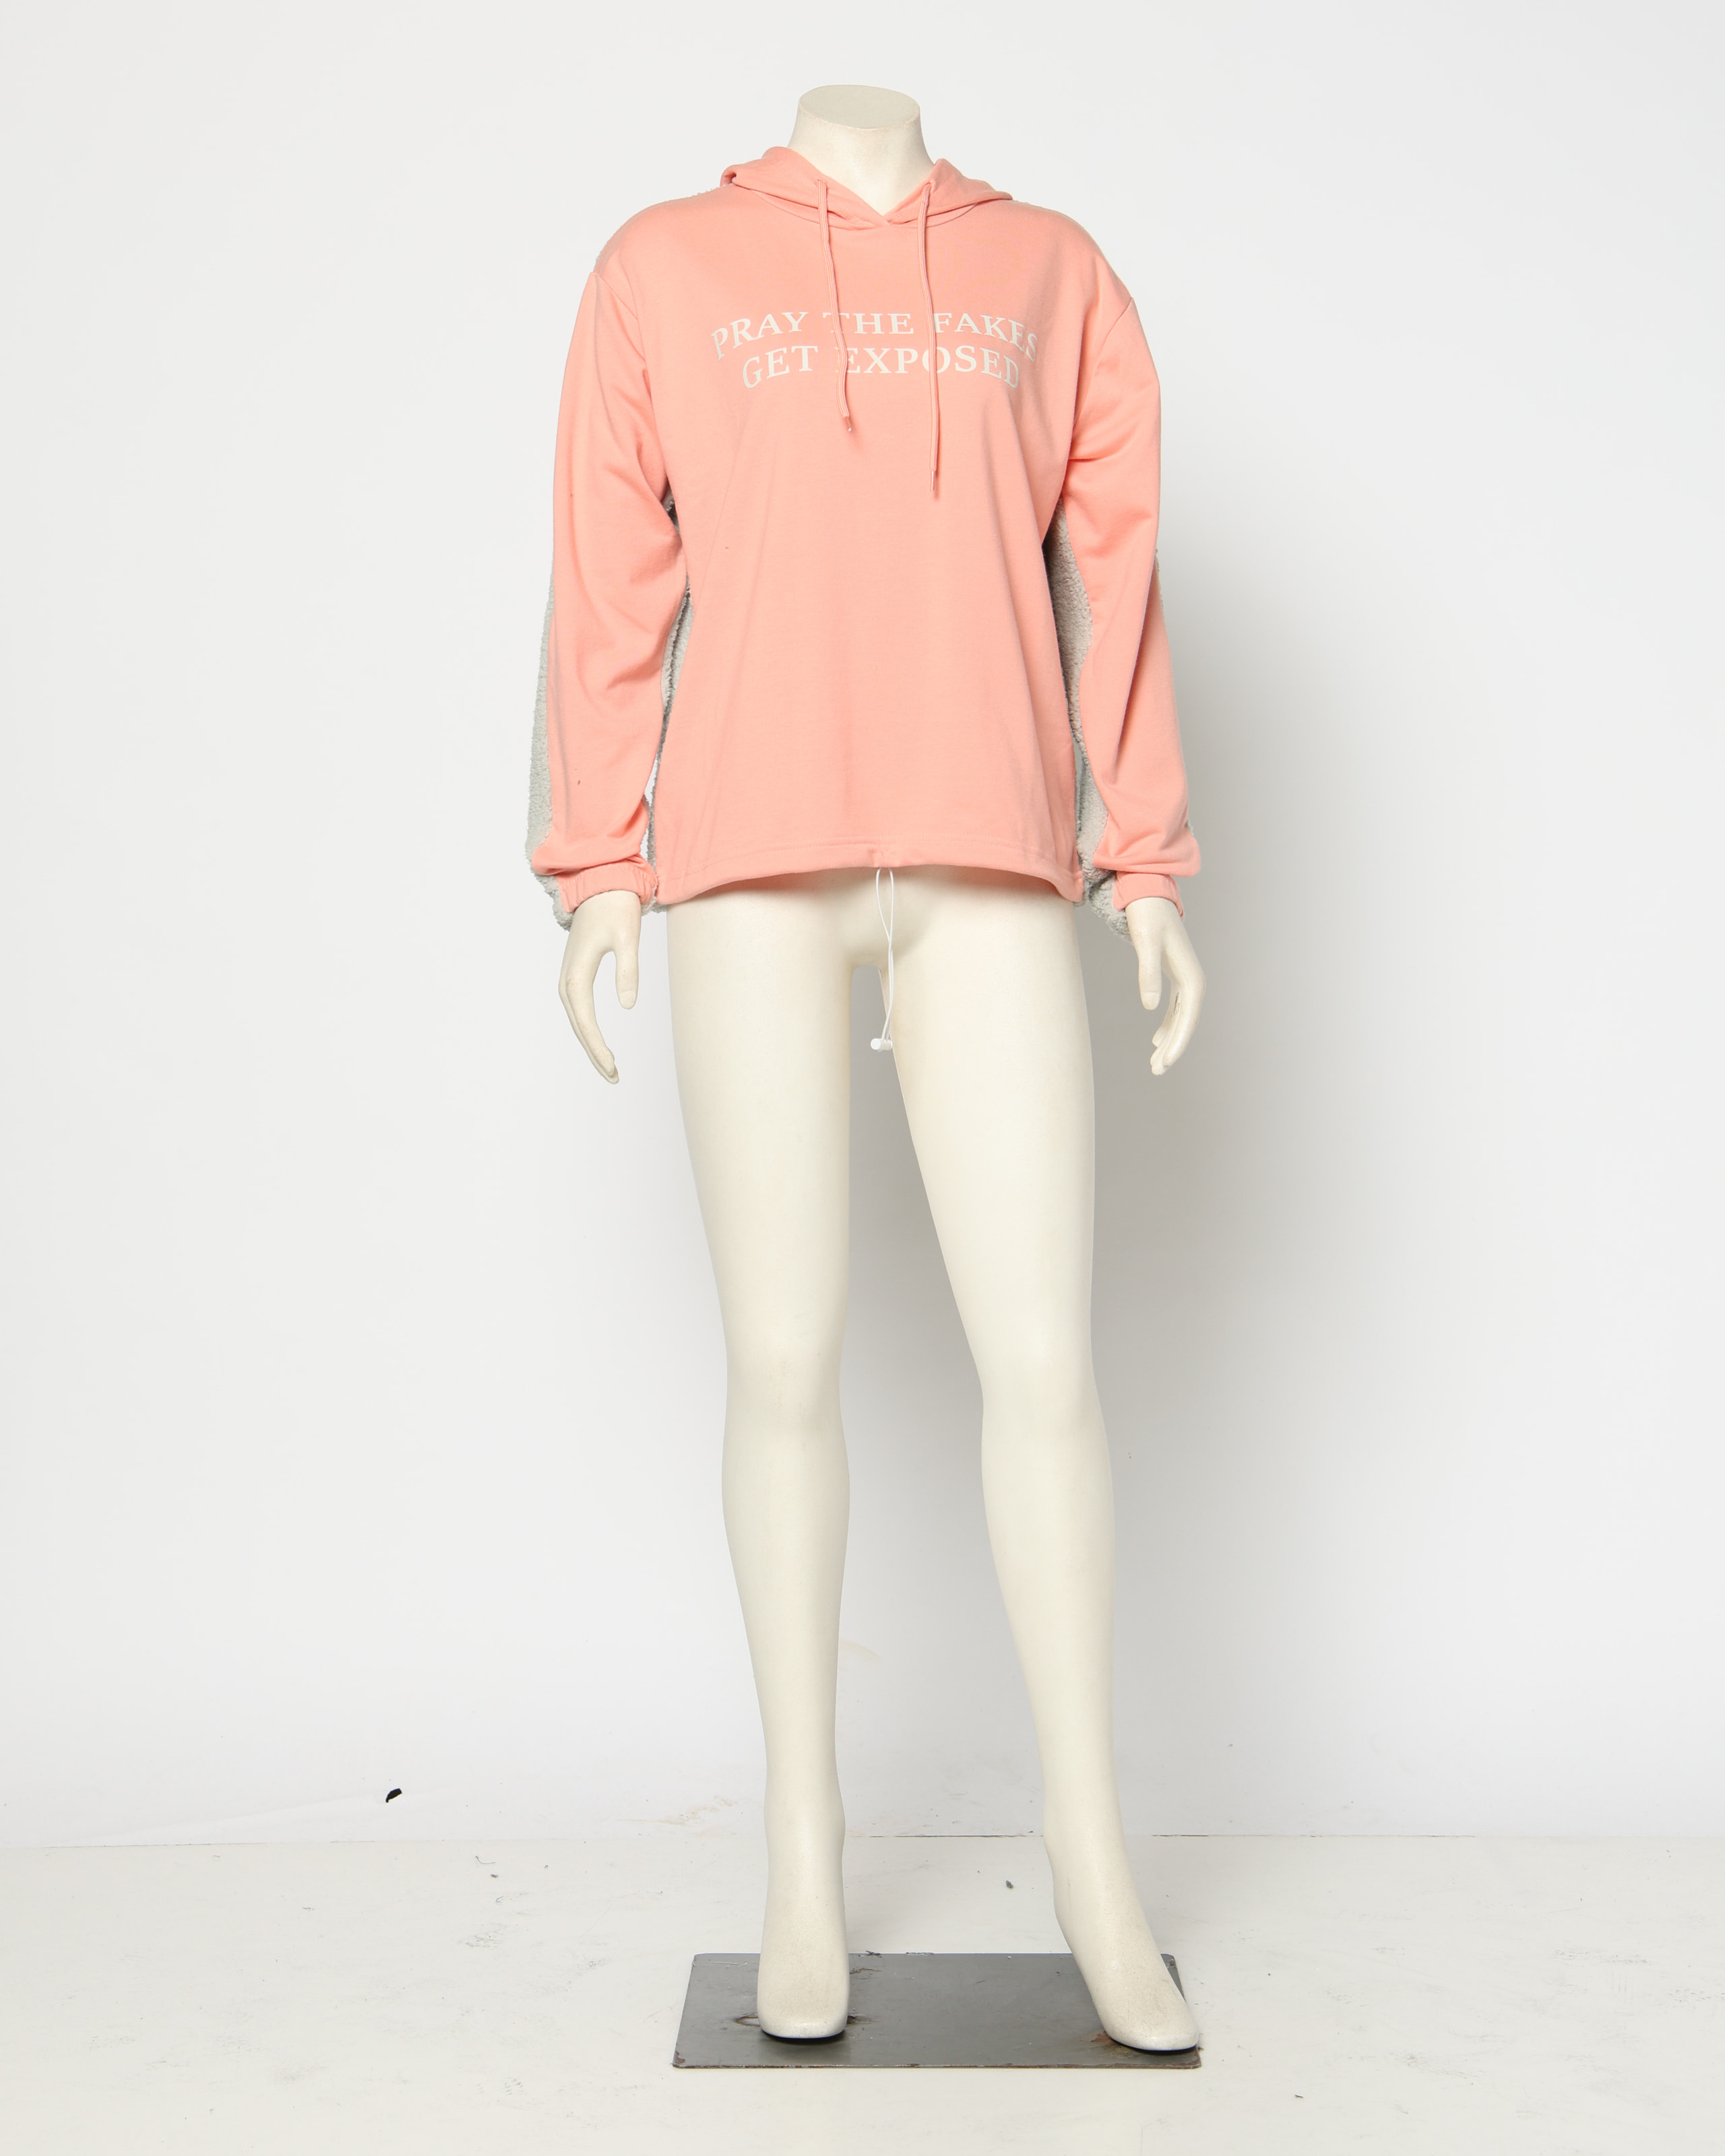
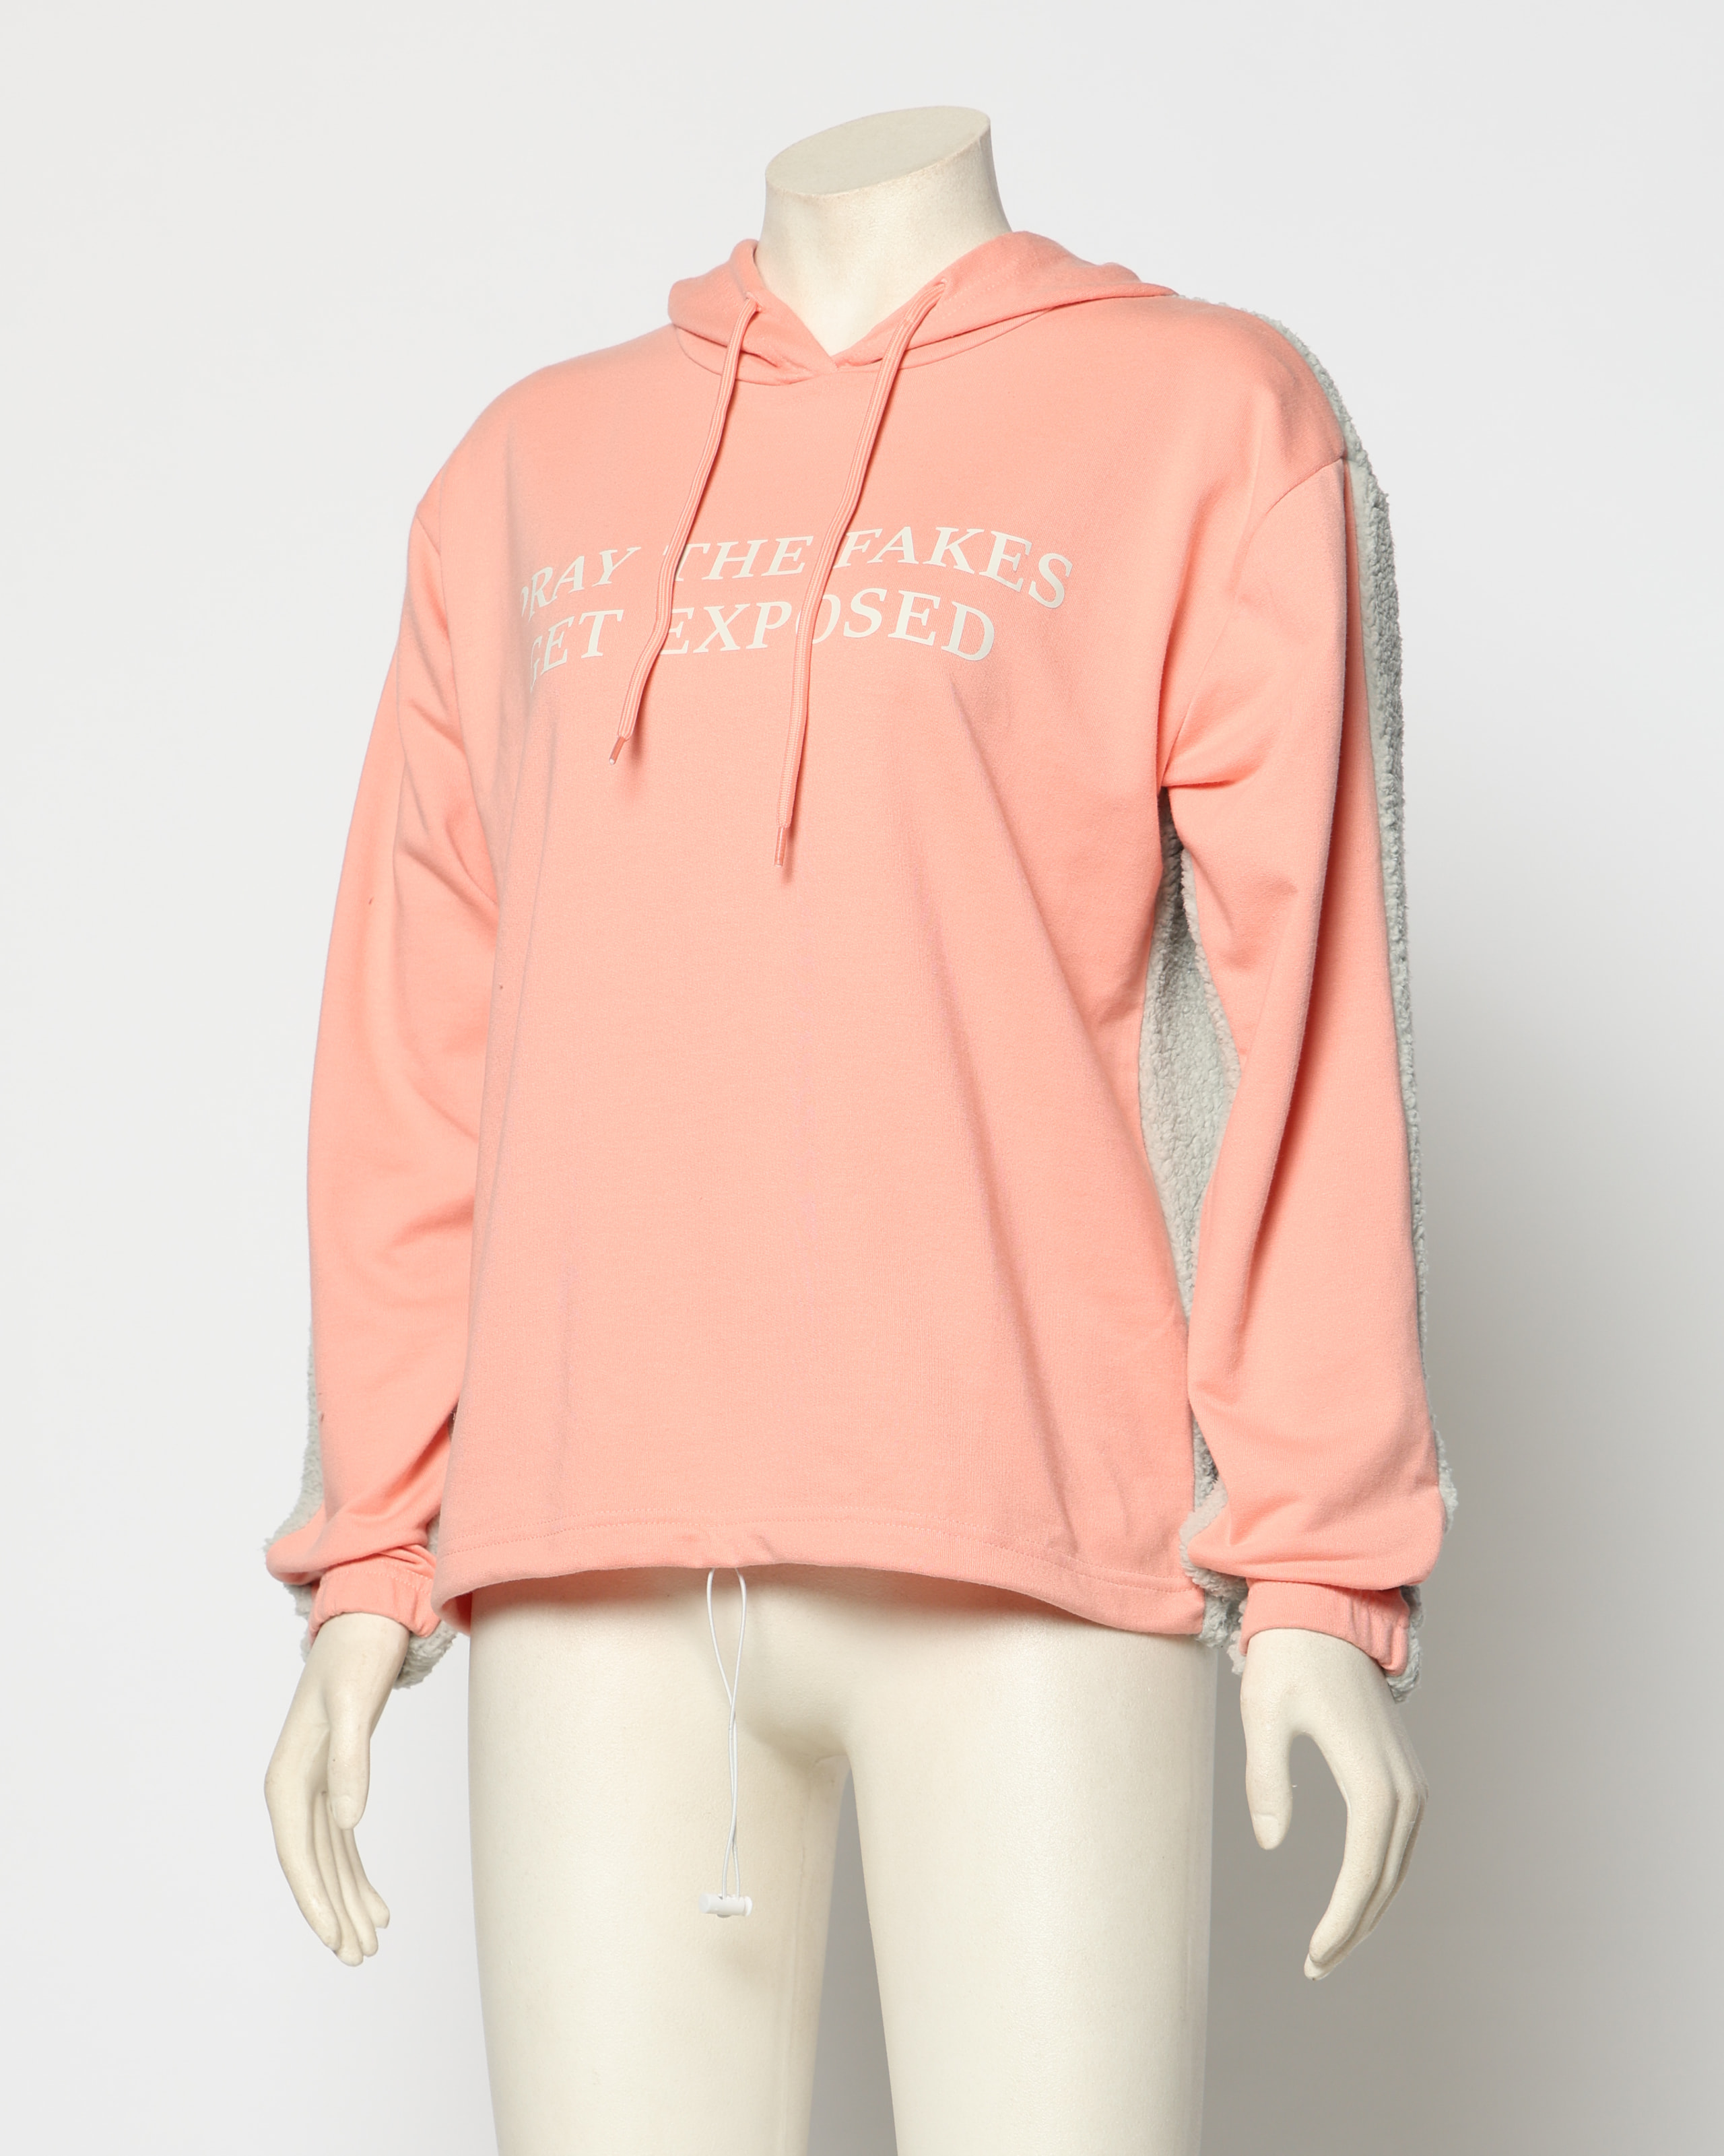
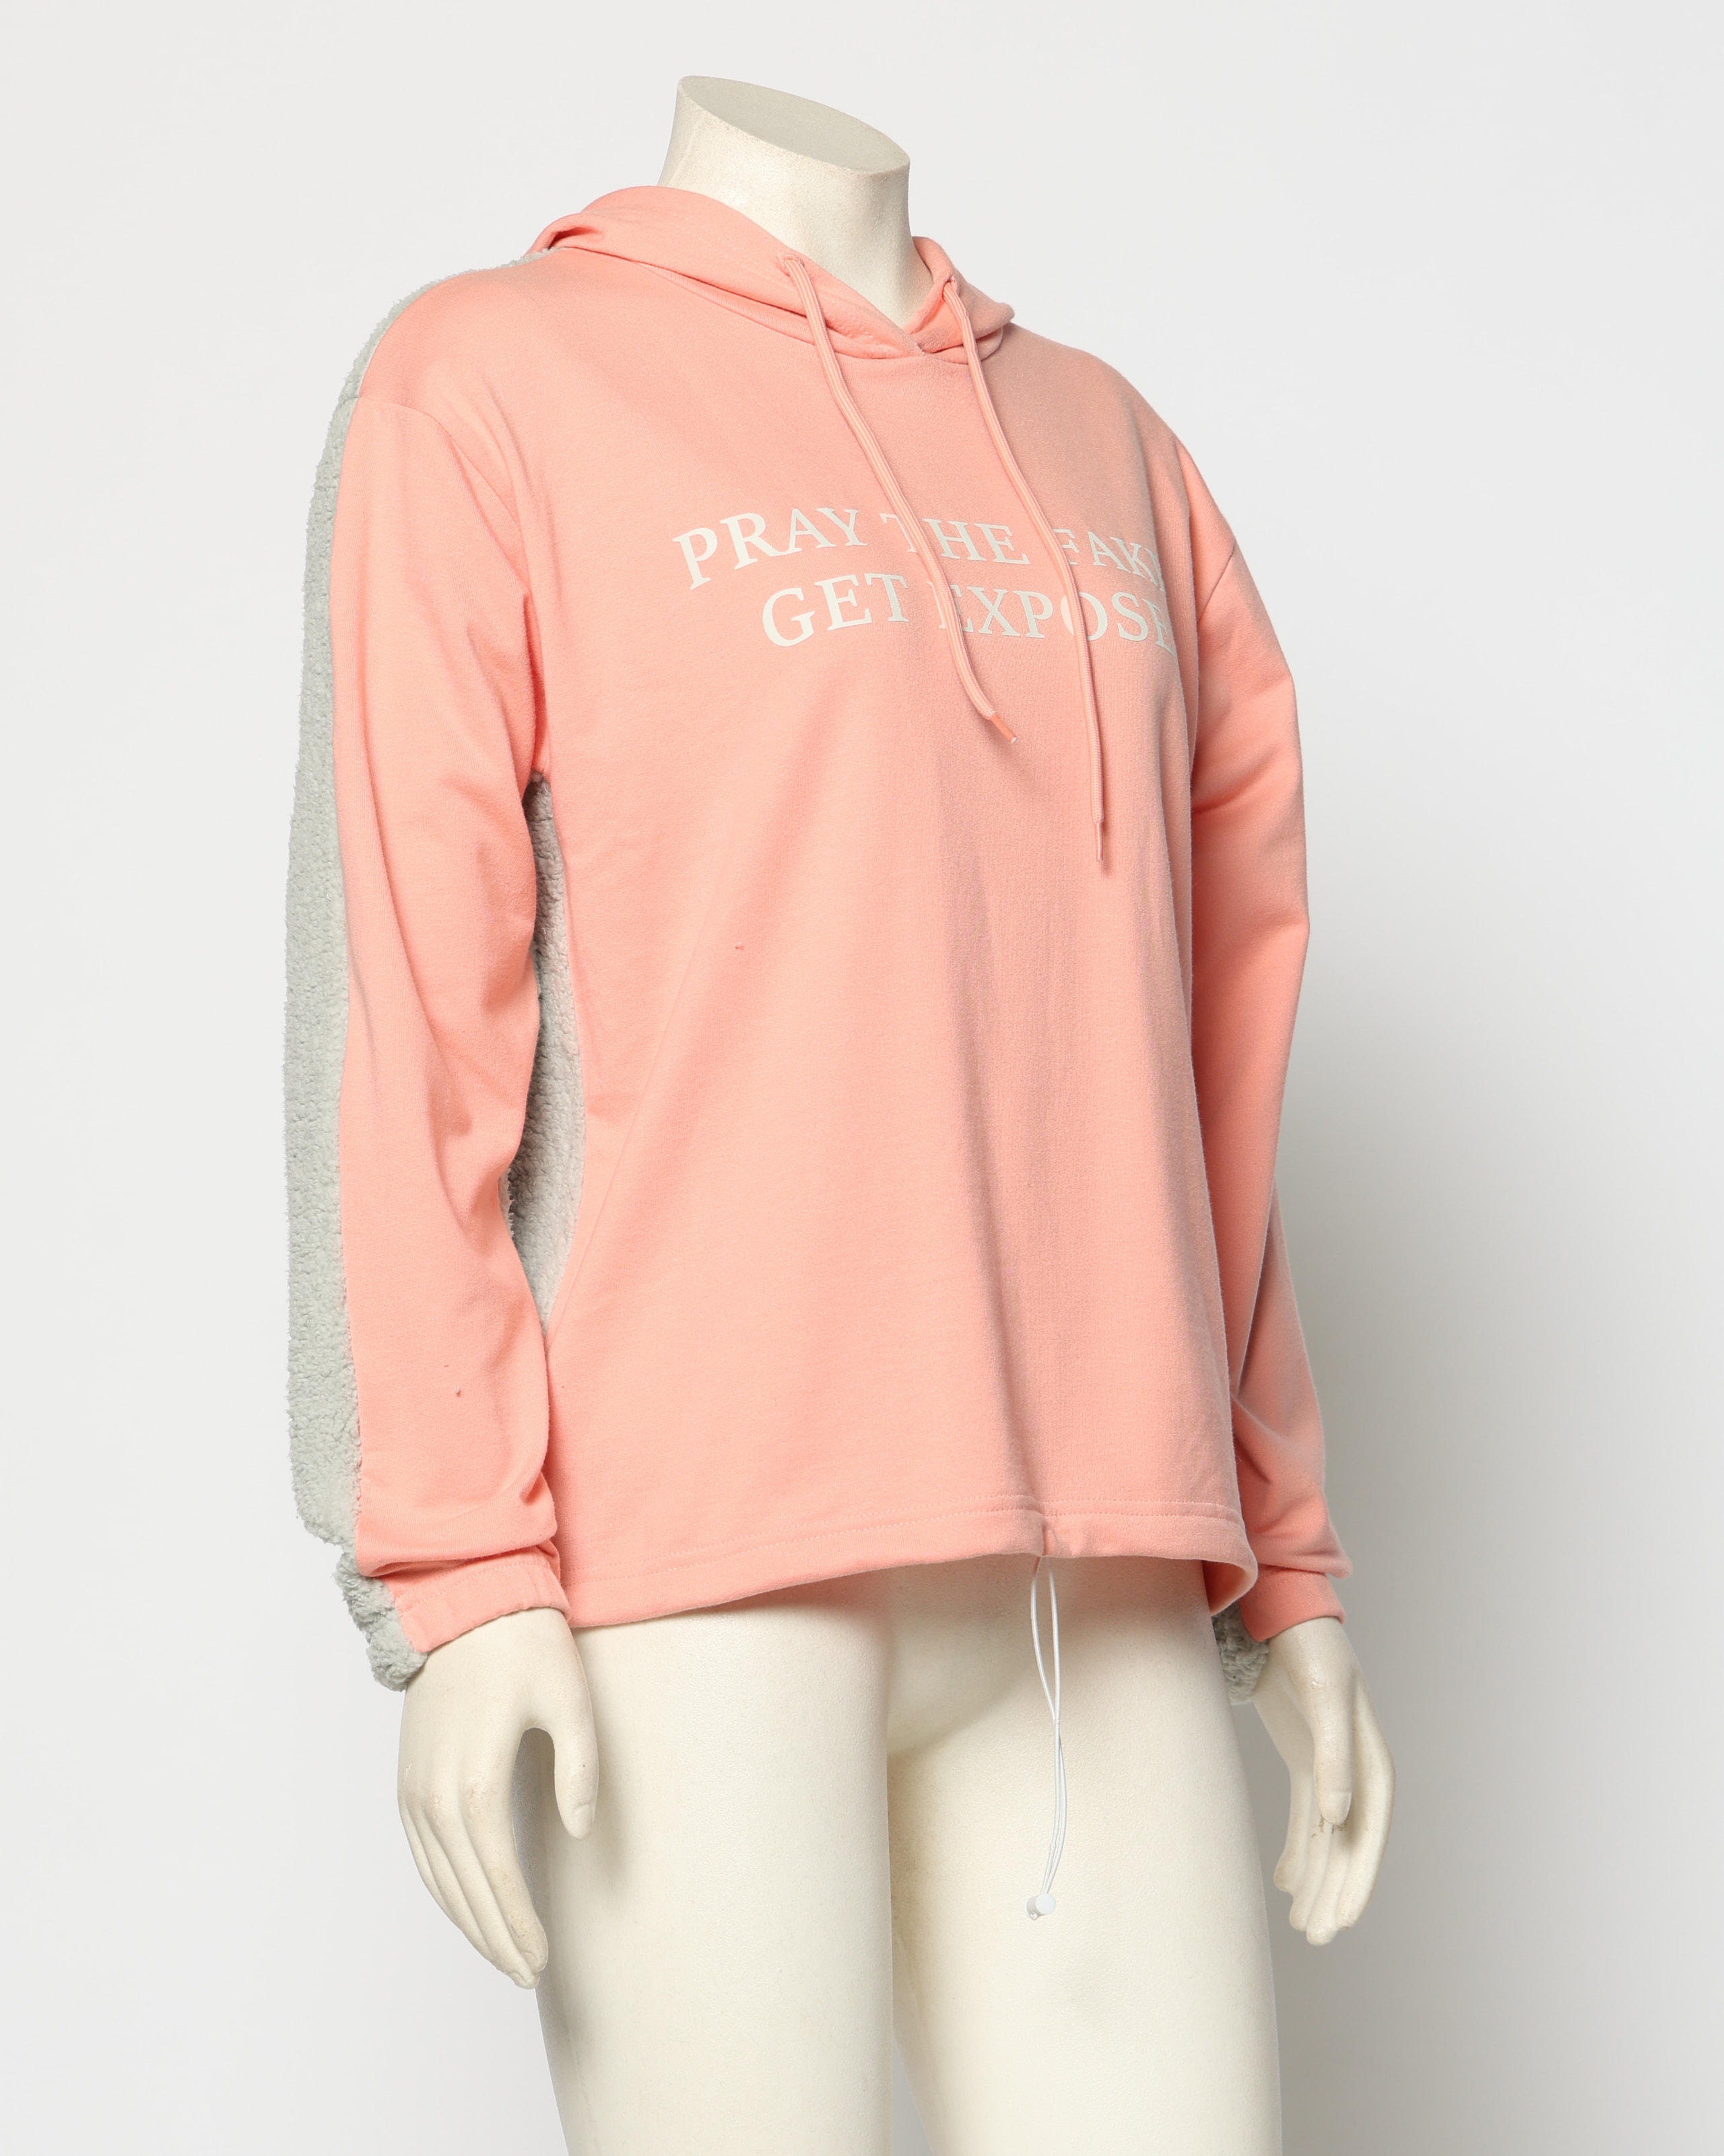
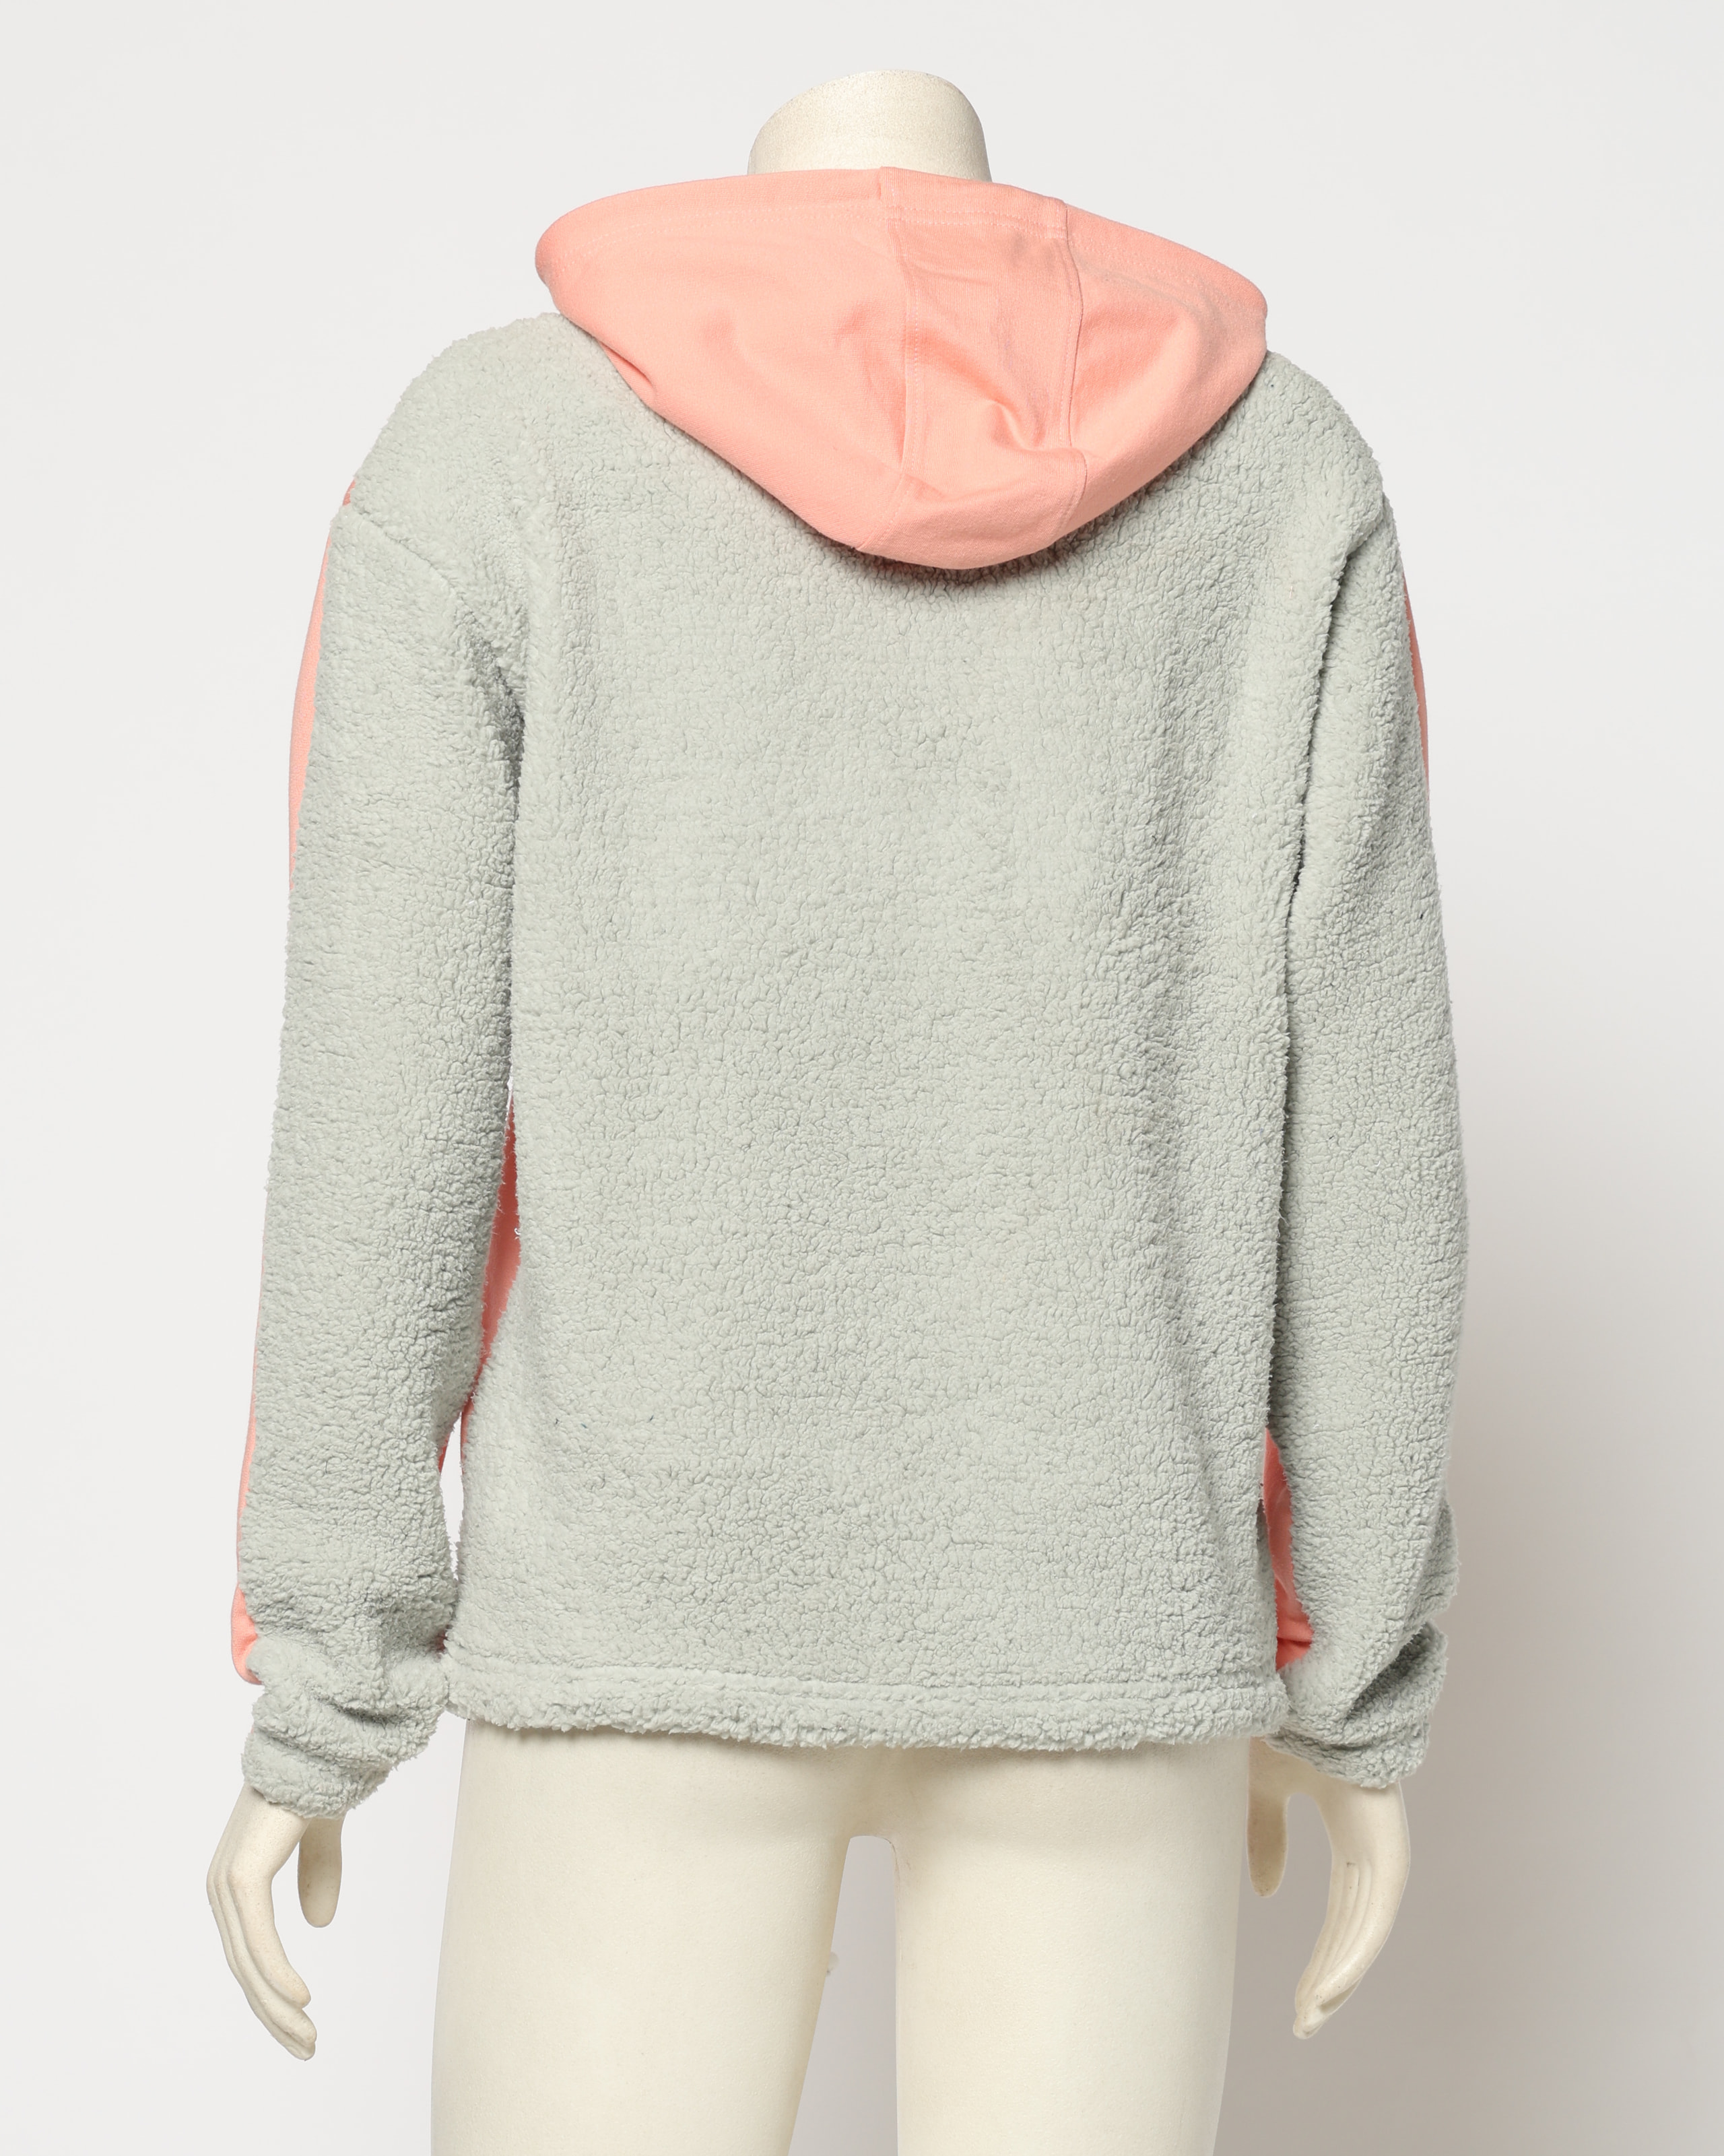
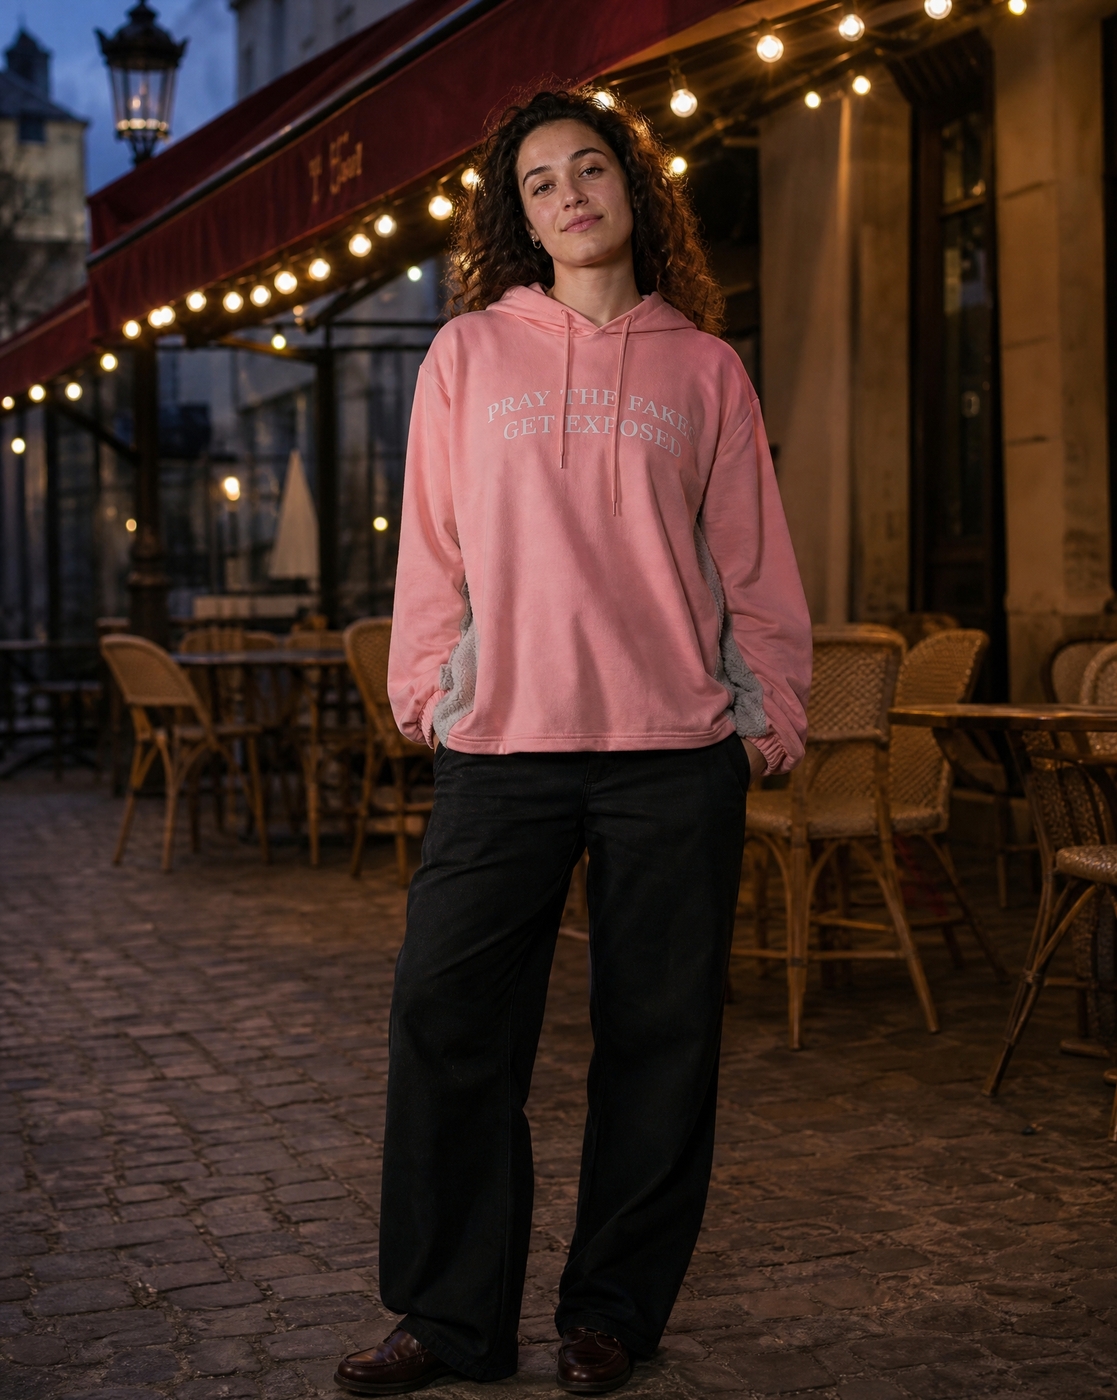
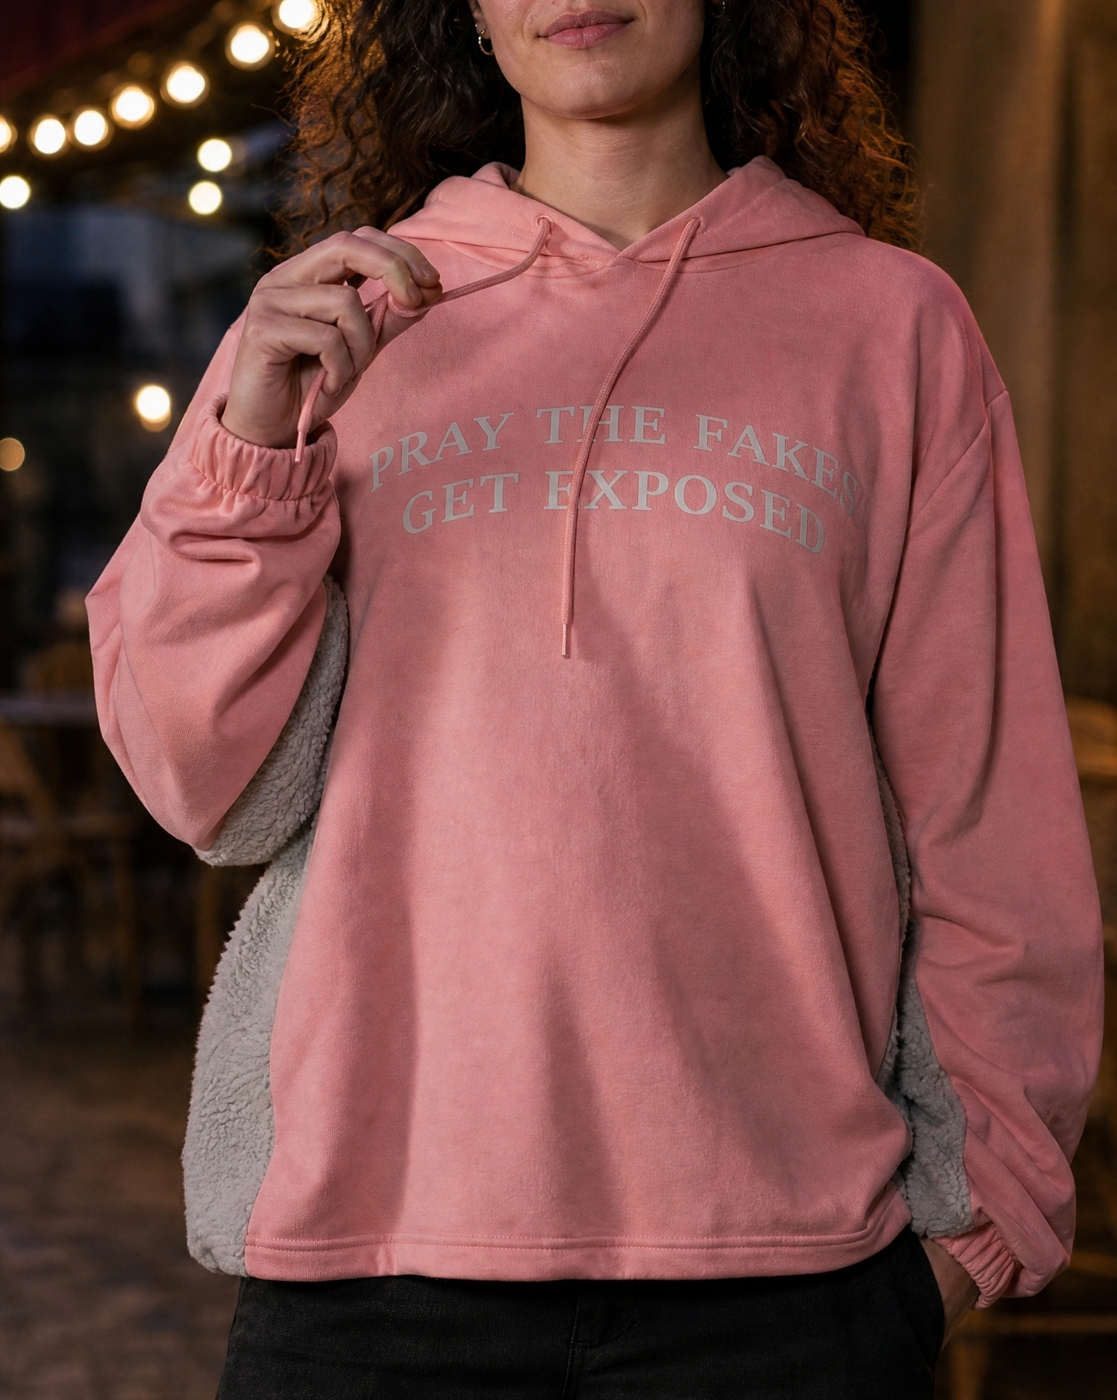
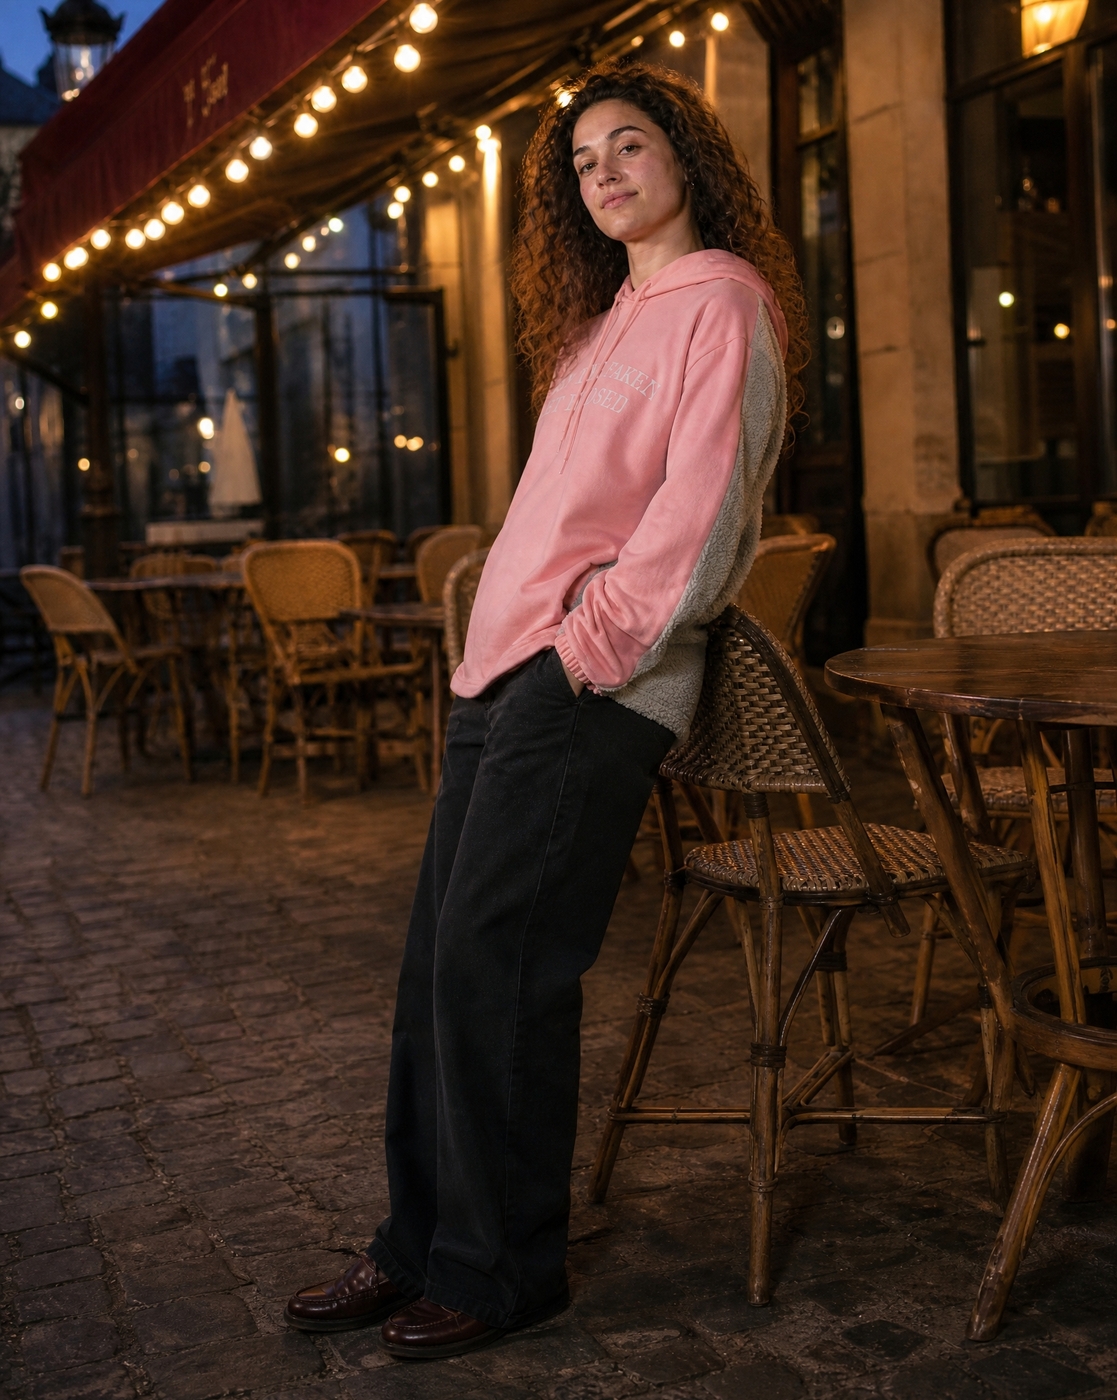
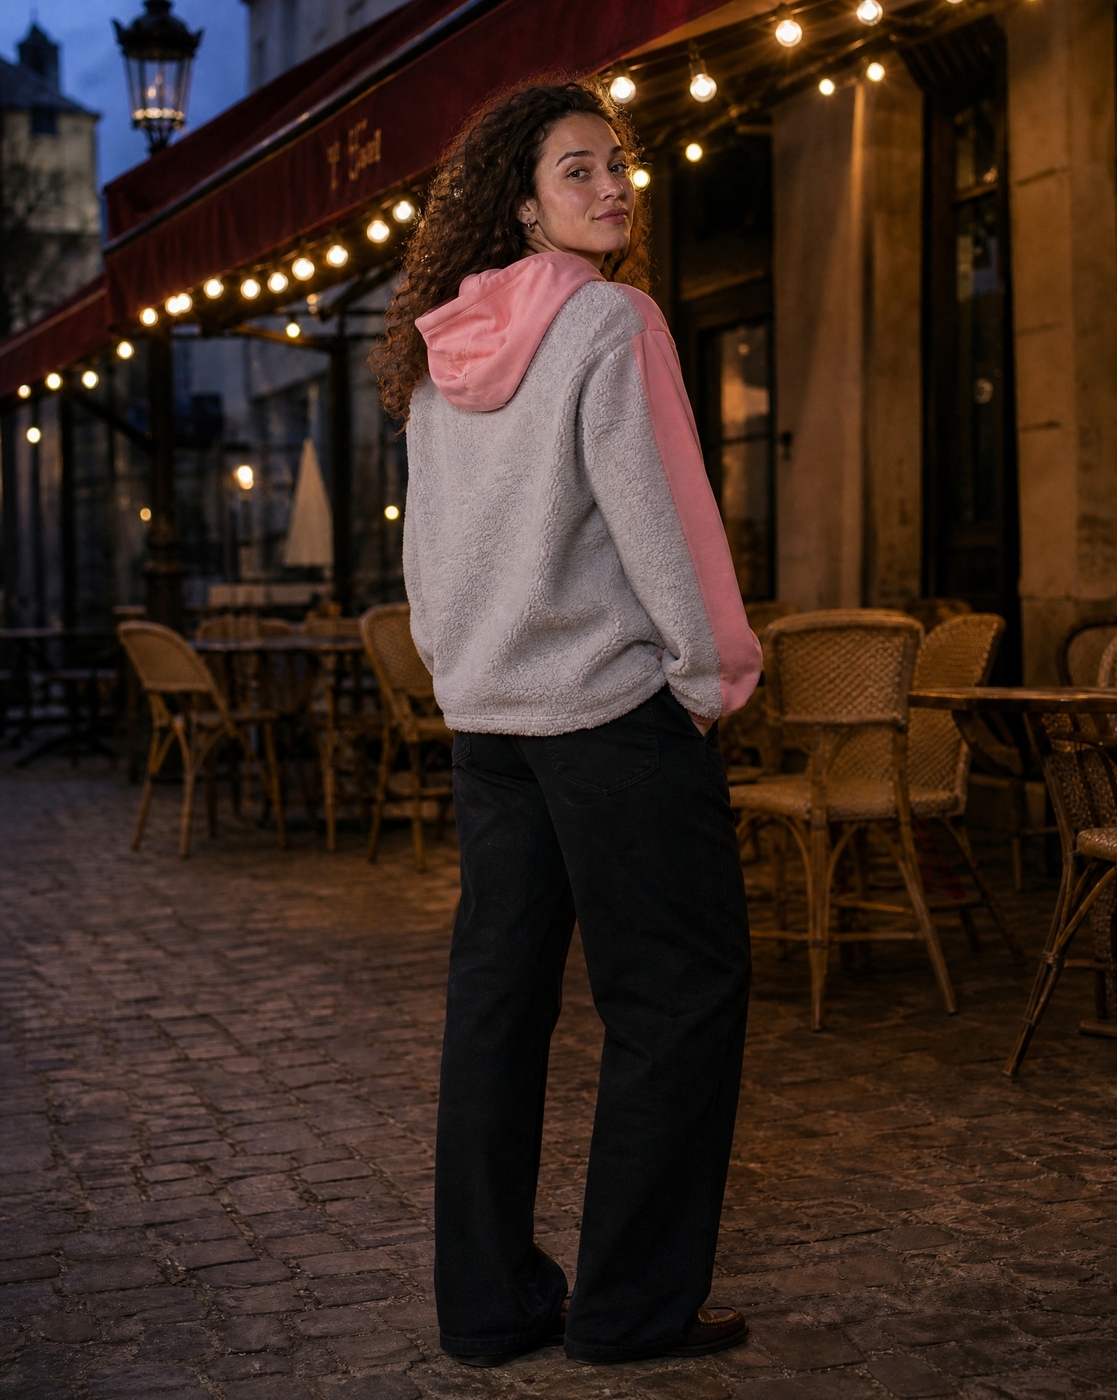
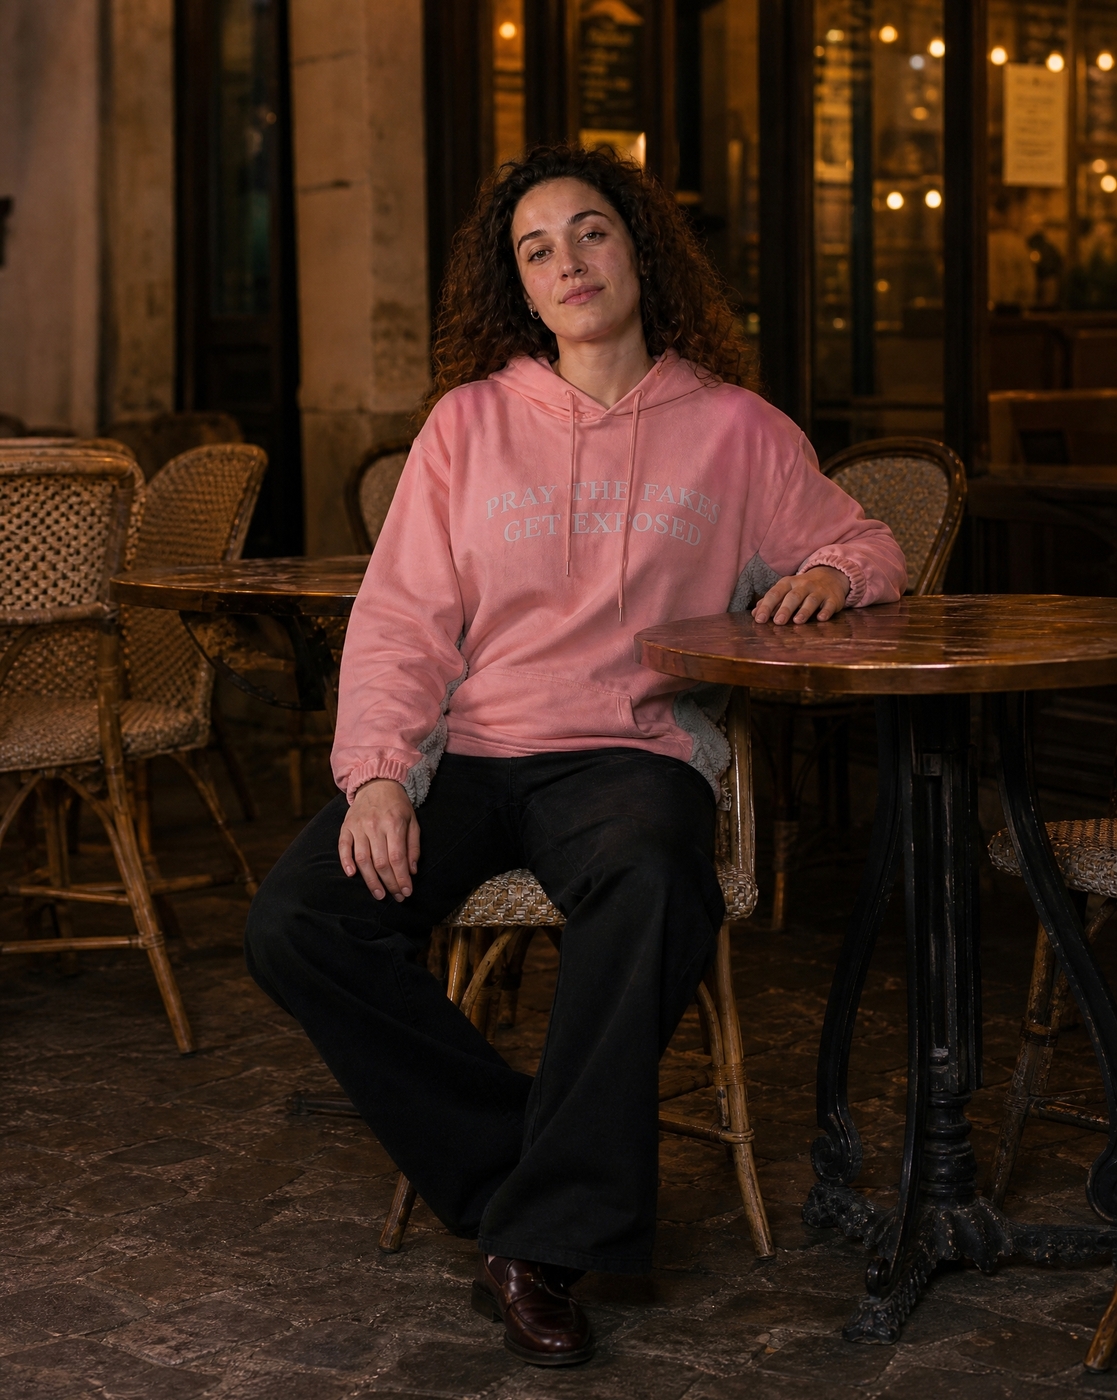
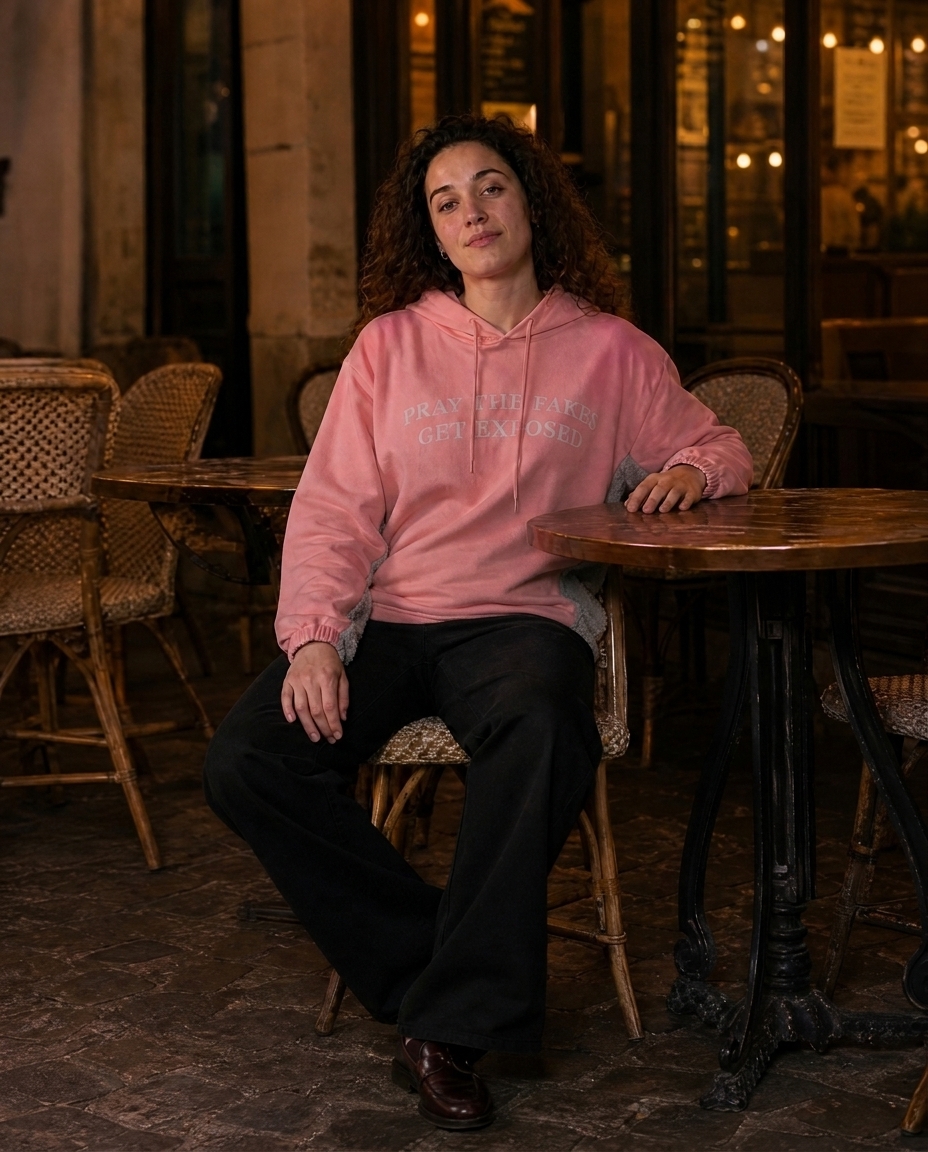
A light pink hoodie with a plain front body. Four of five outputs matched the input. The fifth added a kangaroo pouch pocket stitched across the lower front. The agent flagged it on garment consistency and extra elements, and regenerated that one image.
Ribbed waistband flattened into a t-shirt hem 3 of 5 outputs replaced
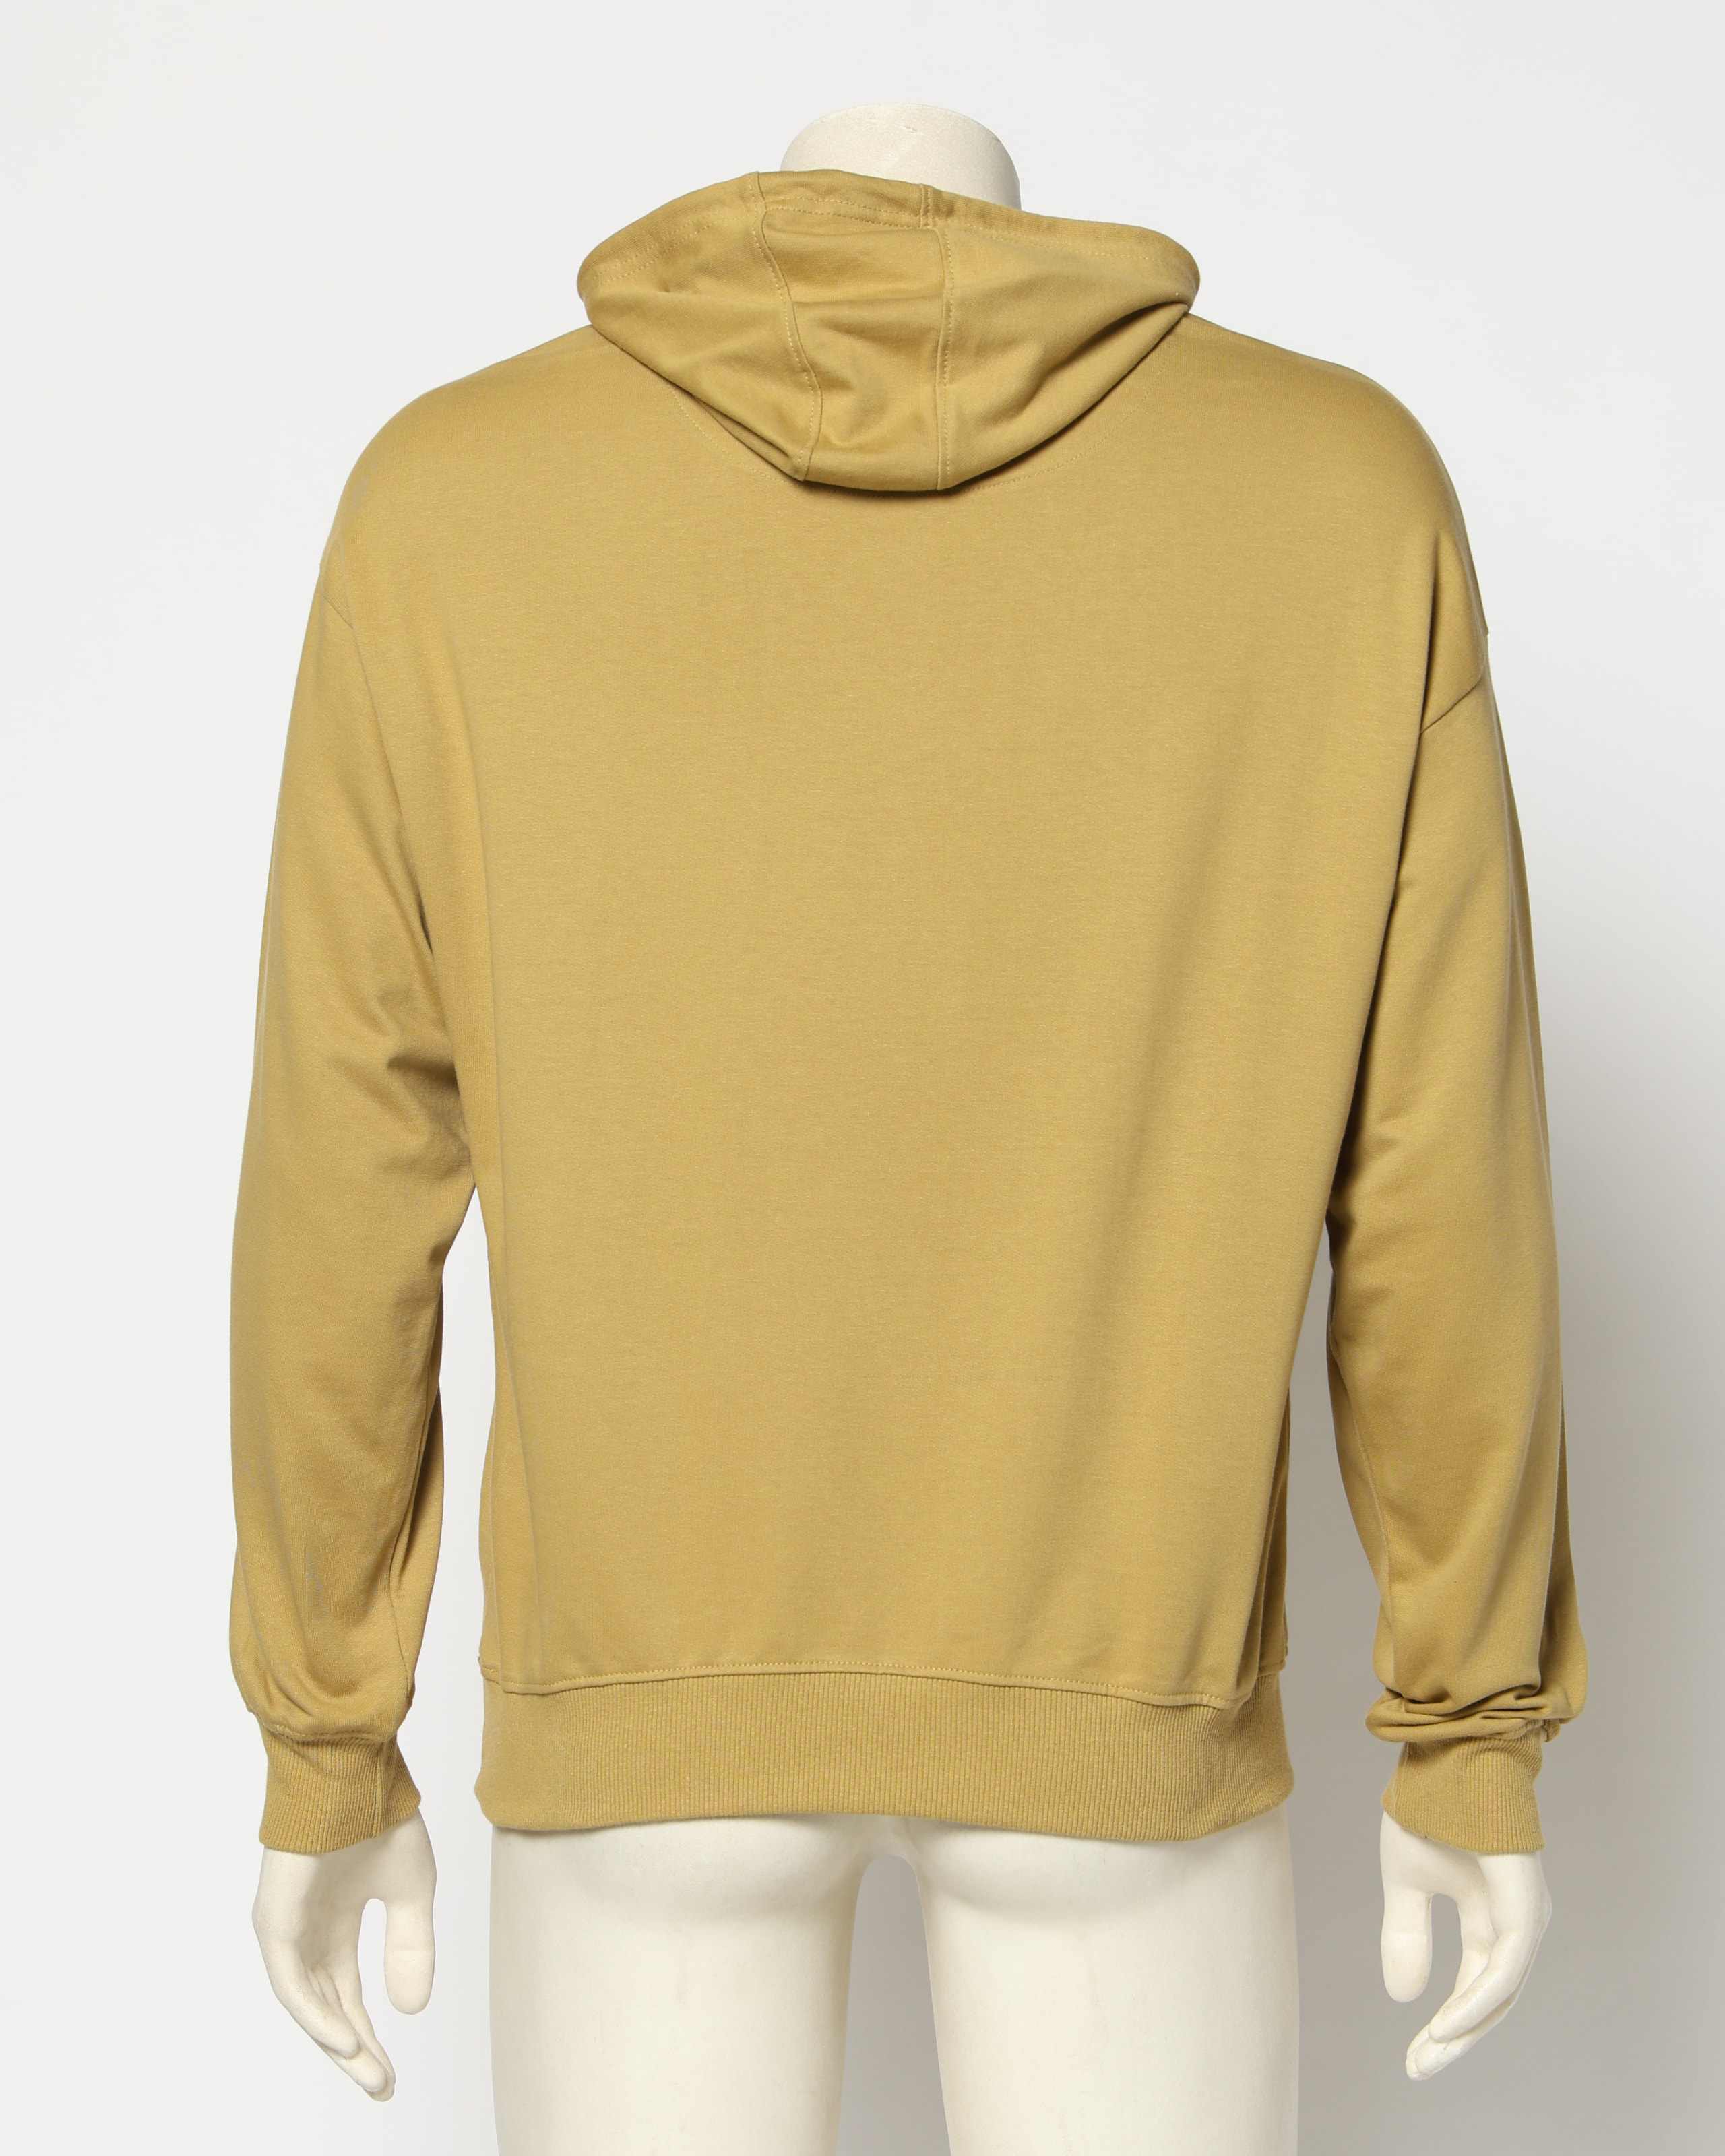
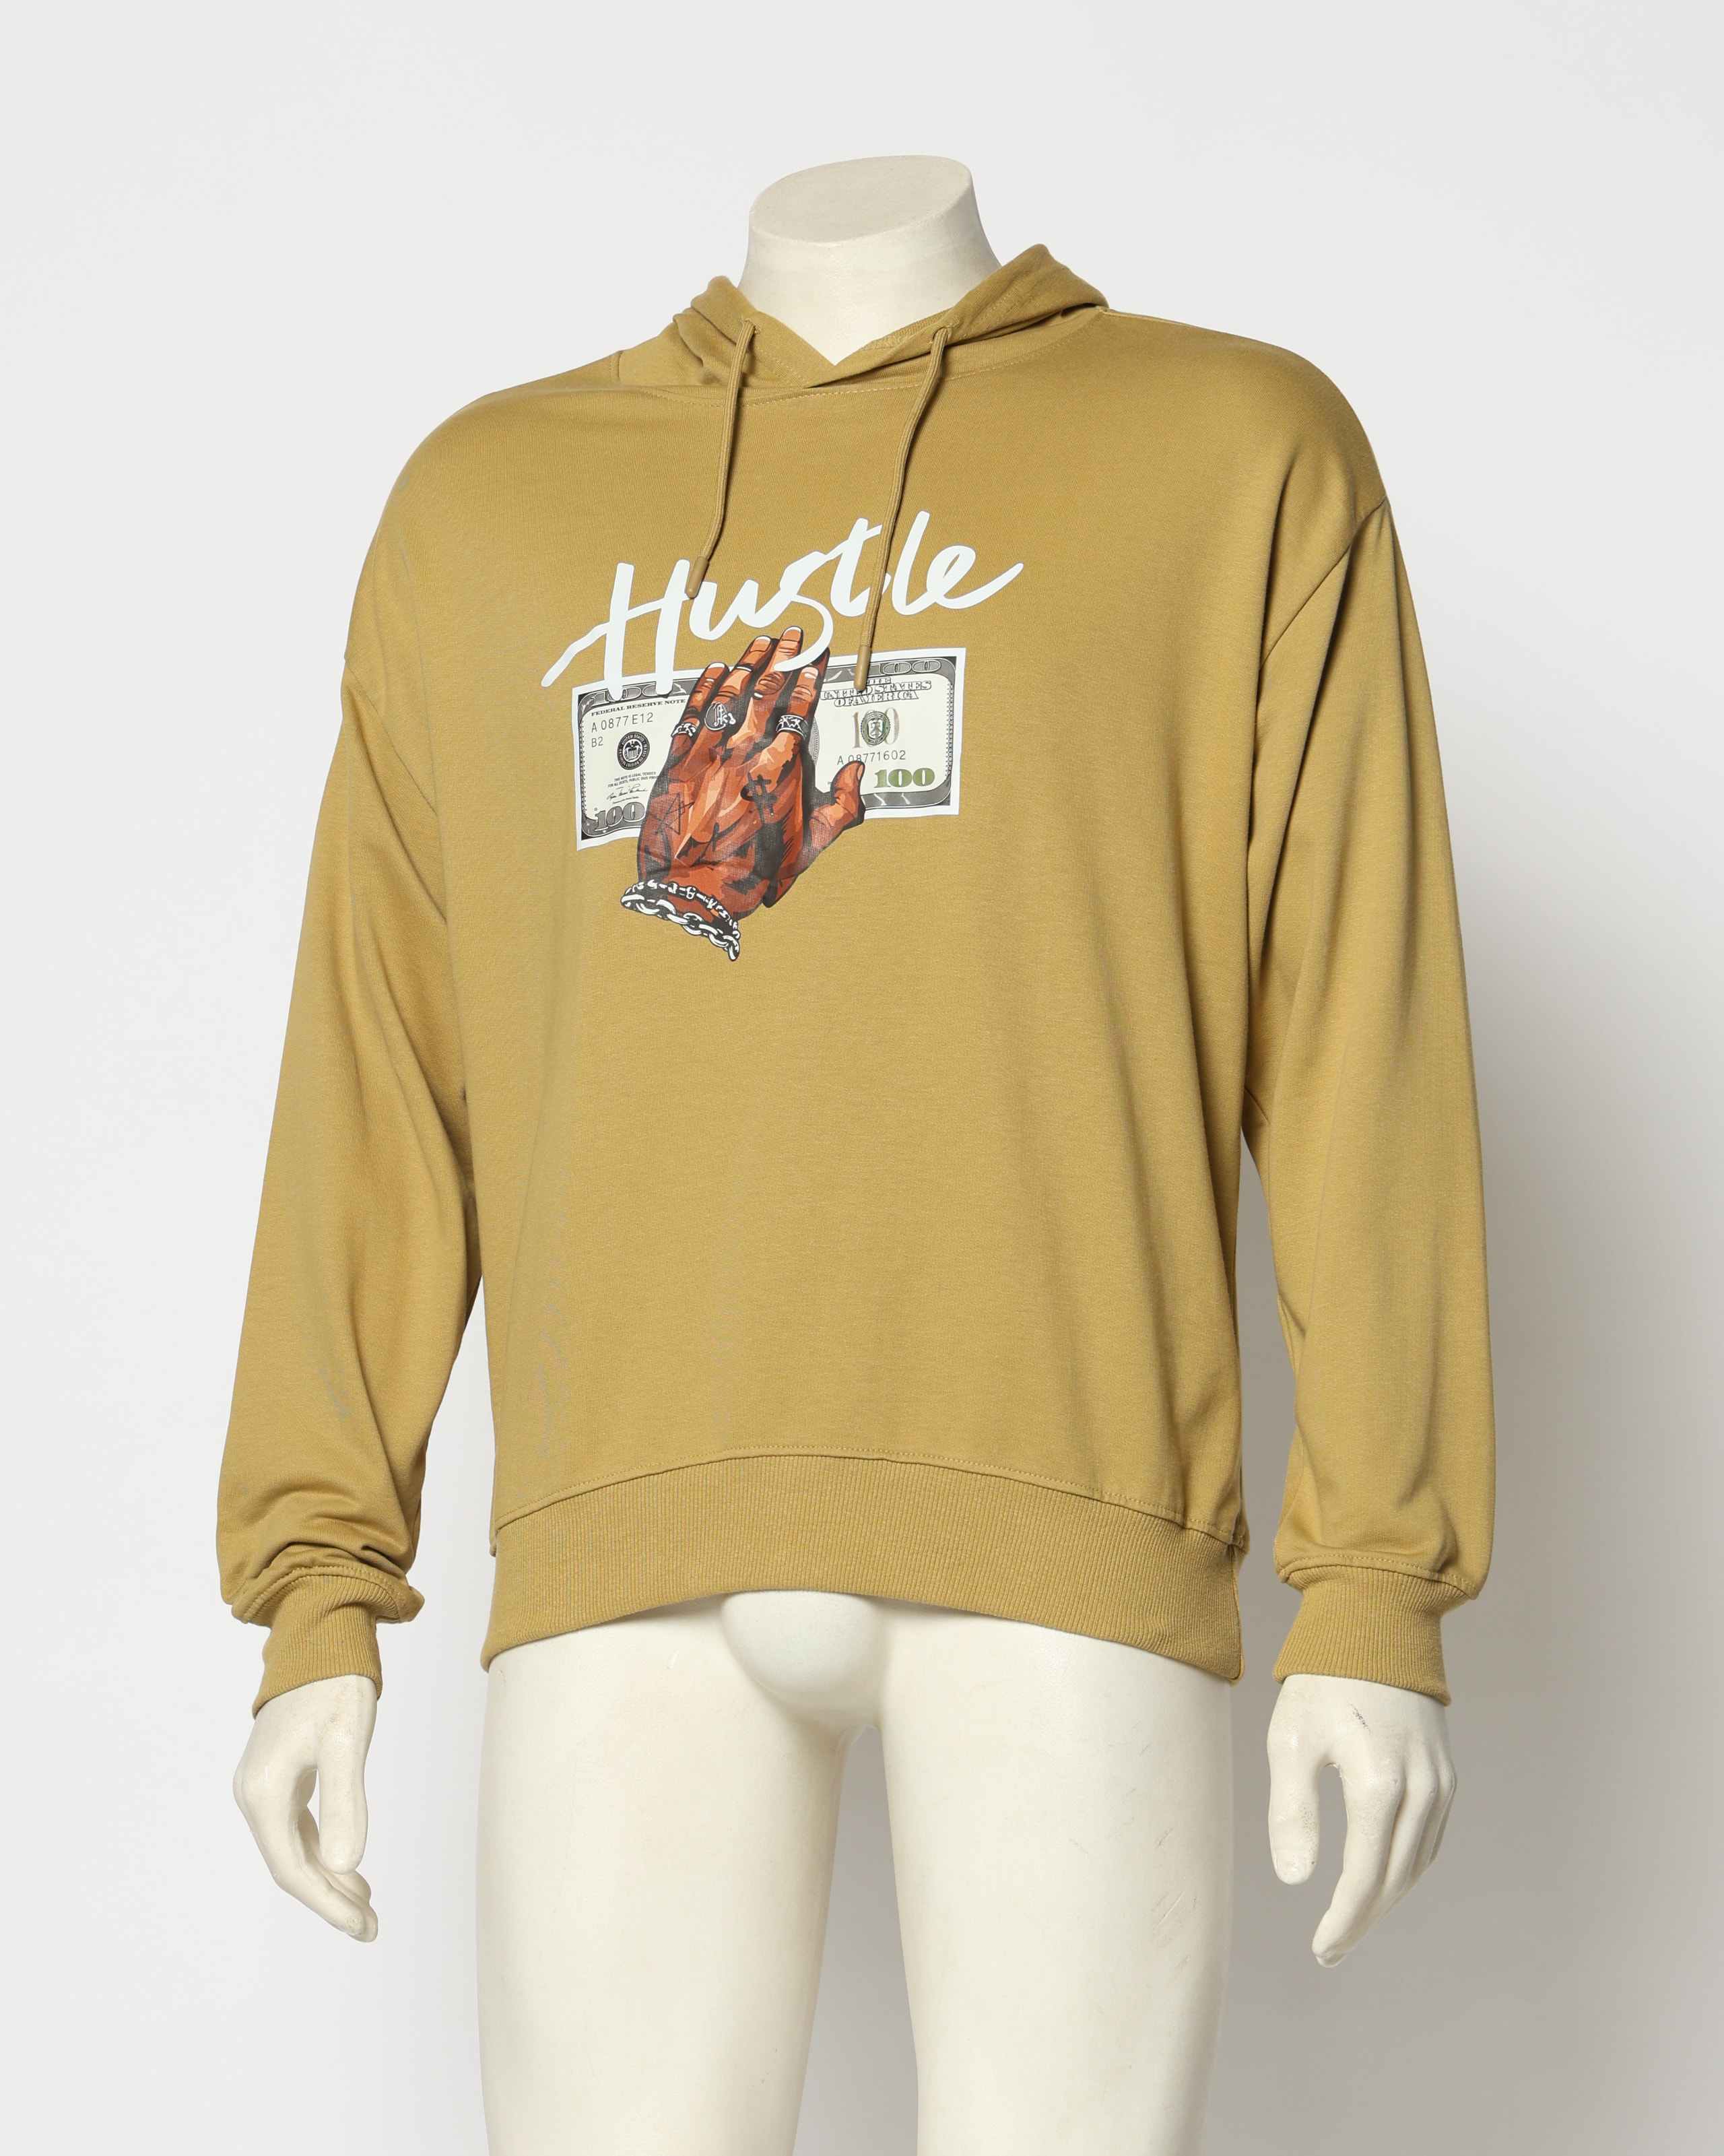
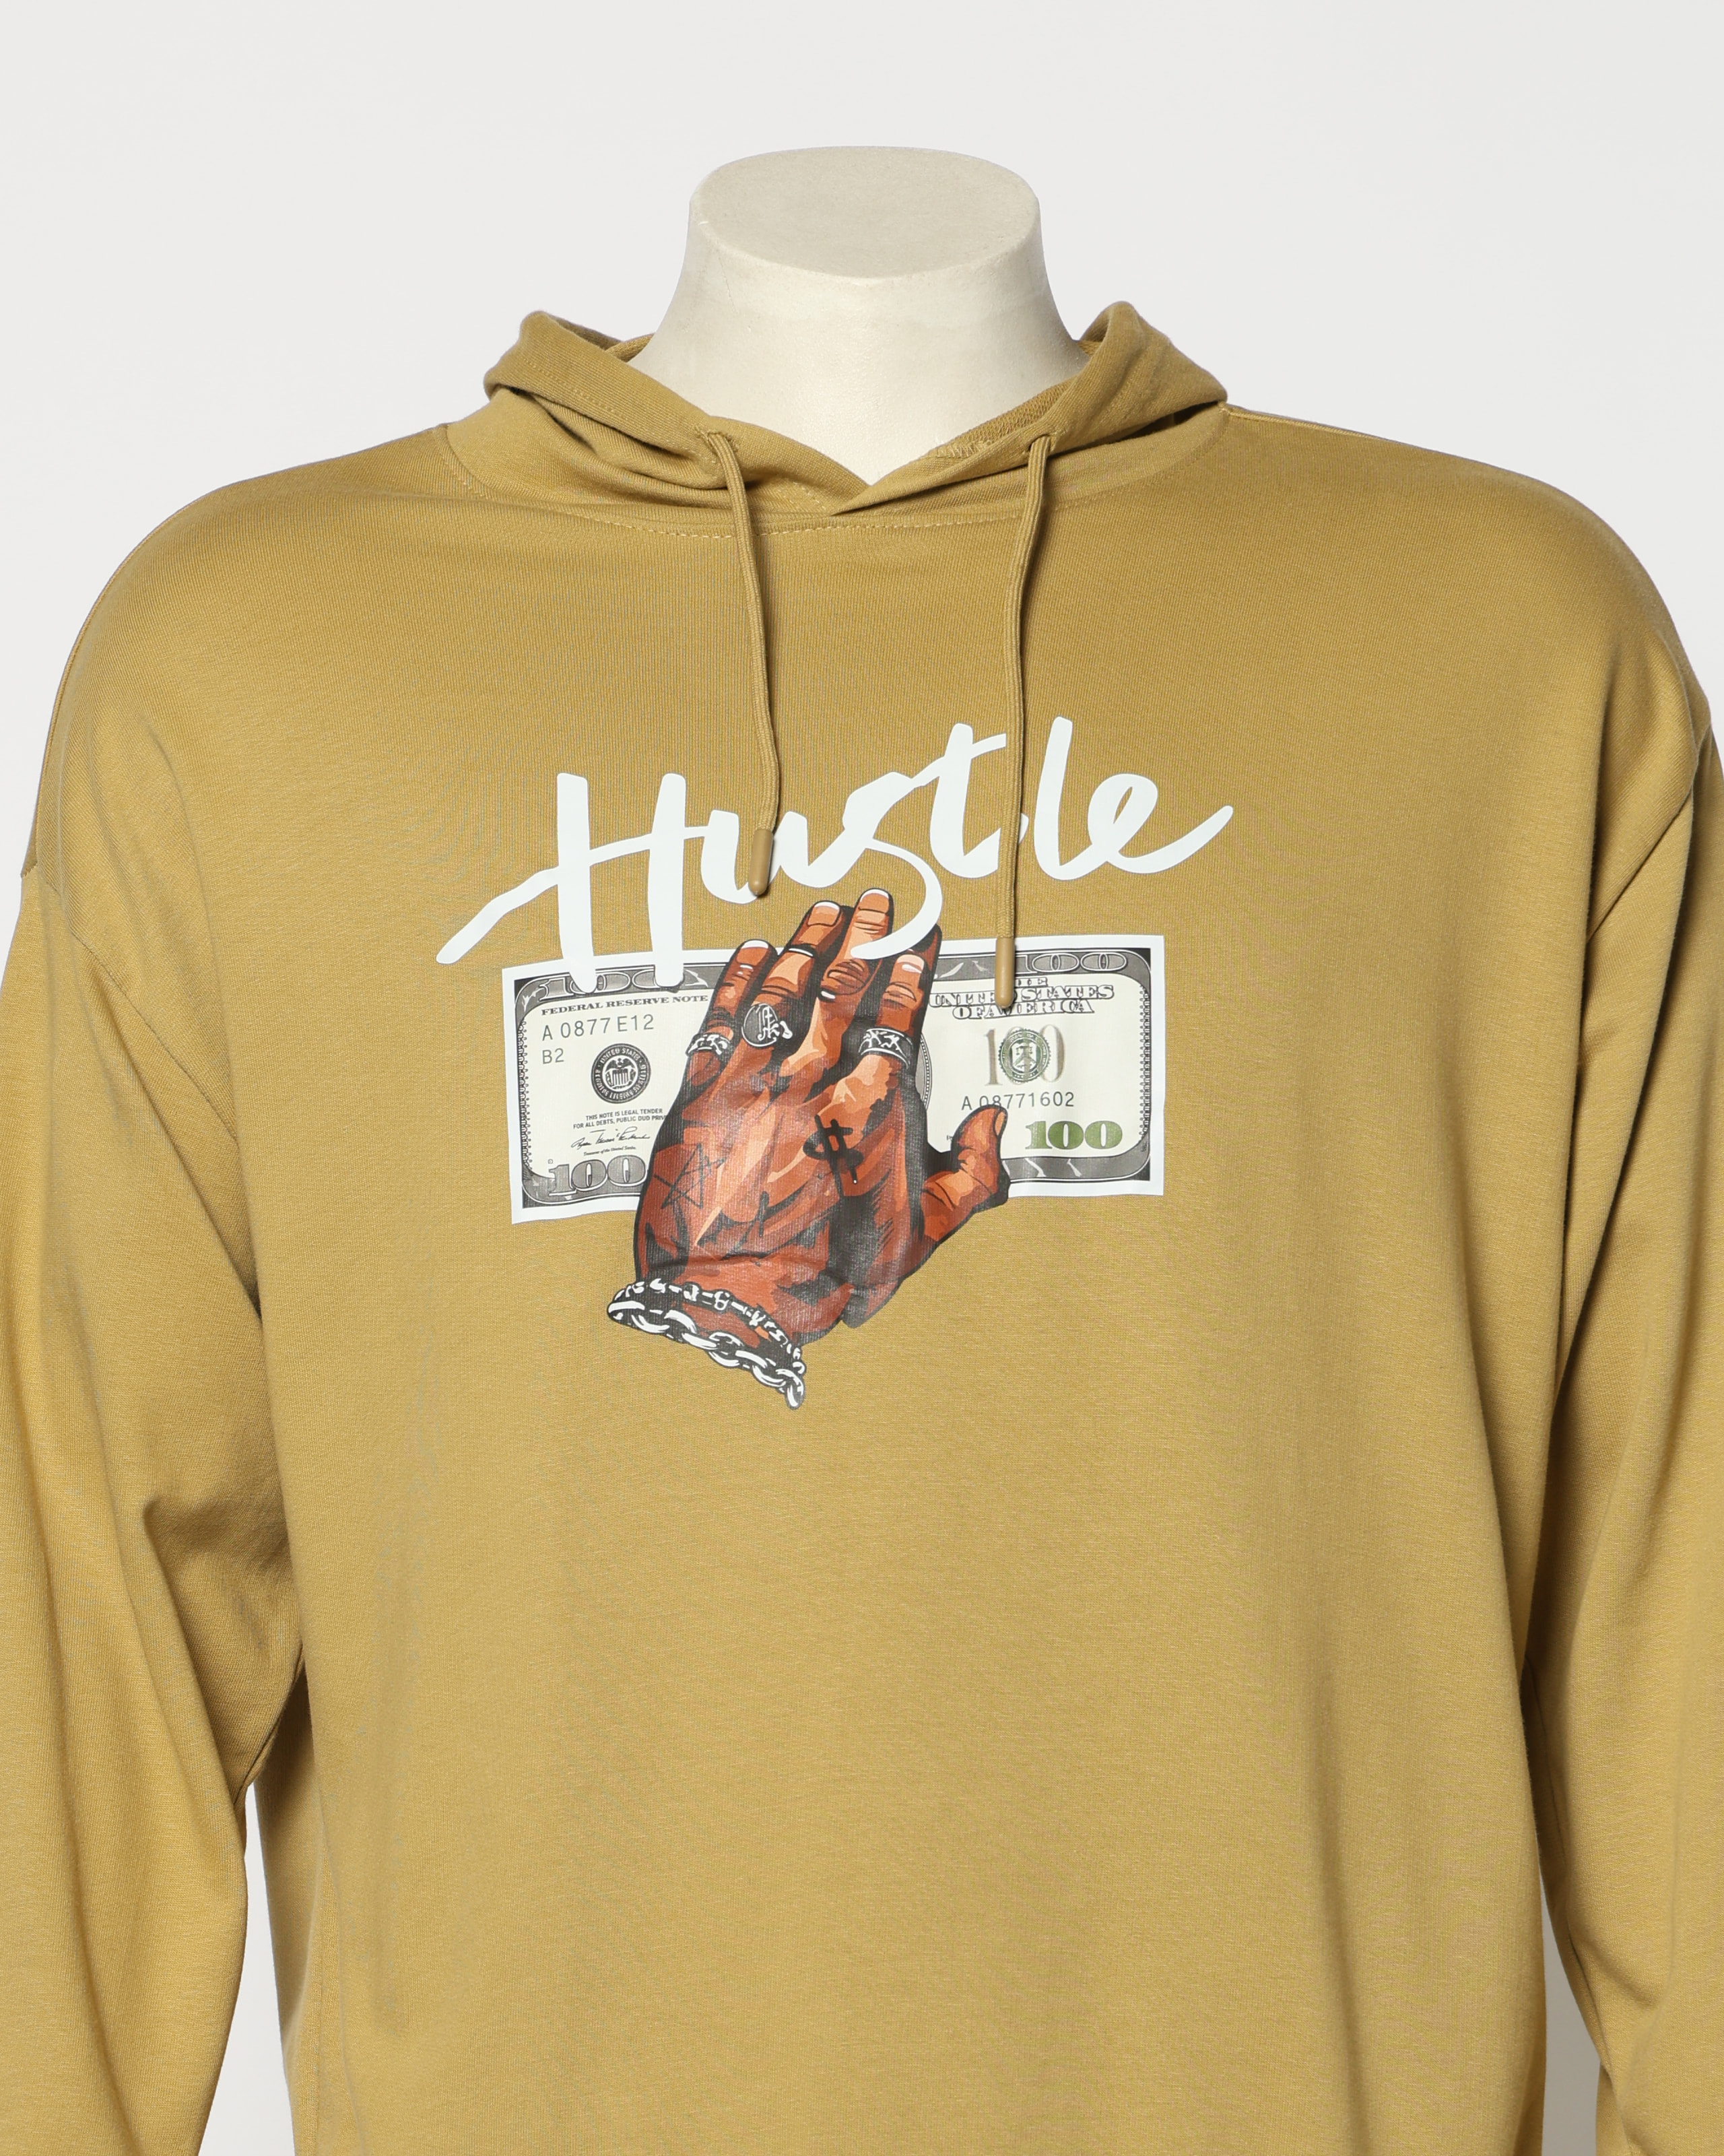
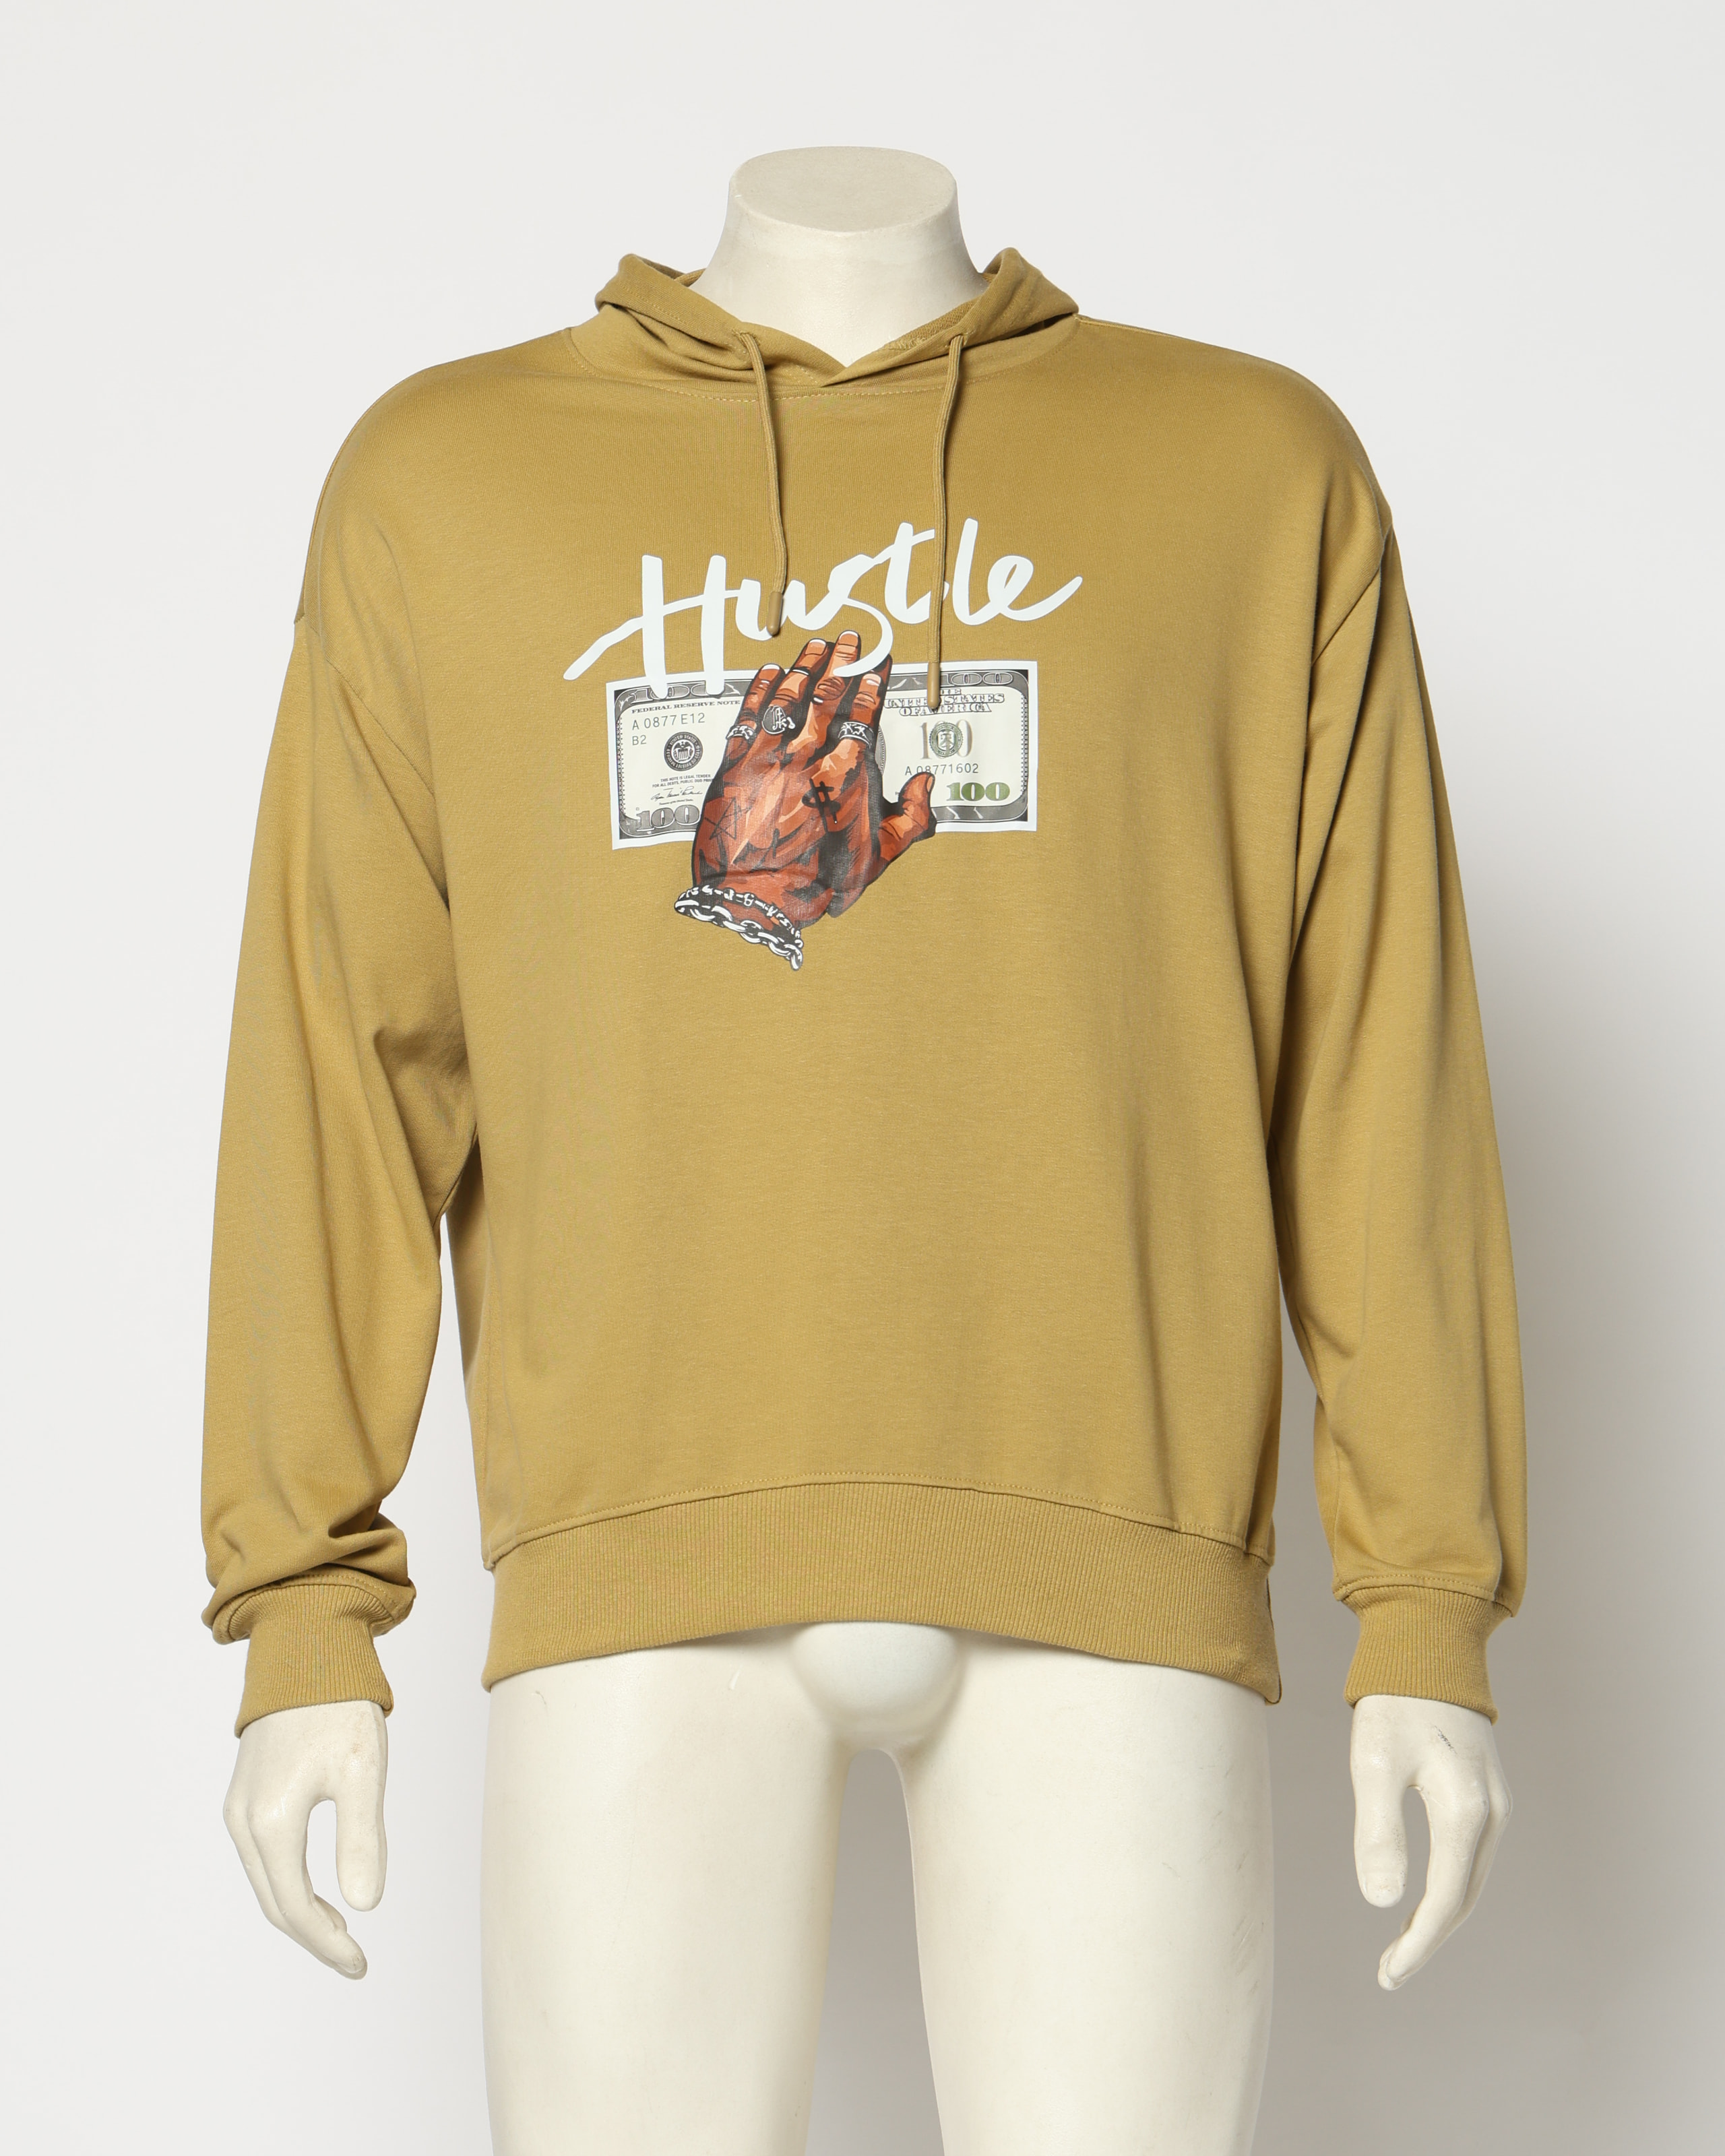
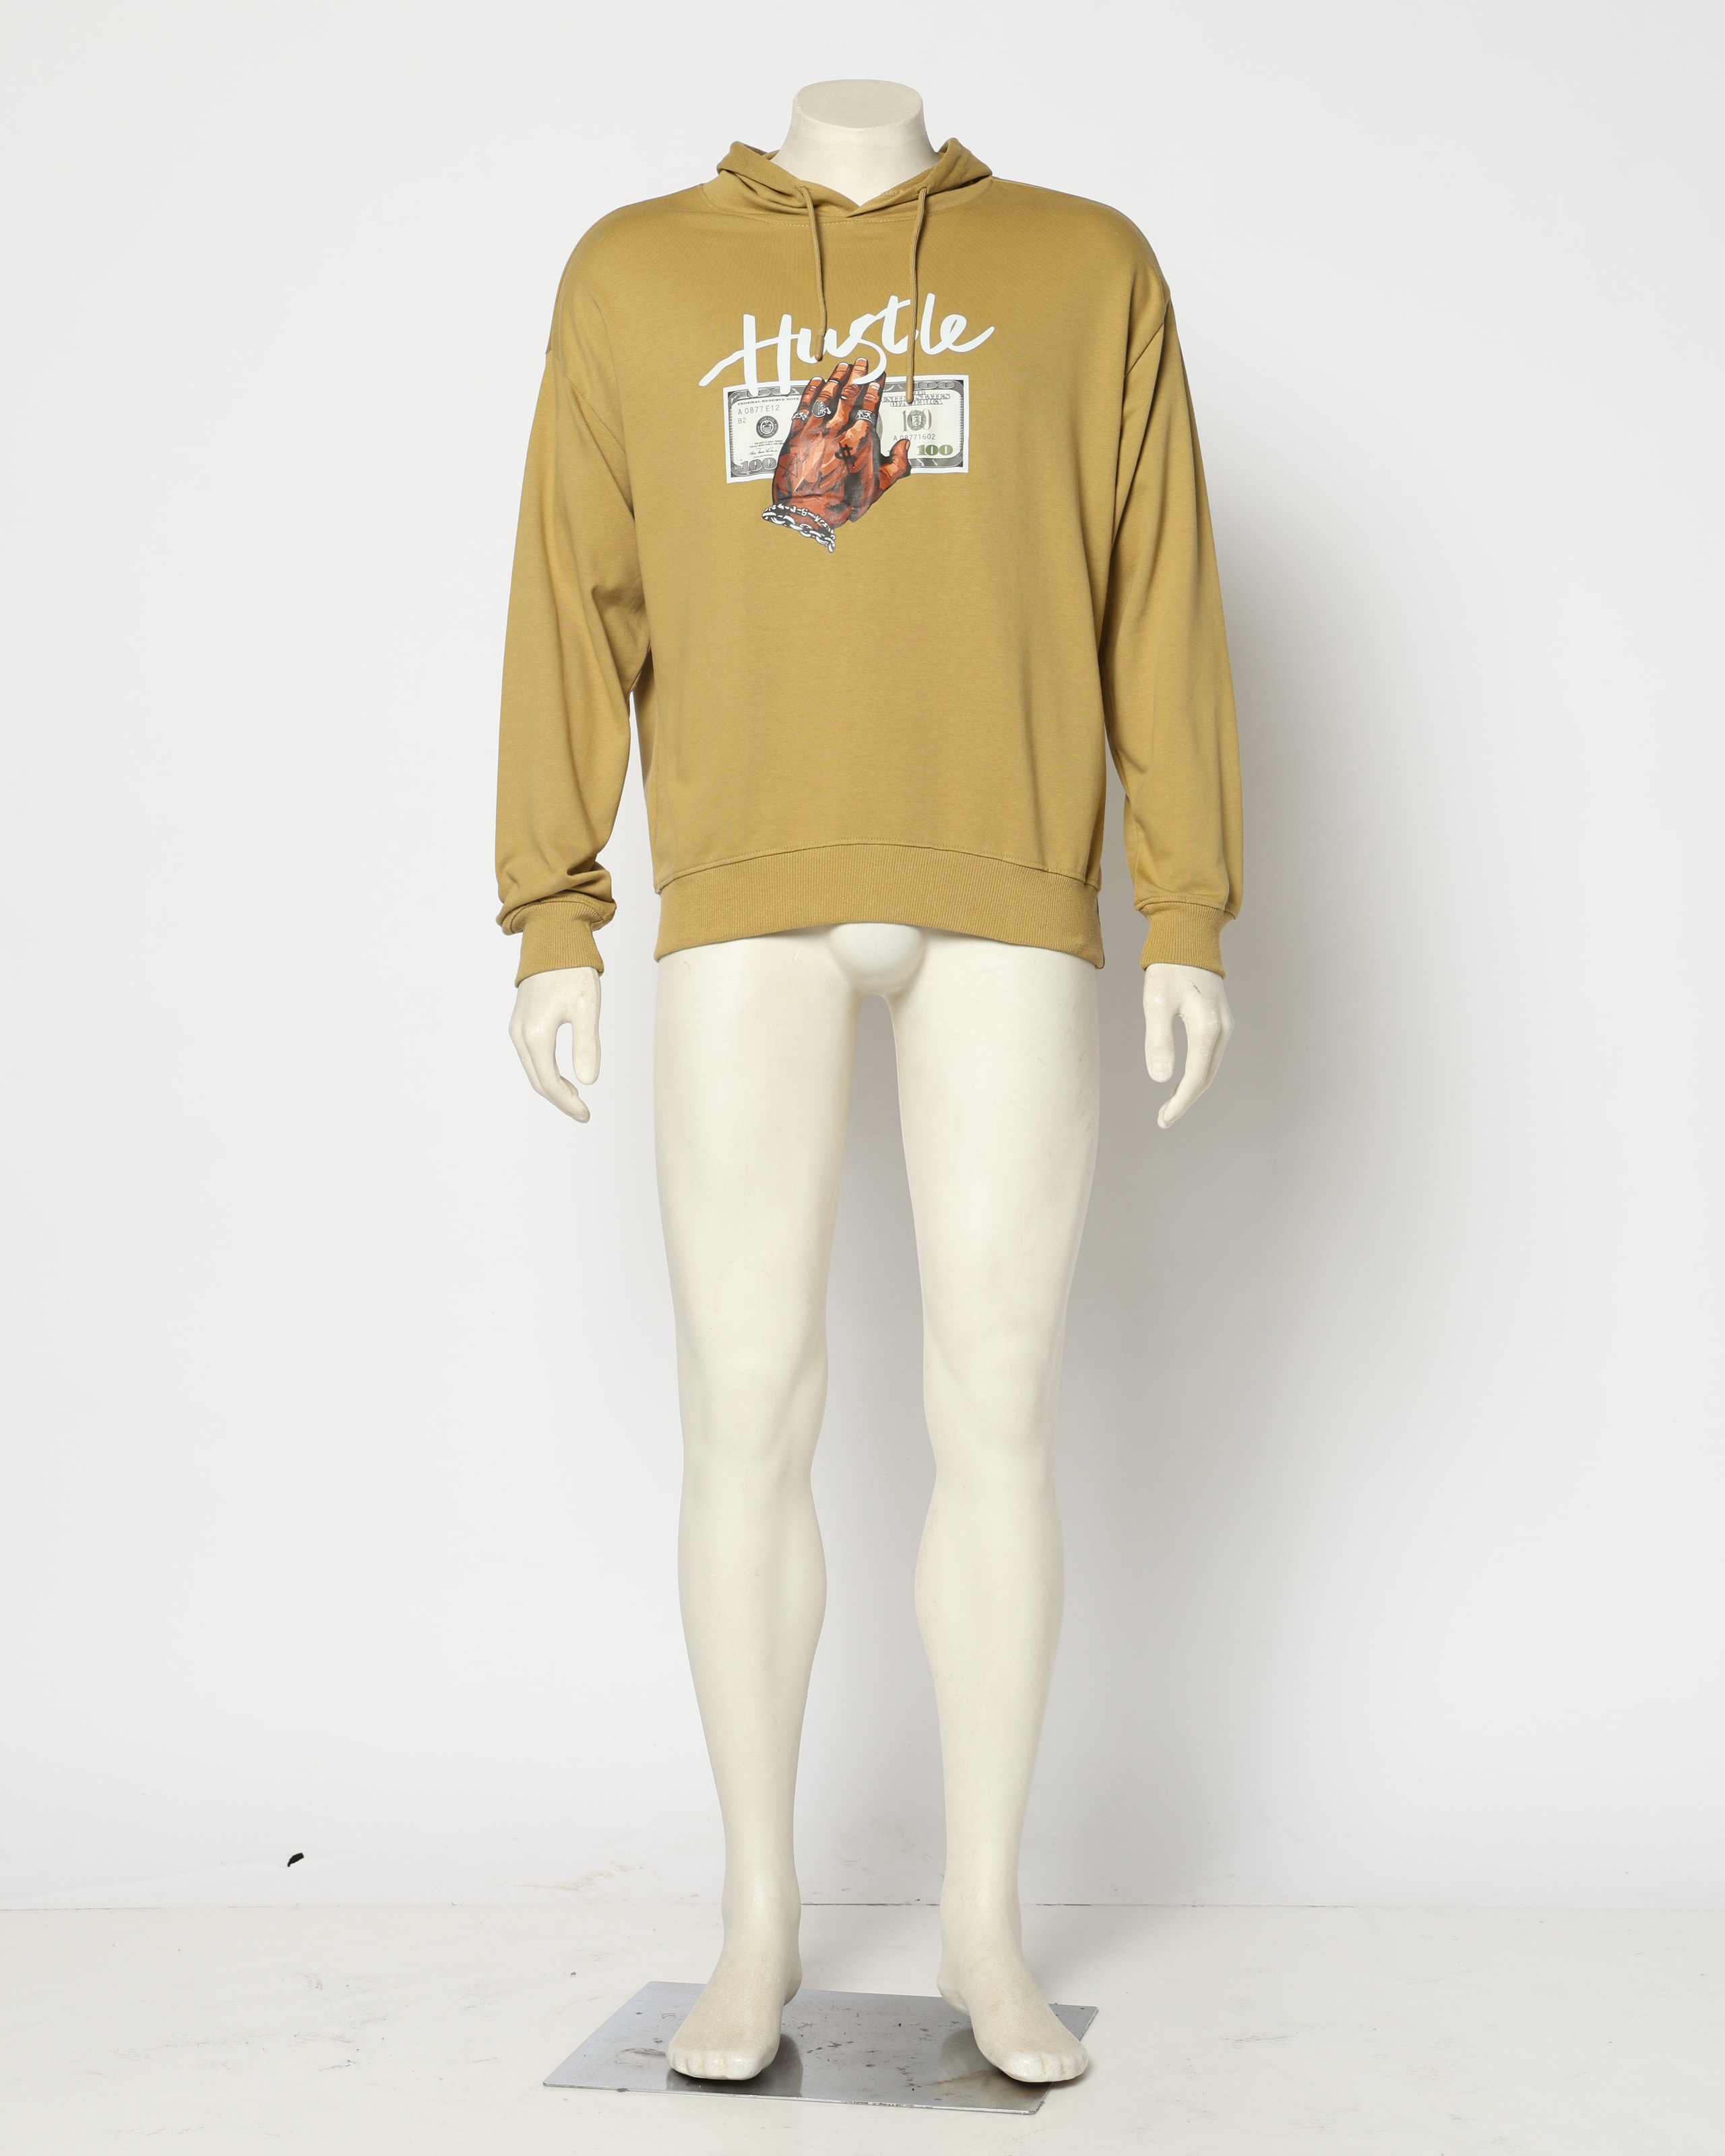
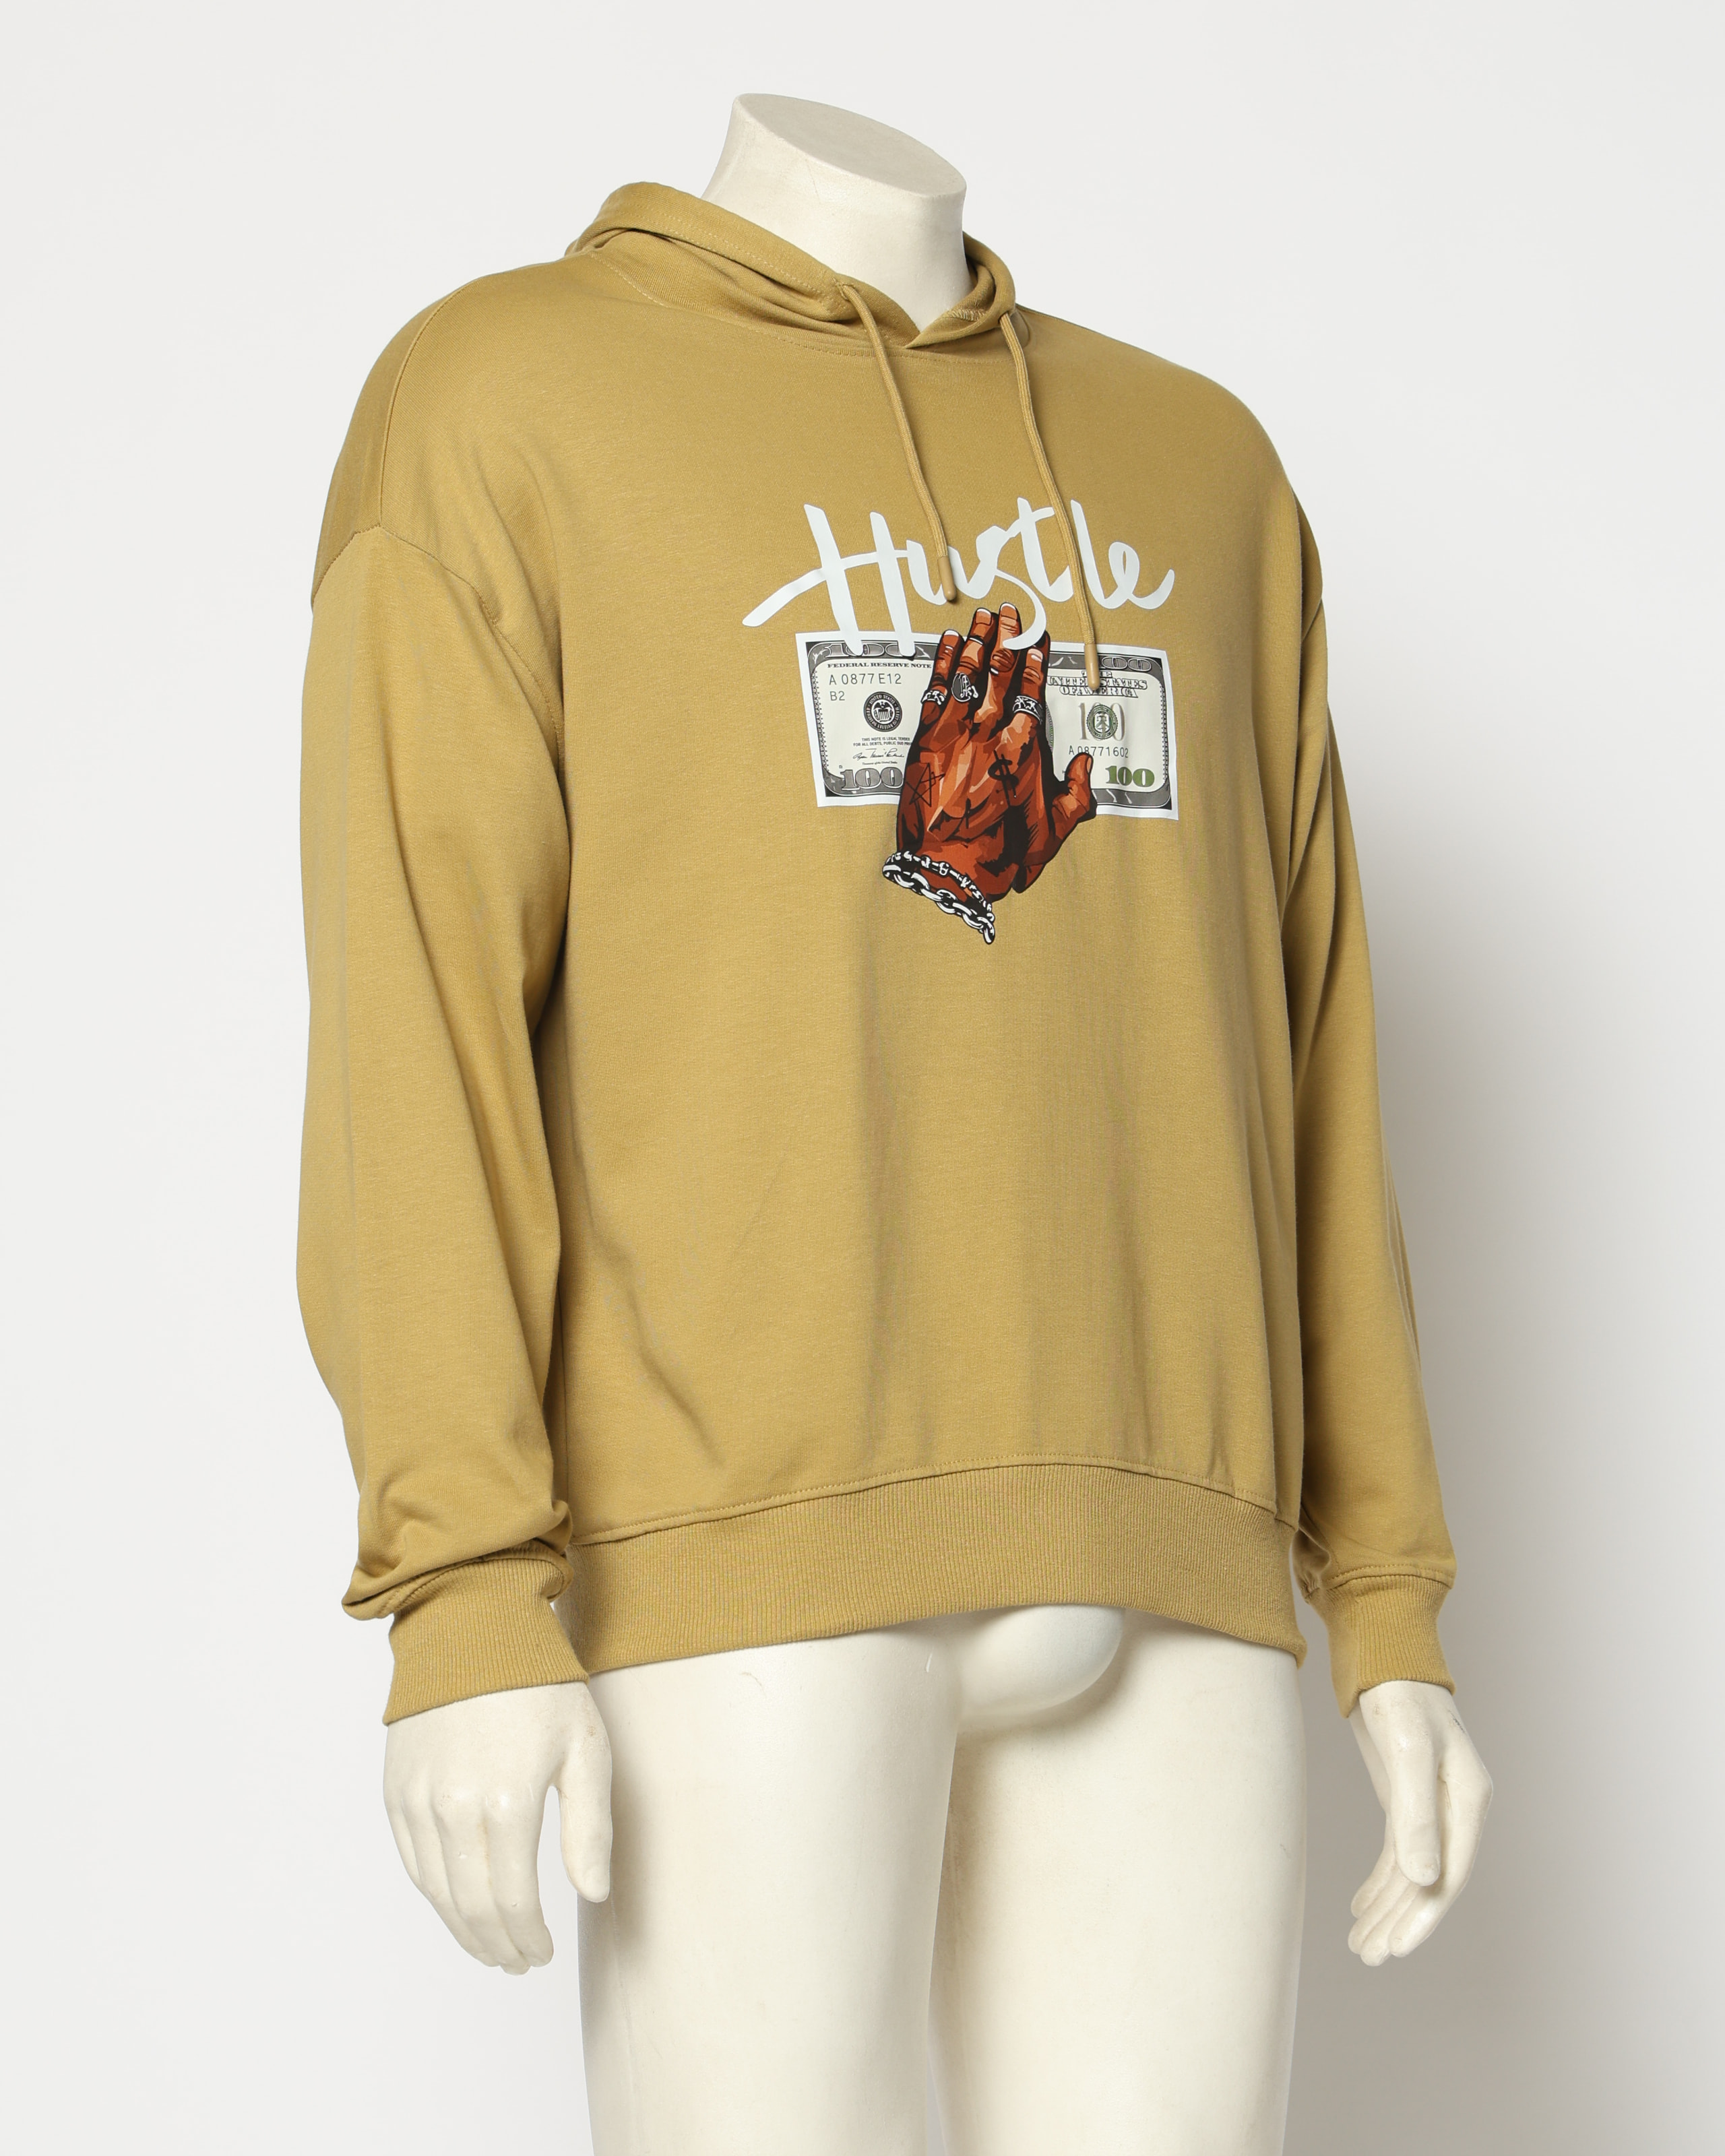
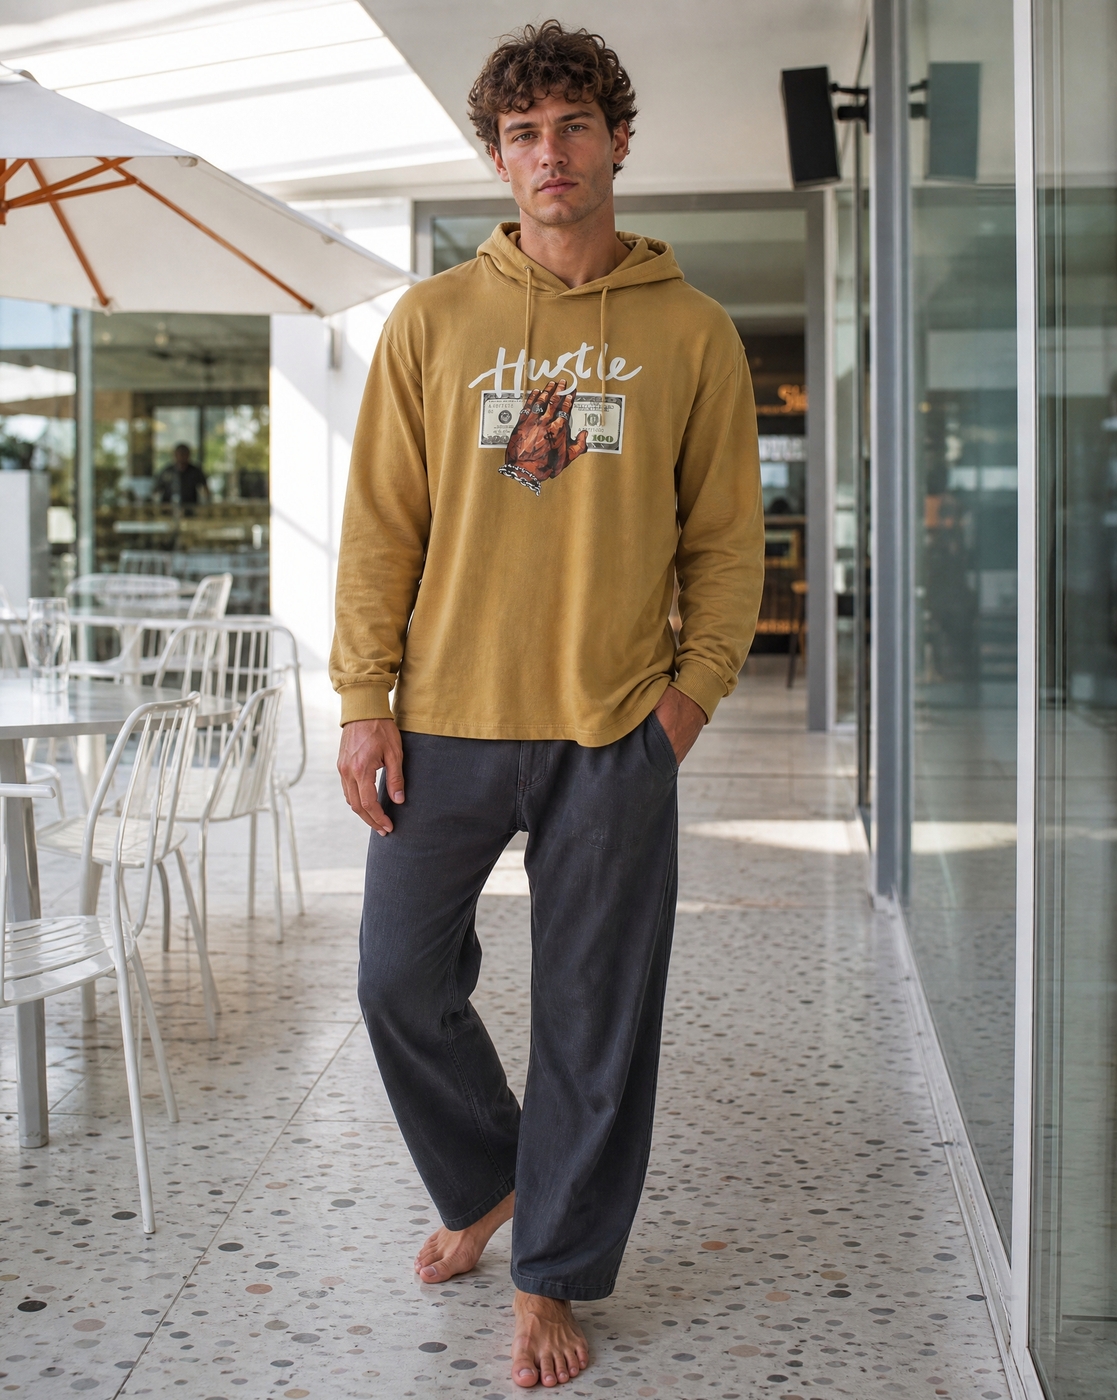
A khaki hoodie whose input photos show a wide ribbed knit waistband. Three of five outputs rendered a flat, folded t-shirt style hem instead. The agent flagged all three on garment consistency and construction details, and regenerated each one.
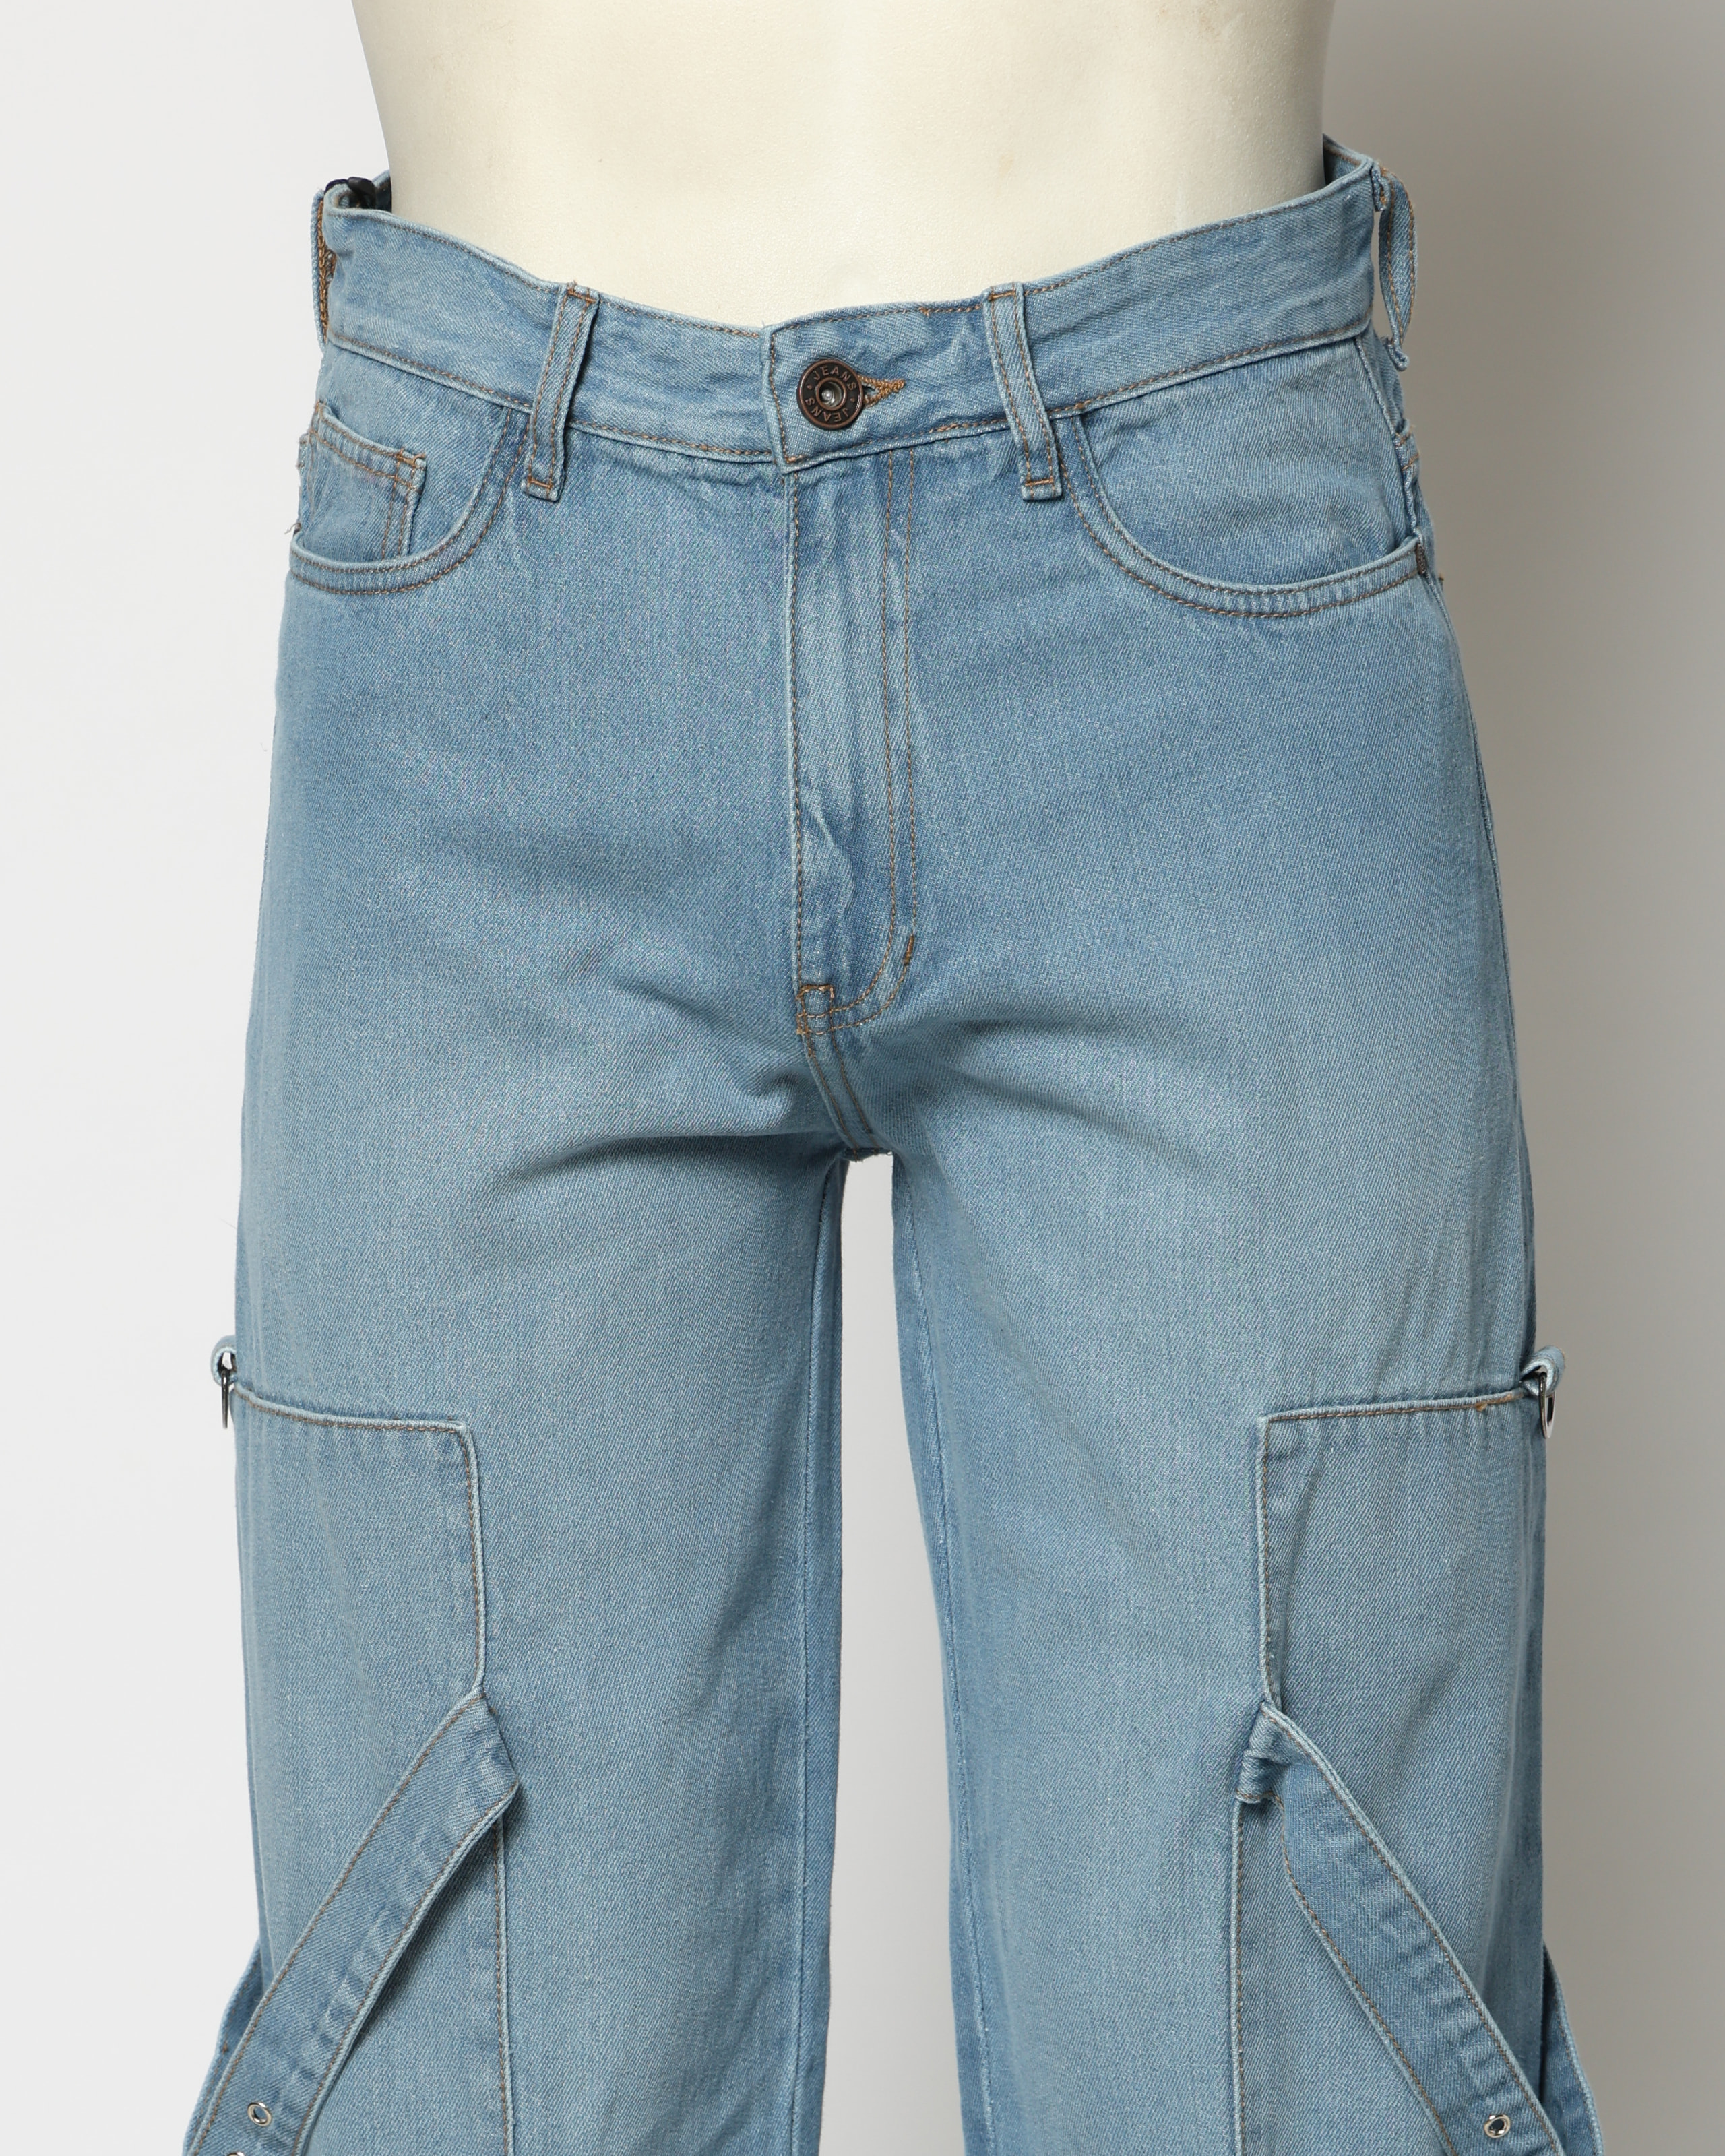
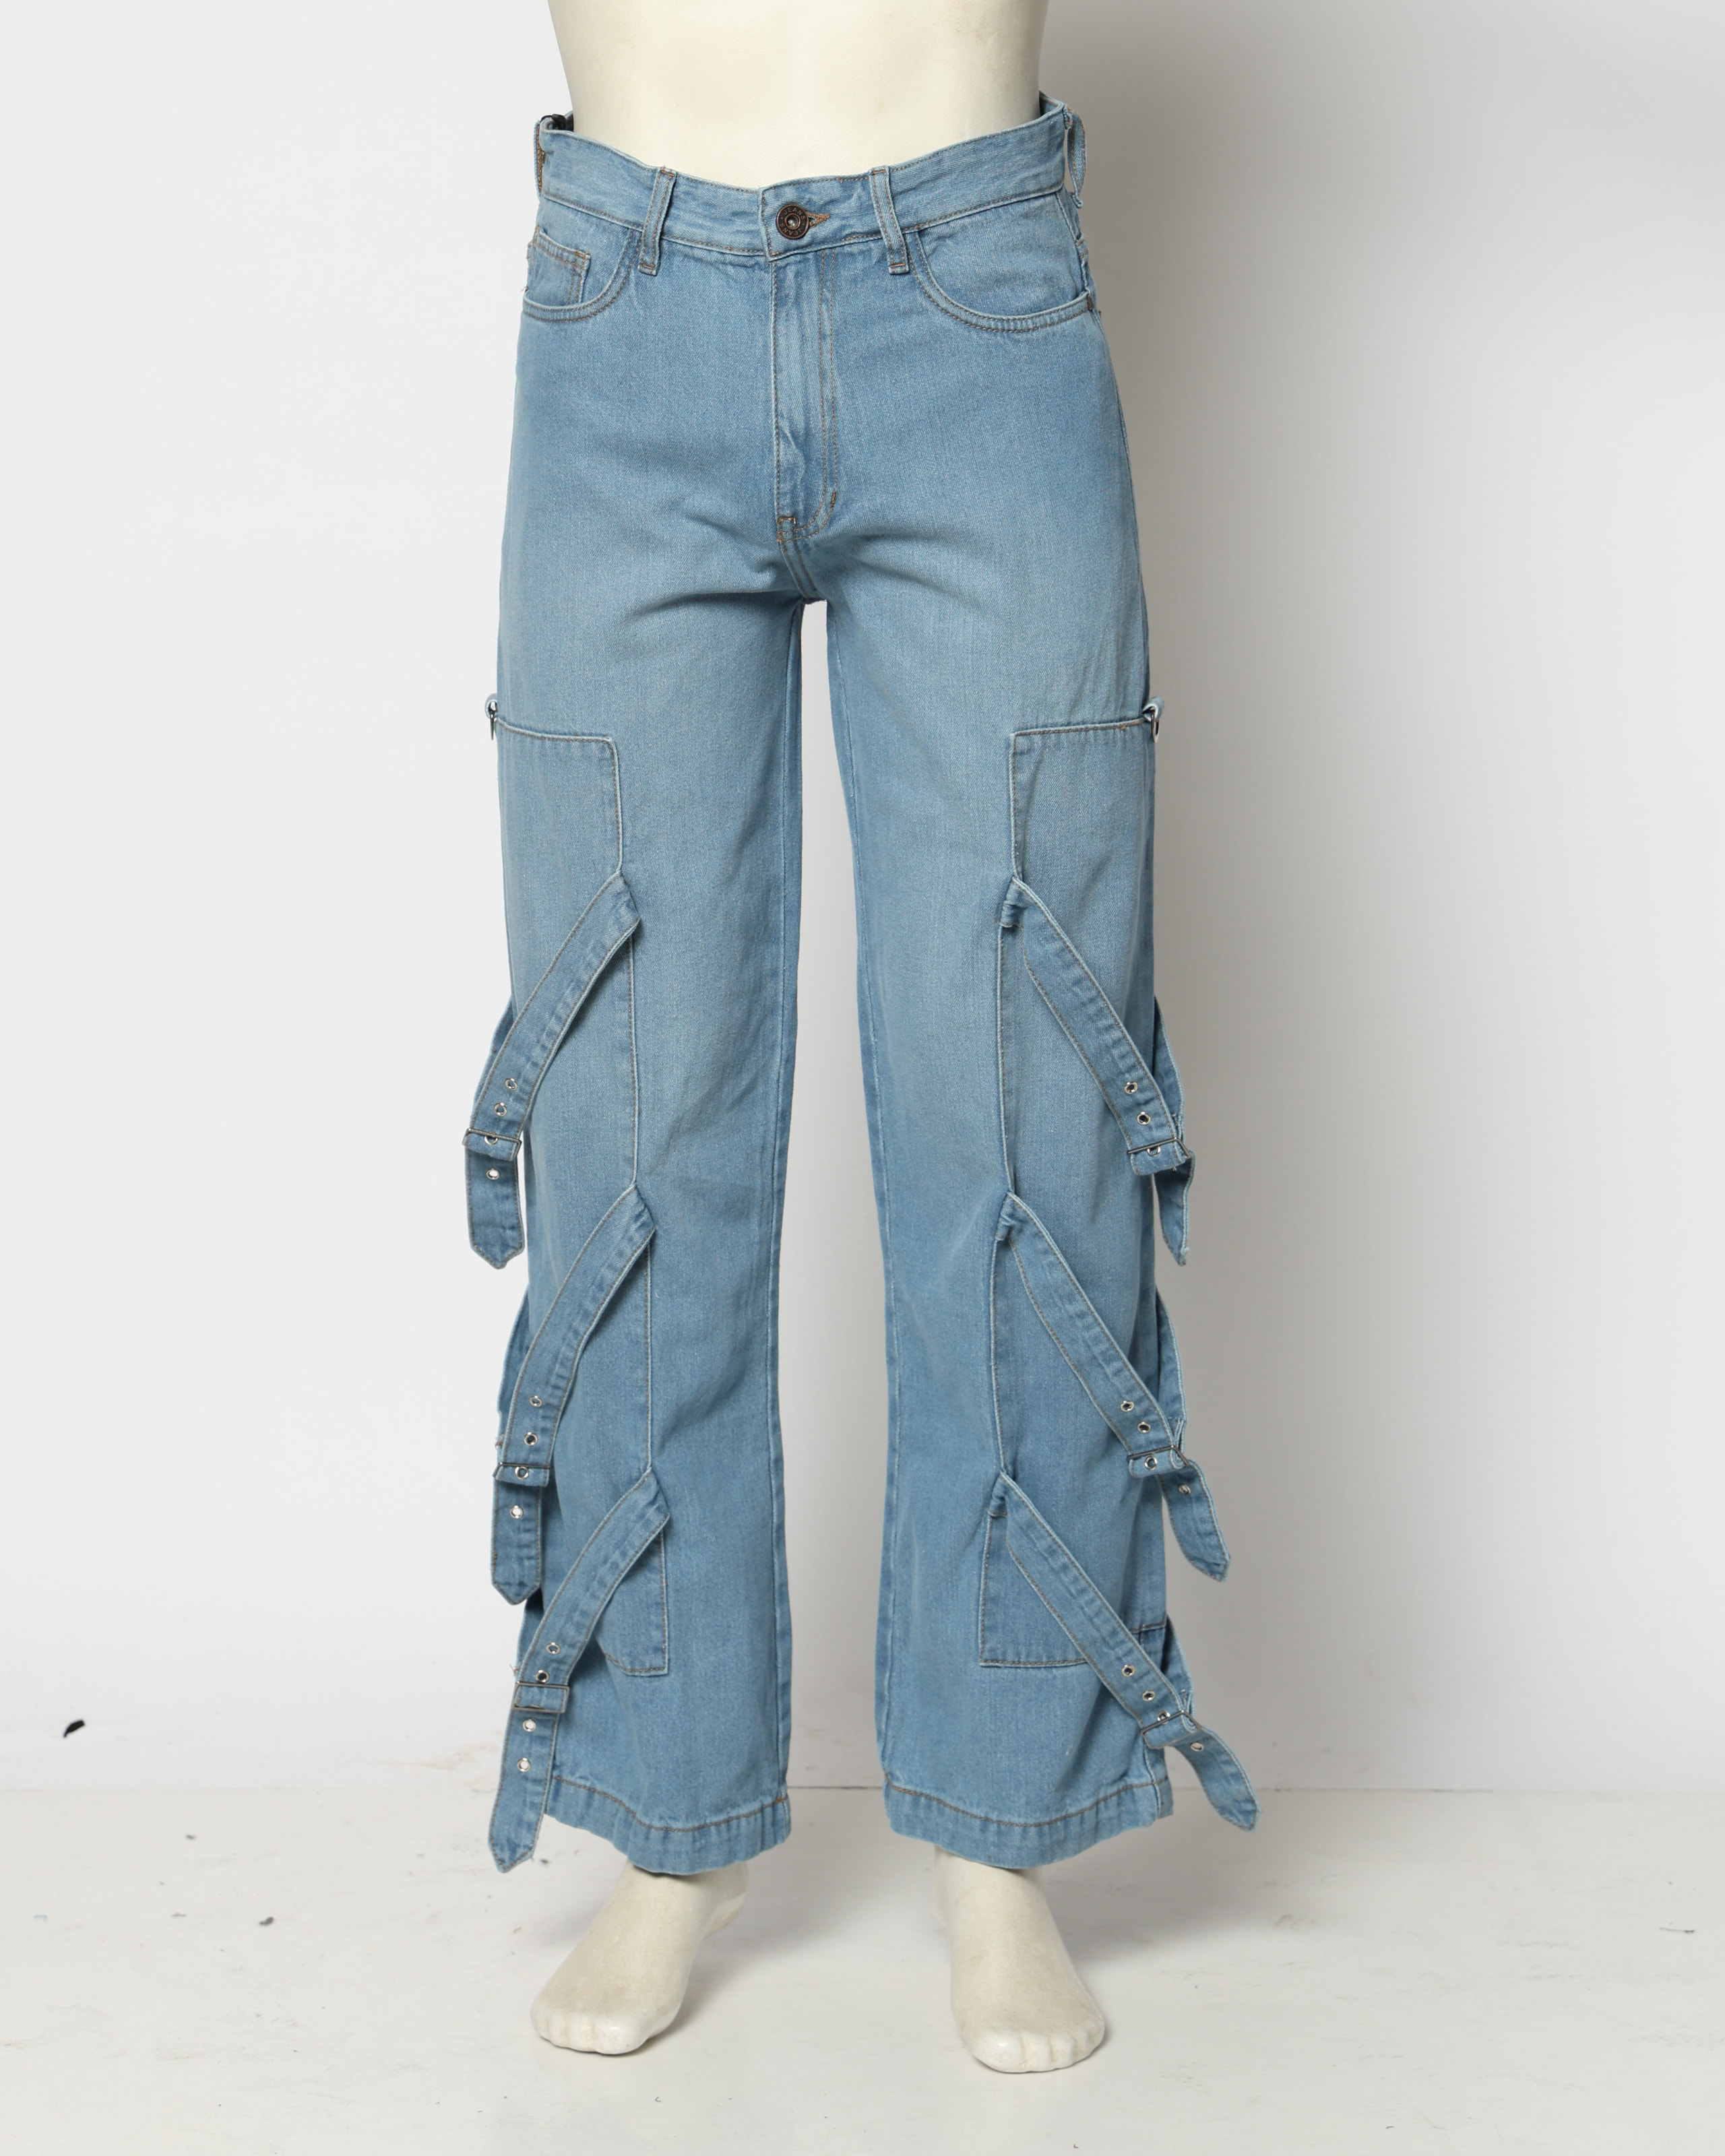
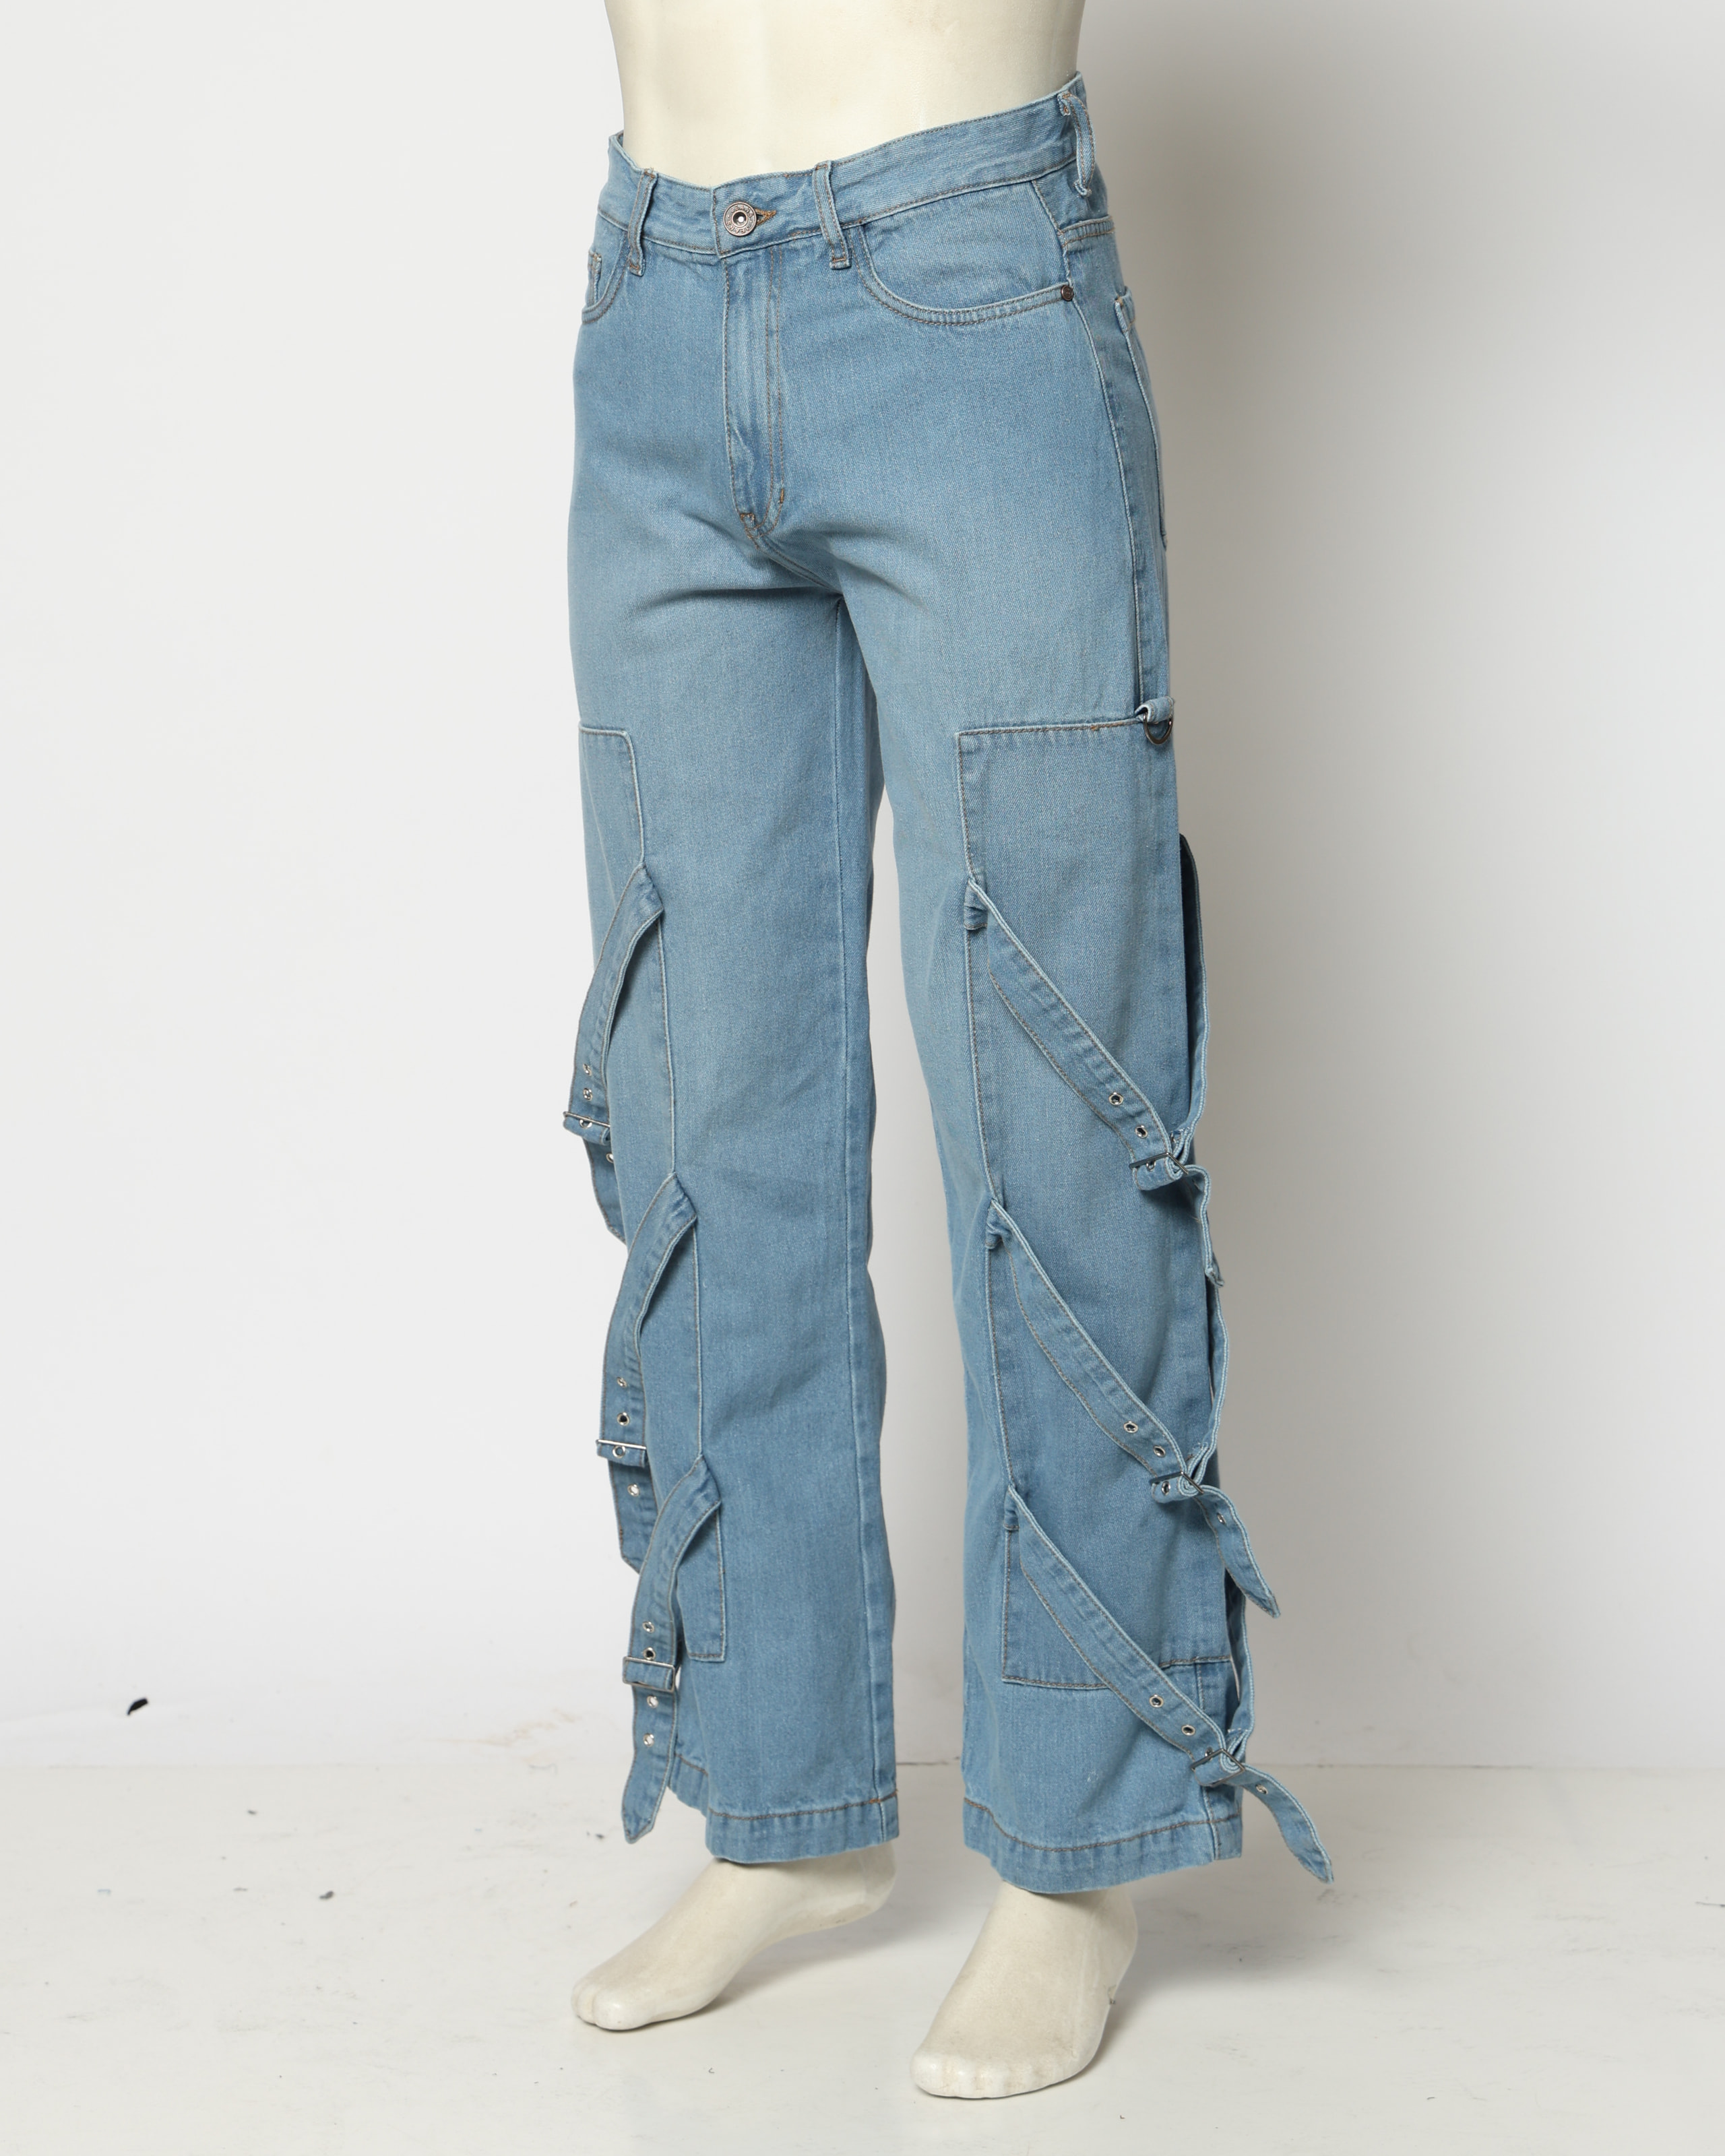
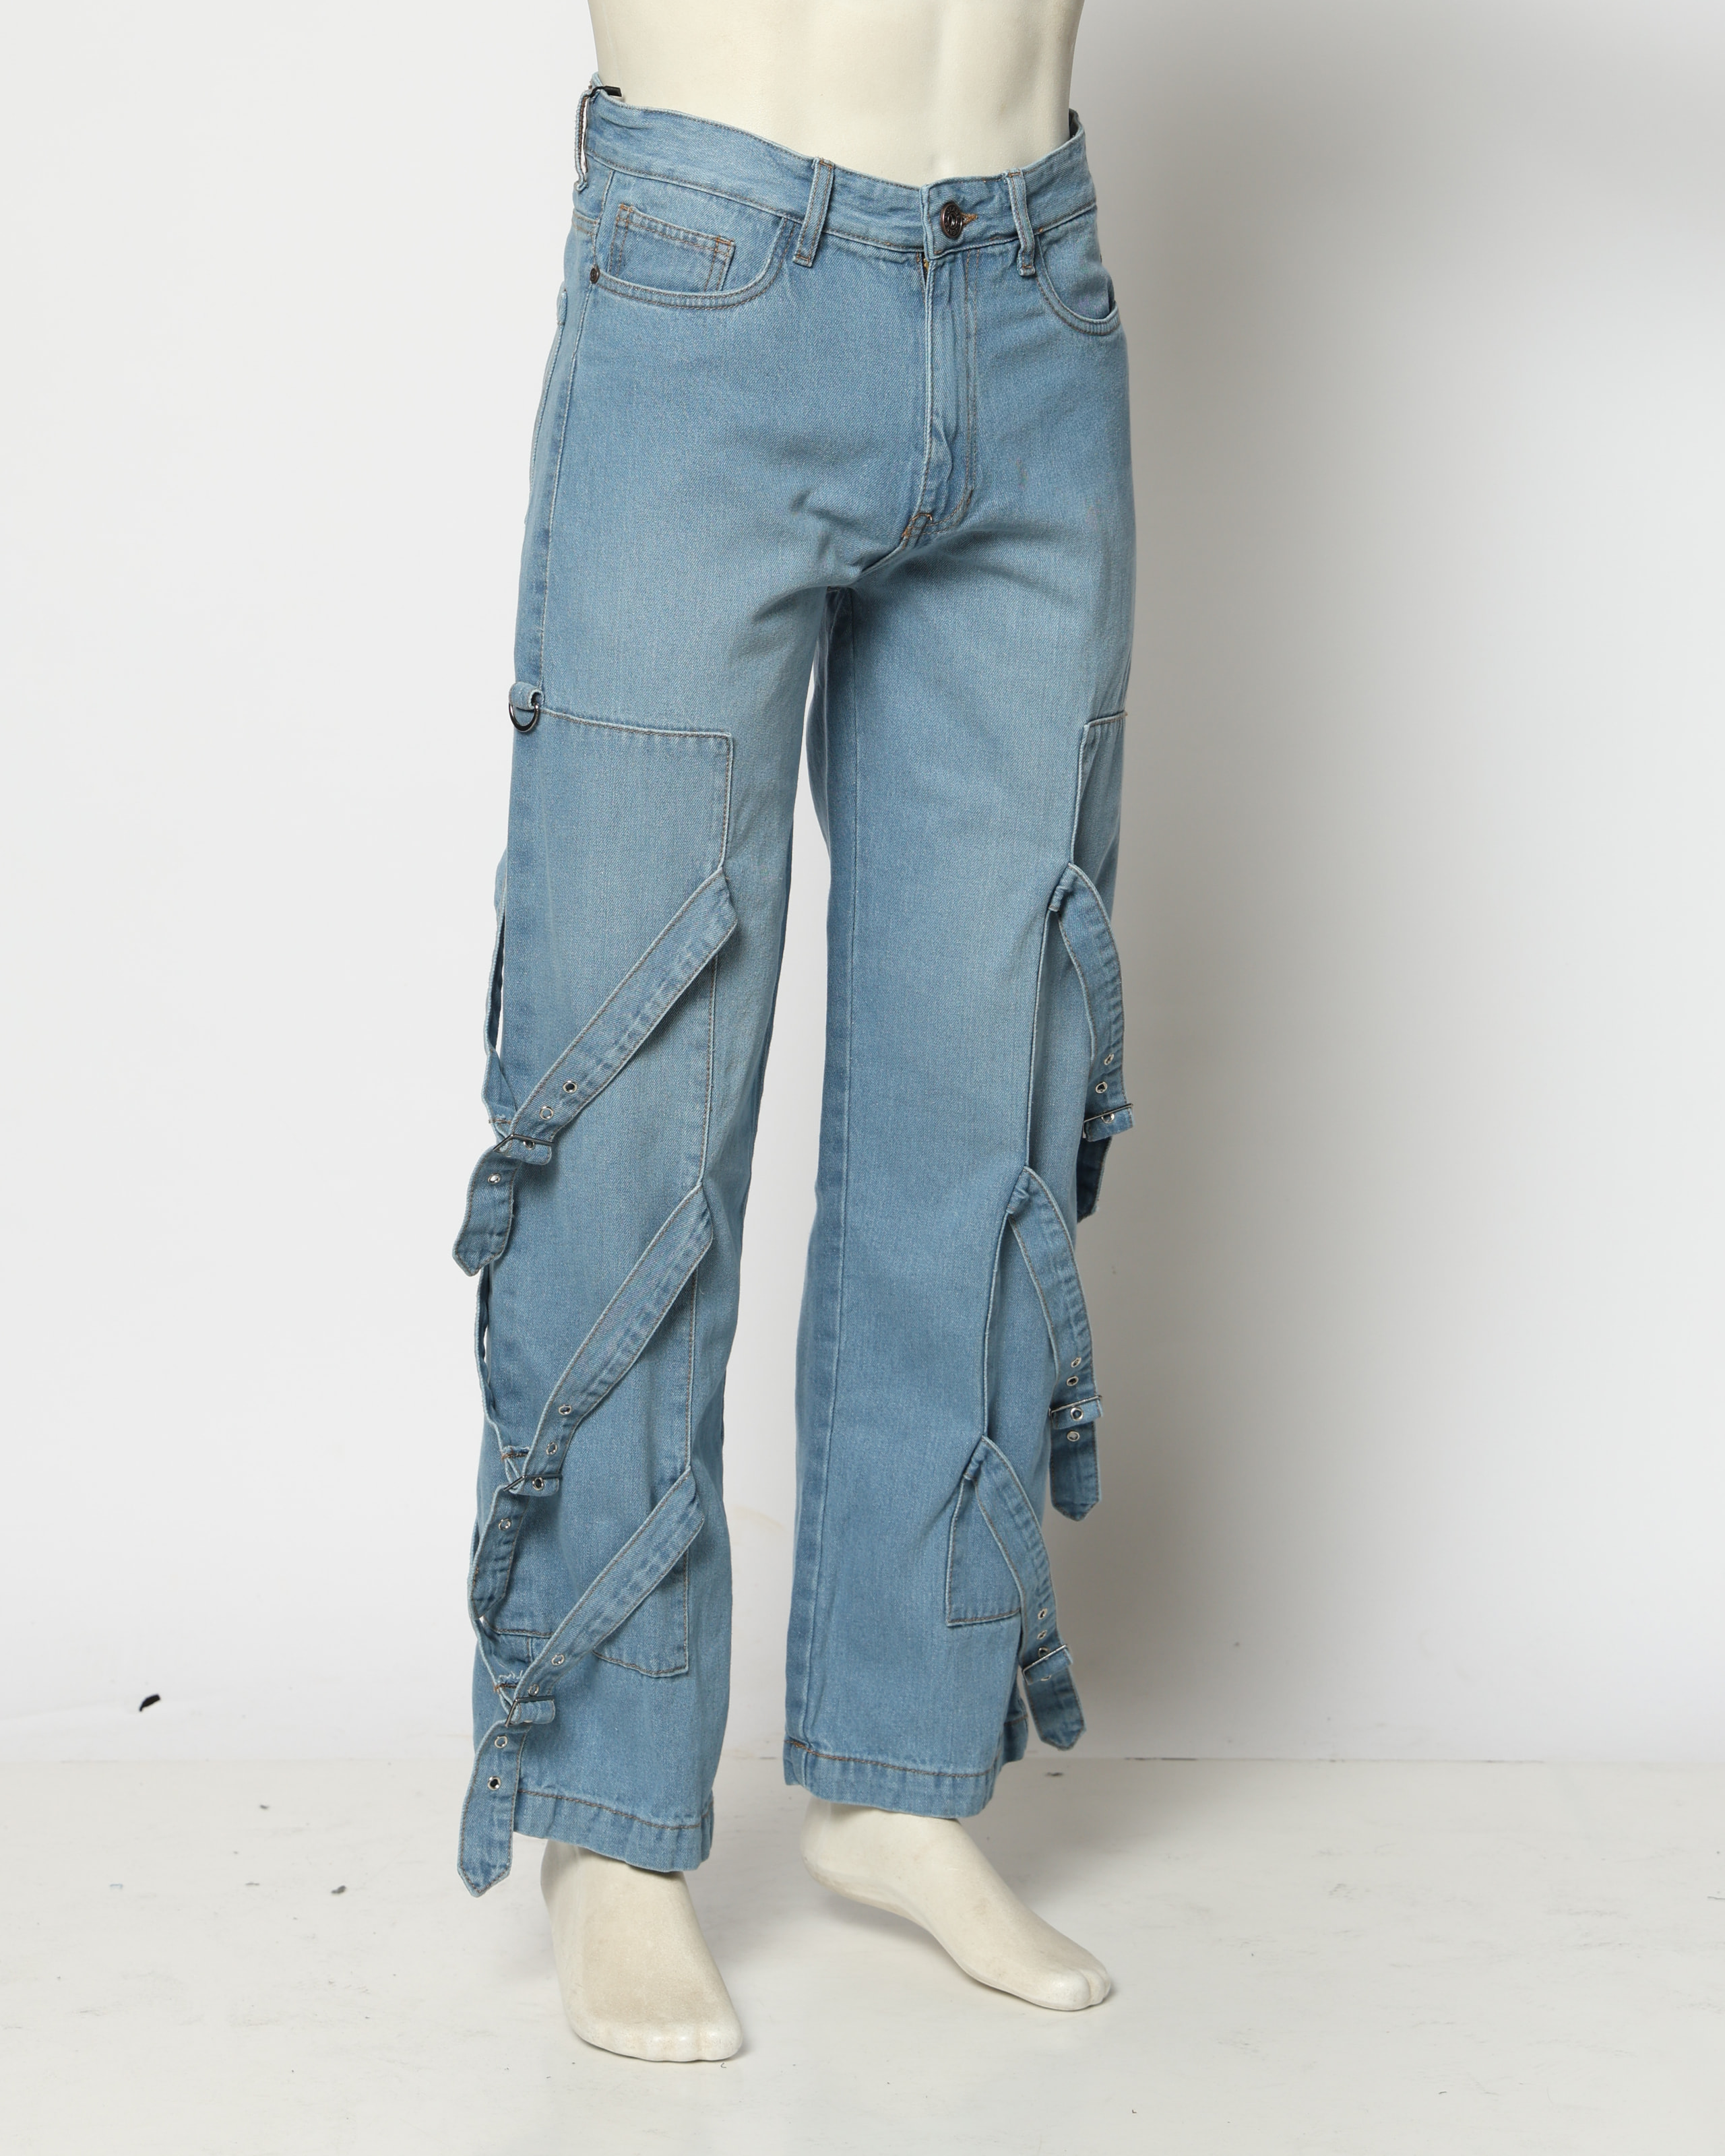
Cargo pockets lost two of three tiers 2 of 5 outputs replaced
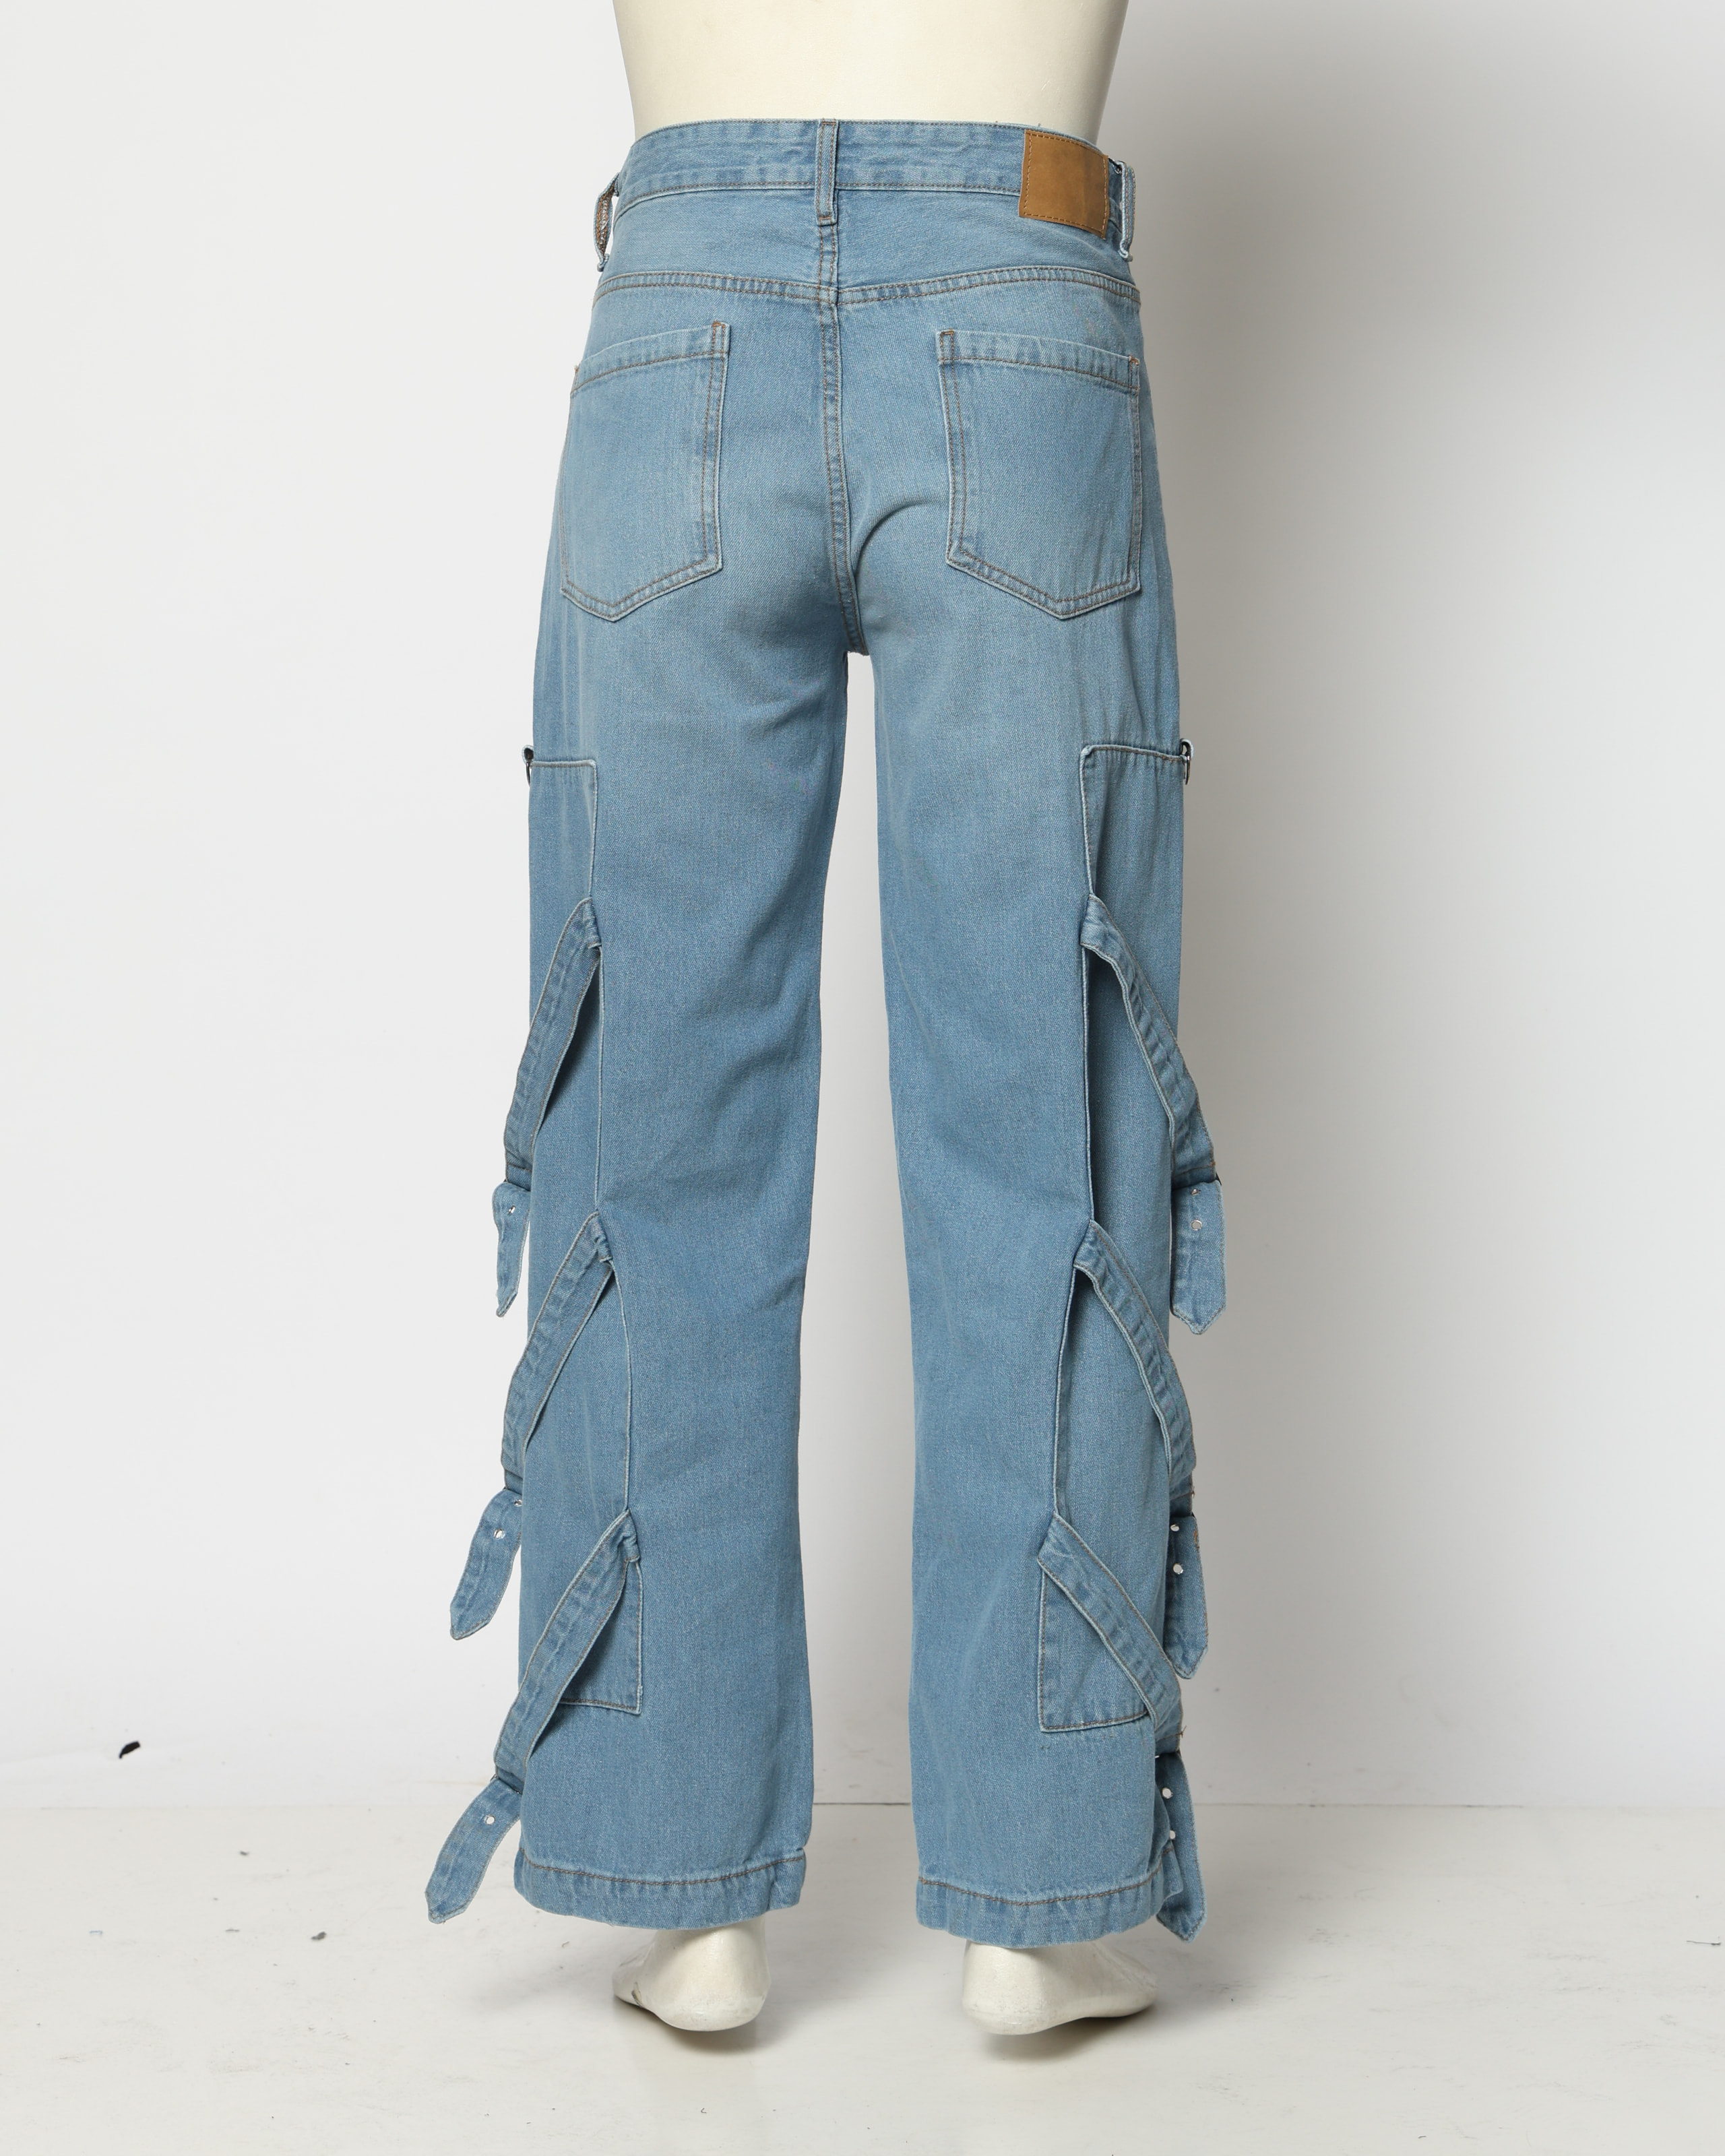
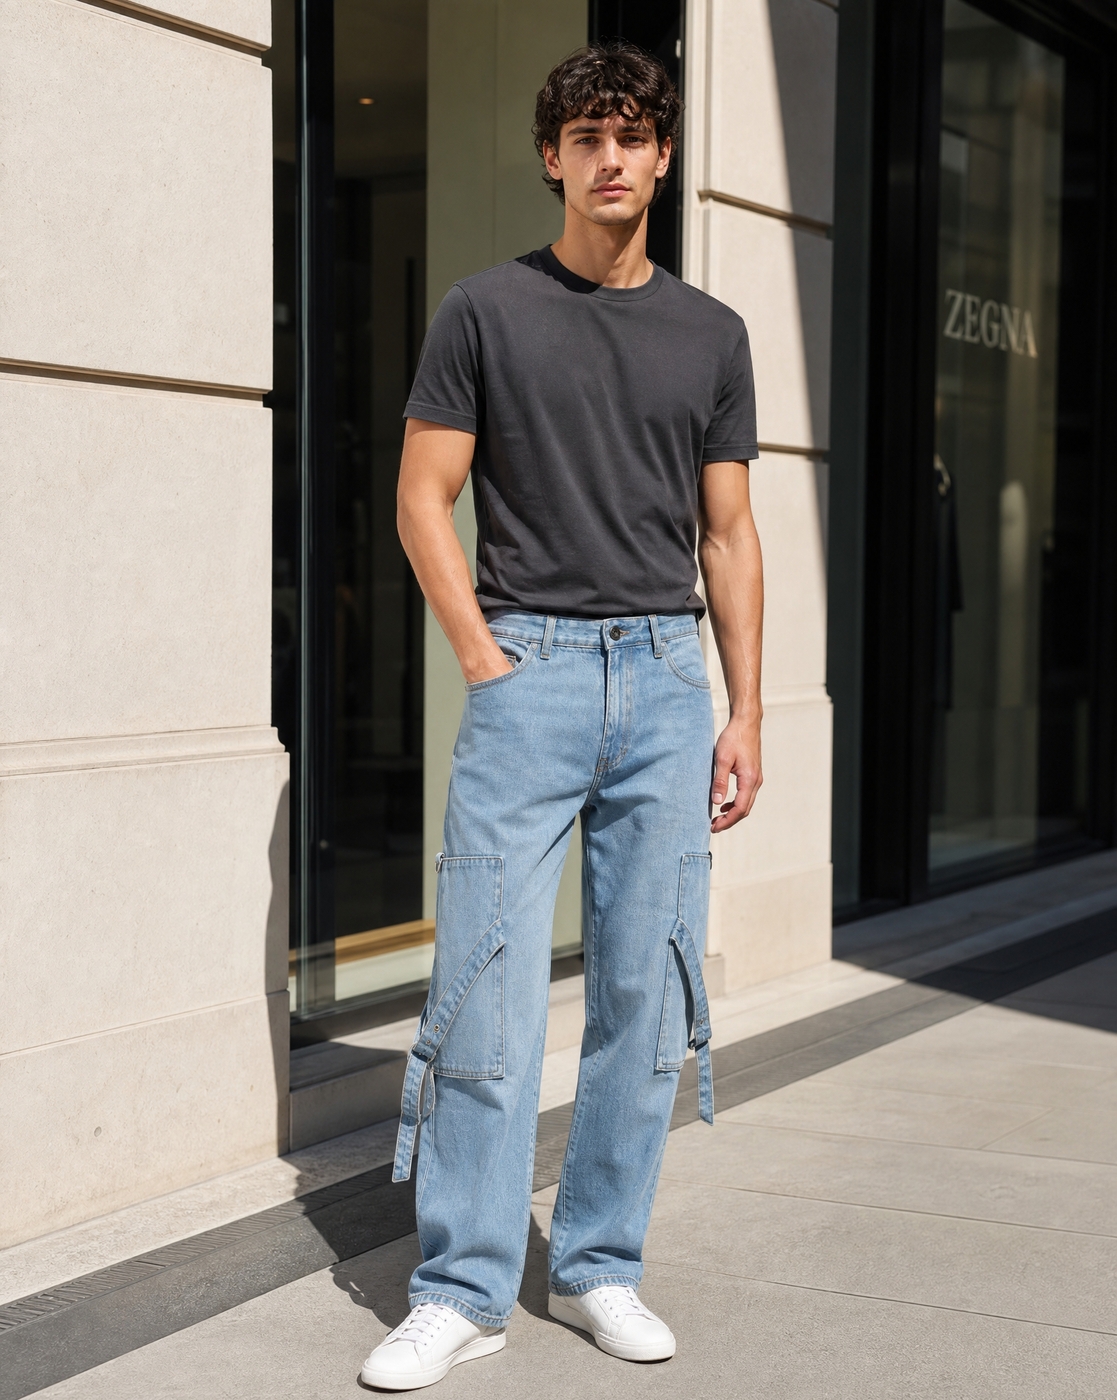
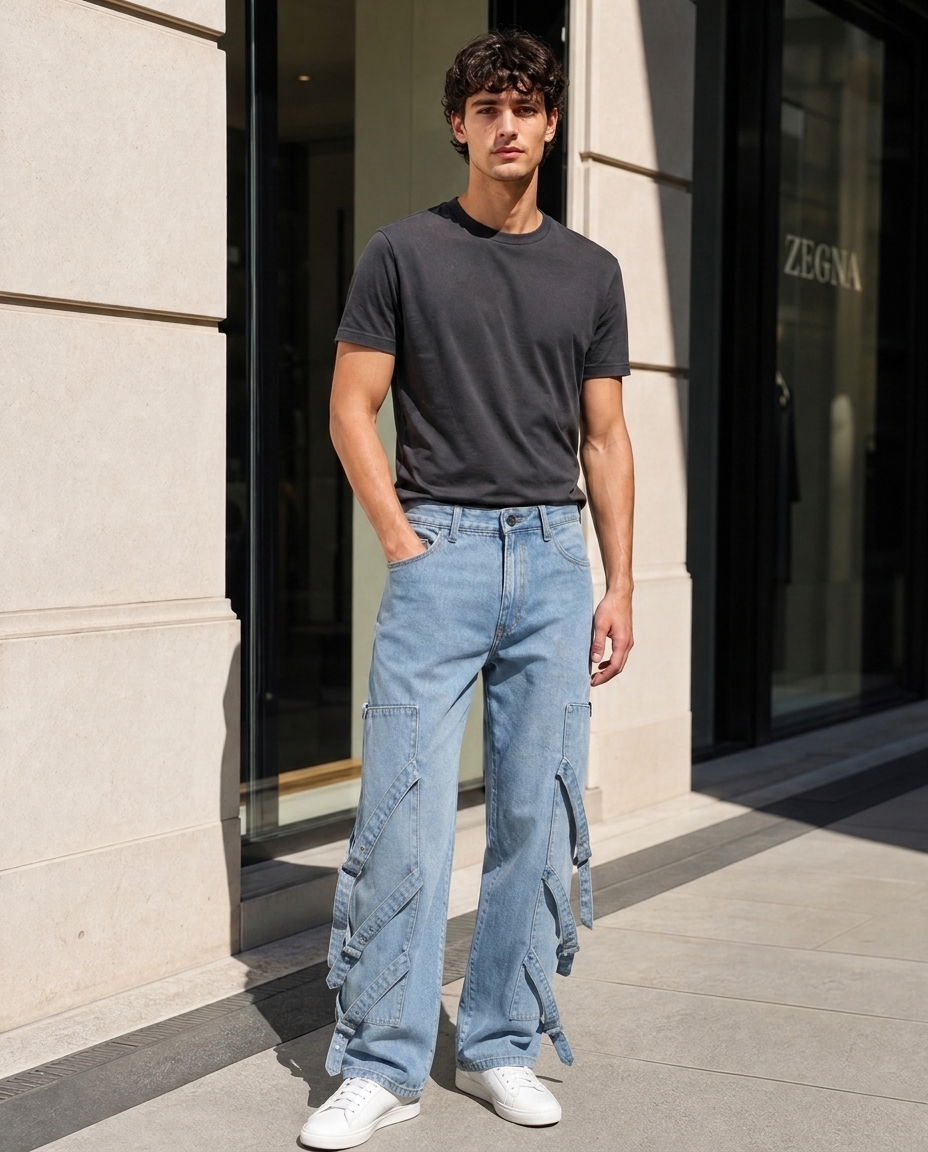
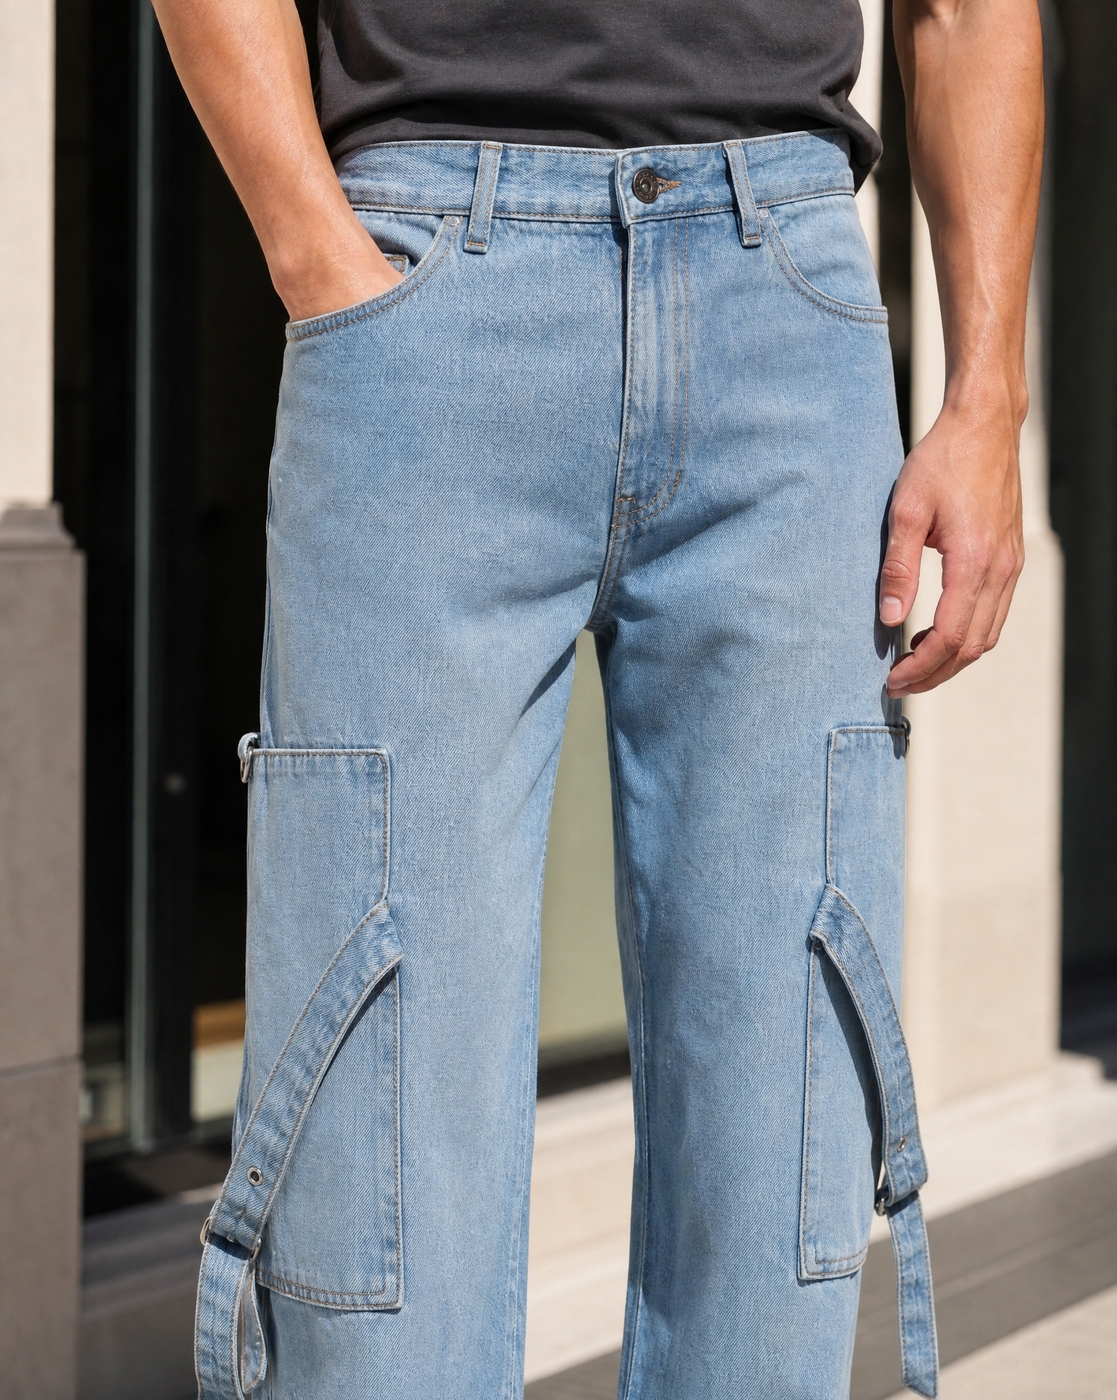
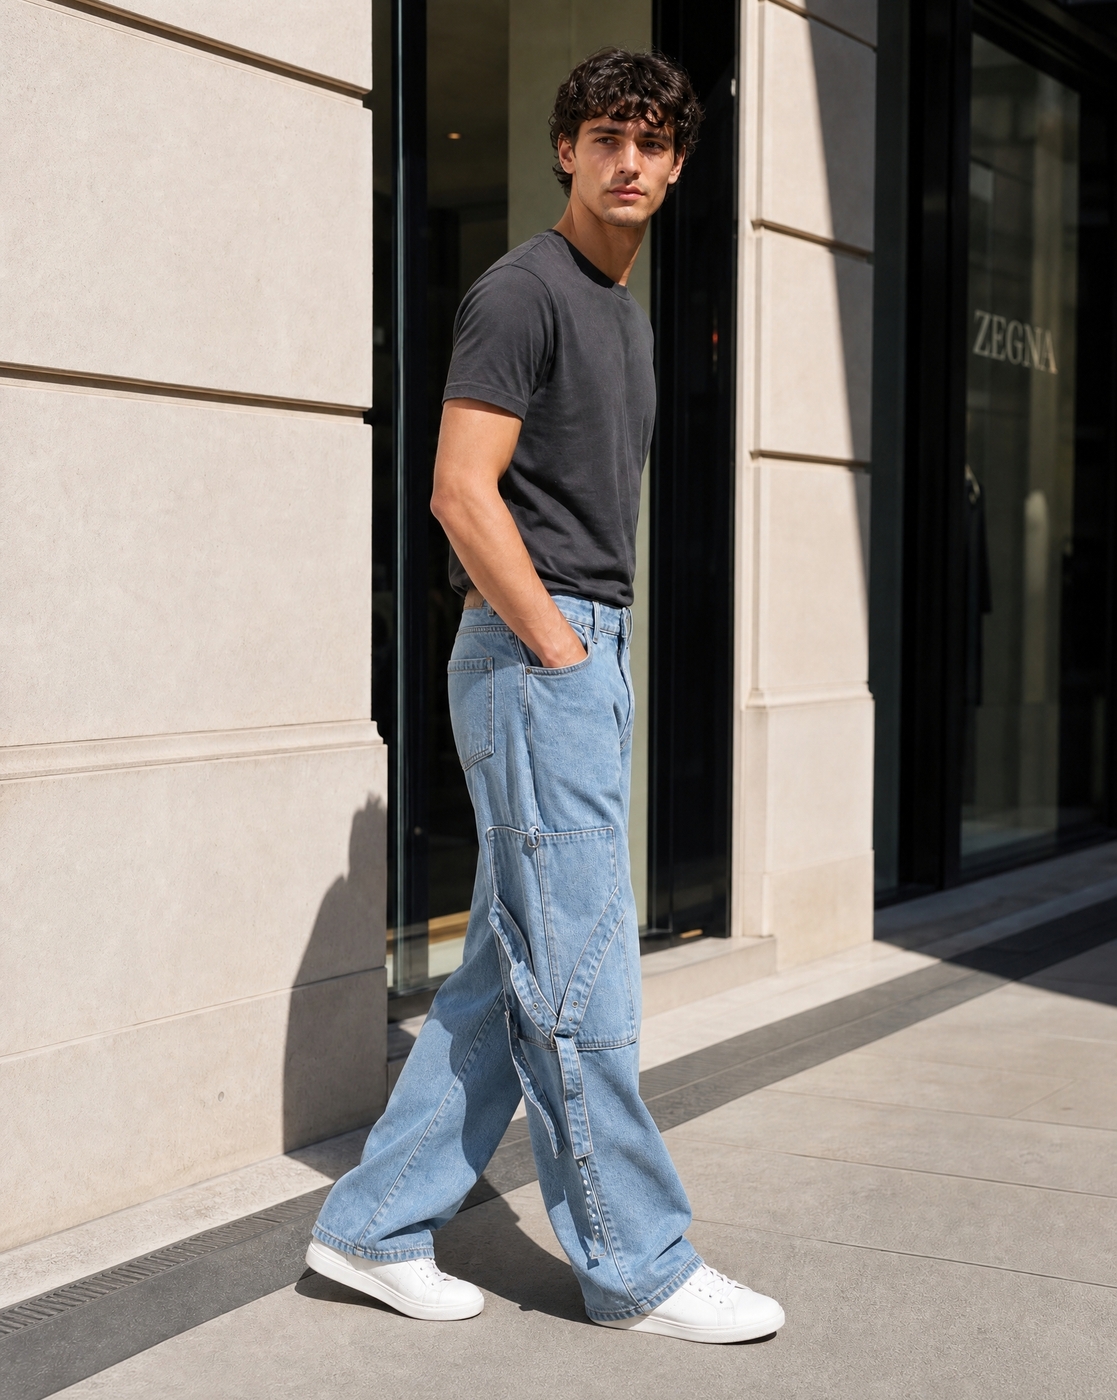
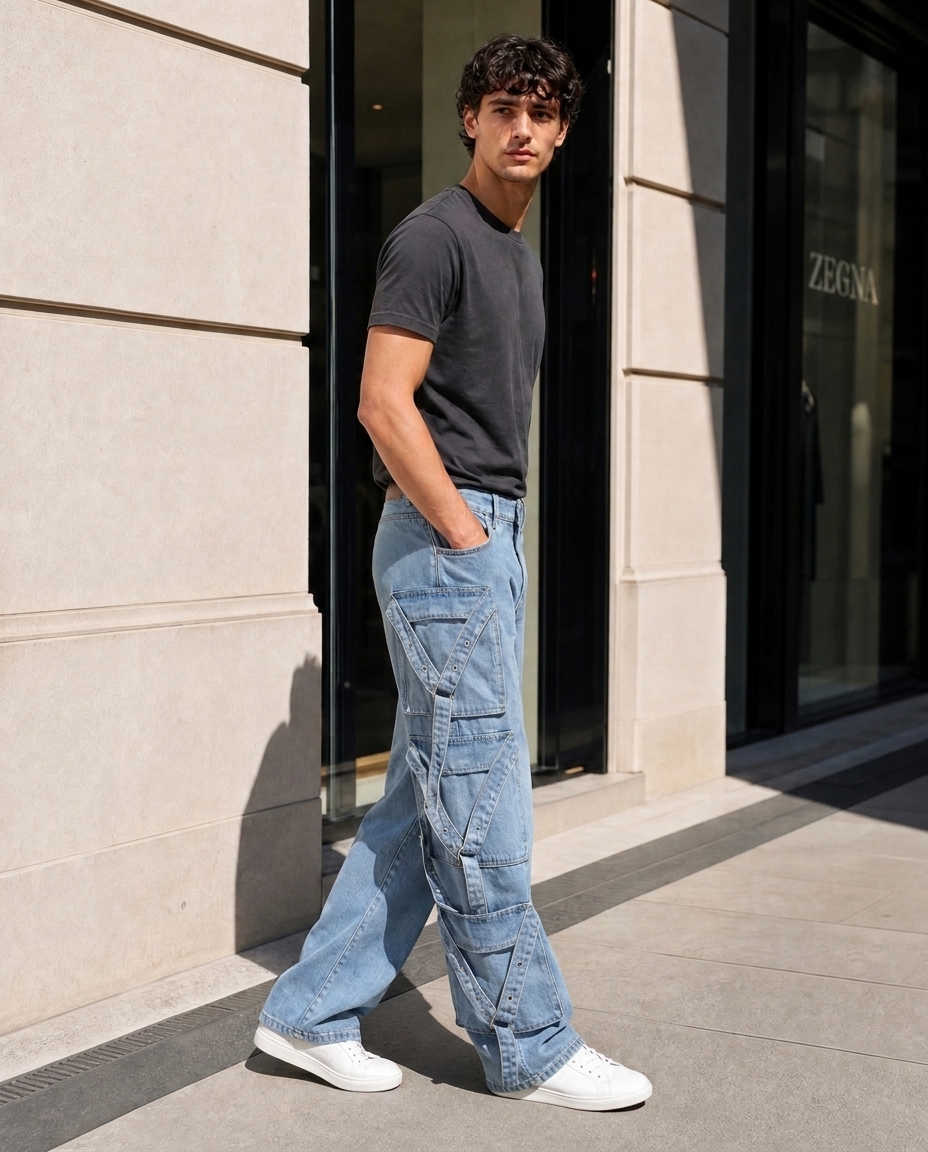
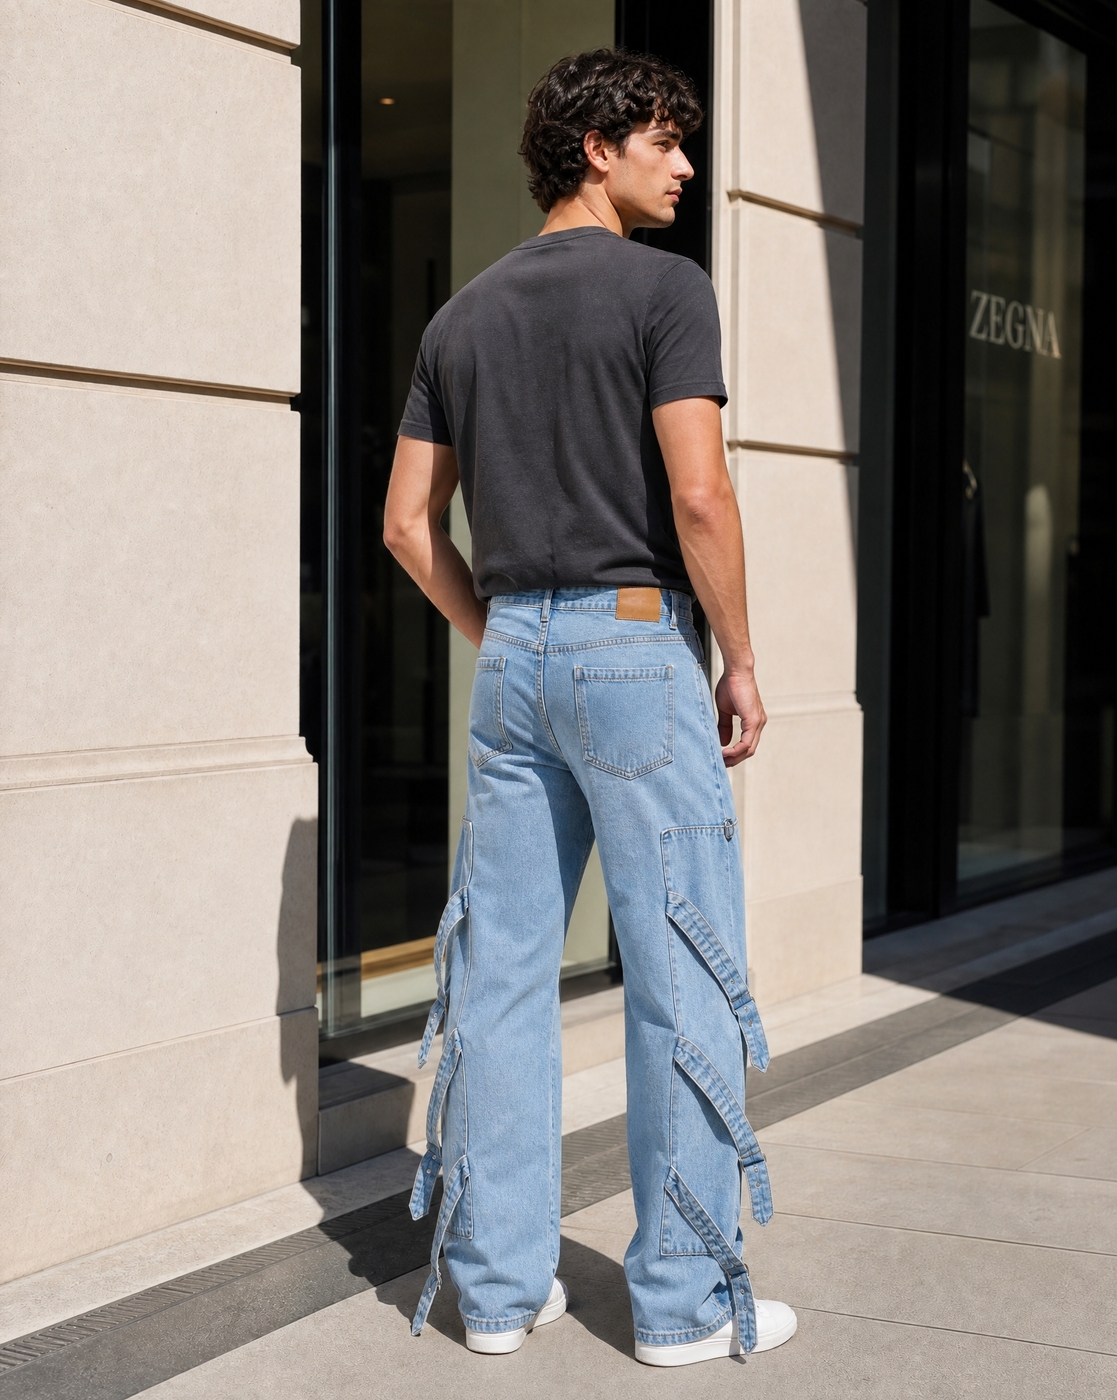
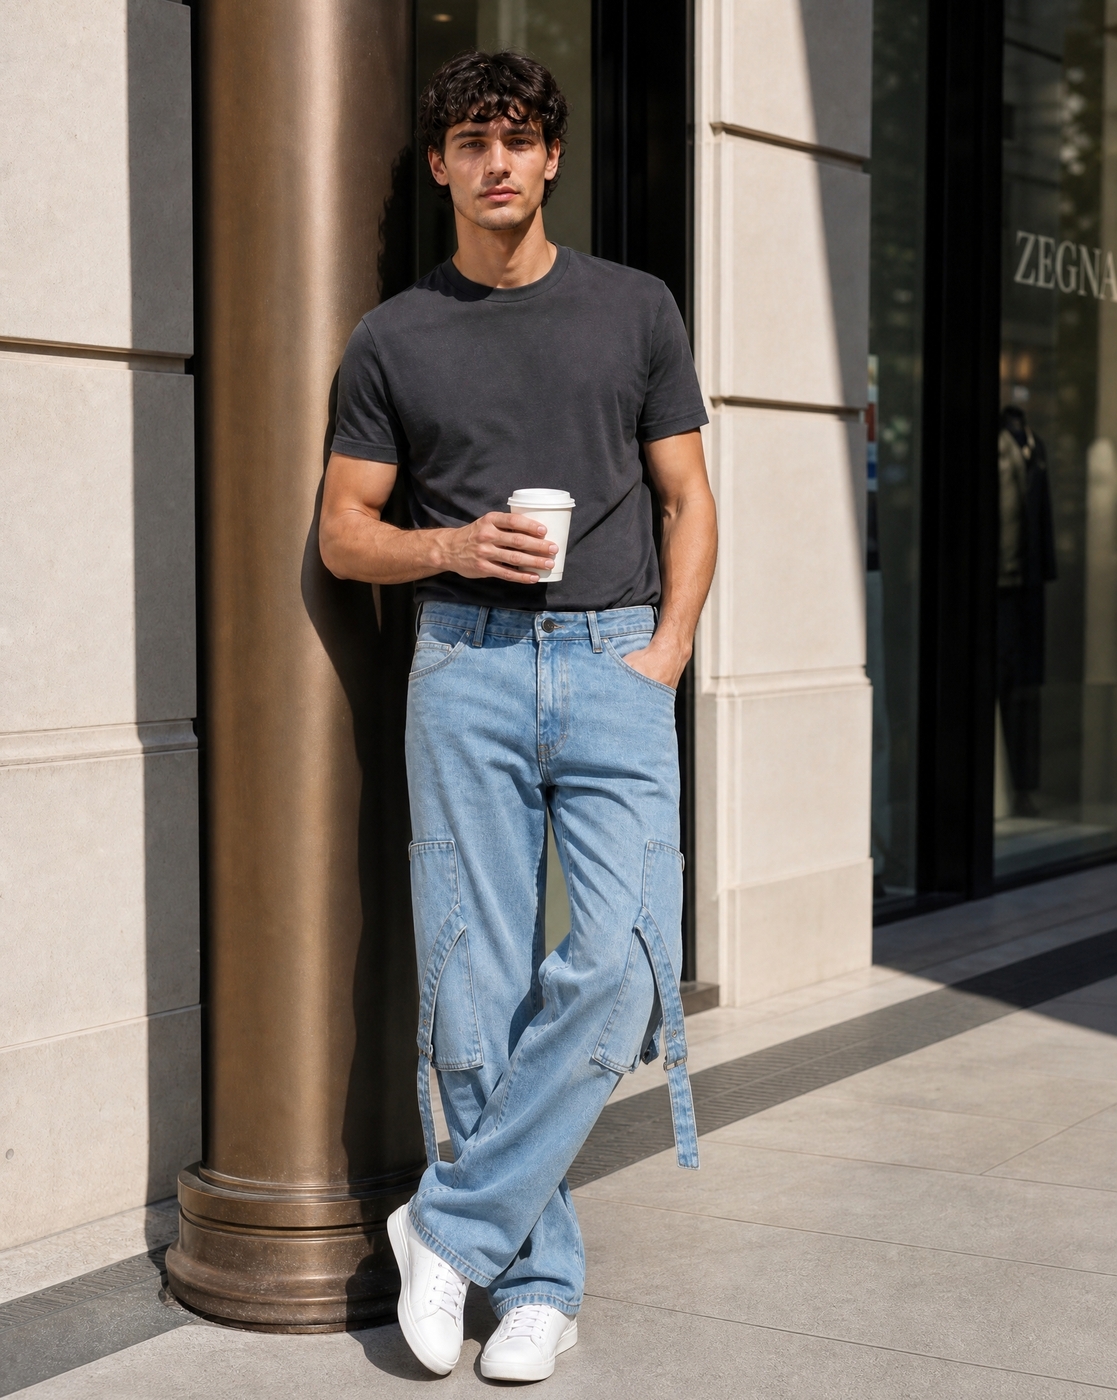
Light-wash cargo jeans with three stacked tiers of pockets and angled buckle straps on each leg. Two outputs kept only the top thigh pocket and dropped the lower tiers. The agent flagged both on garment consistency and regenerated them. A fifth output was flagged for adding pocket flaps, but the regenerated image was not committed and the original was kept.
Failure cases we still do not solve well
Three classes of defect remain difficult.
Exact studio backgrounds
Image models produce plausible backgrounds but miss exact colour requirements. For workflows that need a brand’s studio hex, a better system combines deterministic background generation, segmentation, compositing and shadow synthesis. This is where an LLM should route work to graphics code instead of insisting on generation.
Exact product positioning
Some brands require the product at an exact position or scale in the frame. This is geometry. A vision model can find the object; deterministic transforms should enforce the layout.
Denim and subtle fabric fidelity
Jeans remain unusually difficult. Small changes in wash, weave, distressing or seam treatment are commercially significant and hard for both generators and visual evaluators. We are exploring difference masks and region-specific checks.
Not every visual problem should be solved by adding another LLM call.
Why we think of this as a harness
We separate an agent prompt from an agent harness.
A prompt asks a model to behave in a certain way. A harness defines the environment in which that behavior becomes reliable. Ours owns state, rubric versions, the truth hierarchy, reference routing, structured schemas, verification, round and time budgets, termination, the run record, cost accounting, human escalation and rubric refinement.
The model is one component inside that environment.
For visual production, that changes the question from:
Which model is best at looking at images?
to:
What execution environment lets a strong model make reliable, auditable visual decisions over many steps?
The second question has led to far more of our improvements.
Results so far, and what is next
After running the system in production, we have seen three practical effects.
- More defects are caught before human review. Evidence-first checks moved coverage of historical reviewer complaints from roughly 32% to 39%. That is a harness change, not a model upgrade.
- Fewer hopeless edits are attempted. The planner refuses a meaningful share of targets before the image editor is called.
- Direct delivery has improved by roughly 20%. We treat that as an operational result, not proof that visual QA is solved.
The remaining cases are the hard ones: subtle textures, exact colour, ambiguous input evidence, and repairs where the image model cannot preserve enough of the original. Next on the list: rejection feedback and best-draft carry-forward in production, a set-aware commit rule, and a deterministic finishing stage for backgrounds and positioning.
Conclusion
What holds back visual generation for commerce is reliability, not a lack of beautiful images. A product image is useful only when the product is right.
The most important gains have not come from asking the model to “judge better”. They have come from making the environment around the model harder to cheat, harder to misunderstand, and easier to learn from.
The next generation of production AI systems will not be defined only by stronger generators. They will be defined by the harnesses that can tell when those generators are wrong.
Related work
This work is informed by a broader shift toward harness-centric agent systems: persistent state, programmatic execution, explicit verification, bounded long-horizon control, and reviewed continual refinement. A useful recent reference is Prime Agent: A Self-Improving RLM Harness by Karten et al. (2026), which frames the harness as the execution substrate that manages information, computation, persistence, verification, and refinement around a fixed model. We apply the same approach to high-volume image evaluation and repair, rather than coding or interactive reasoning.
The closest production system we know of is Uber’s, described in Building Closed-Loop Evals for a Multimodal Agent at Scale. Uber Eats uses a multimodal agent to improve food photos for independent merchants: better lighting, composition and colour, while keeping the merchant’s brand and staying true to the real dish. The shape is familiar:
- a routing agent decides whether a photo needs work or passes through as-is;
- an edit and QA loop gives feedback on things like portion size and plating, until the image meets the bar or hits an iteration limit;
- a diagnoser agent samples production data, compares agent outputs with human labels, and triggers prompt optimization as the data drifts;
- a “Swiss cheese” stack of redundant QA gates, with a final policy and safety check before anything reaches the menu.
Catalogue generation has more moving parts. A food photo is one image of one dish, judged against itself. A catalogue SKU is a set: several client photos as ground truth, five or more outputs that must agree on model identity, garment, paired garment, accessories and background, and many separate checks, each with its own method. That is why our harness adds things a single-image loop can skip: two judge passes that keep consistency apart from truth, per-edit choice of which source to trust, positive crop-level verification, and rubric versions that a human has to promote.
Notes on reported numbers
All percentages and cost figures in this article are production or offline measurements from the system version described here. The 30–45% unfixable figure comes from offline evaluations; the 32% to 39% figure is coverage of reviewer complaints on 100 production SKUs, not strict recall. Model versions, image pricing, rubric coverage, customer mix and workflow difficulty can materially change these numbers.